I kept the full technical walkthrough here so the main story could stay readable. You can read these notes in order, search for a topic, or jump straight to the glossary in note 60. The earlier experiments build toward 1.30×; note 63 covers the later official 1.3234× result.
- 01 The run that crossed 1.30×
- 02 What the competition actually asks
- 03 The complete competition map
- 04 From a message to generated tokens
- 05 Inside the transformer layer
- 06 Prefill, decode, and verification
- 07 One GPU inside an eight-GPU model
- 08 The software stack beneath SGLang
- 09 The mathematics of our projection
- 10 The exact projection workload
- 11 Numerical formats and error
- 12 Why the router needs special care
- 13 A guided tour of the H200
- 14 Threads, warps, blocks, and scheduling
- 15 The journey of a byte
- 16 Coalescing, tiling, and weight layout
- 17 Tensor cores and matrix instructions
- 18 Rooflines and practical limits
- 19 Split-K and the cost of combining work
- 20 Hopper pipelines and block clusters
- 21 The submission contract
- 22 What correctness really tests
- 23 How the judge times a kernel
- 24 How thirty timings become one score
- 25 Noise, uncertainty, and moving ranks
- 26 Building an auditable investigation
- 27 A correct kernel that lost
- 28 Split the router: our first useful win
- 29 Learning to dispatch by shape
- 30 Packed router: reaching 1.1555×
- 31 The attention side story
- 32 The routed-expert side story
- 33 Why whole-layer gains were smaller
- 34 Transposes, wider K, and QuACK detours
- 35 Systematic vector and library searches
- 36 Composing gains into 1.1993×
- 37 The handoff and the measured best-of plan
- 38 Atomic router: reaching 1.2785×
- 39 The small unpooler opportunity
- 40 Custom cluster QKV: reaching 1.2888×
- 41 Building our remote H200 laboratory
- 42 The packed pooler experiment
- 43 Exploring cuBLASLt orientations
- 44 Lossless compression: fewer bytes, slower execution
- 45 Router redesigns that did not help
- 46 Advanced features that still lost
- 47 The final single-token streaming gain
- 48 Read the winning implementation end to end
- 49 Local 1.3234×, official 1.3012×
- 50 What crossing 1.30× established
- 51 The epilogue: tuning can regress
- 52 The remaining road to 1.32×
- 53 From kernel wins to serving wins
- 54 Reproduce and audit the result
- 55 The decision-making playbook
- 56 Appendix A · Every experiment
- 57 Appendix B · All thirty shapes
- 58 Appendix C · Mathematical derivations
- 59 Appendix D · The source atlas
- 60 Appendix E · The glossary
- 61 Appendix F · Provenance and limitations
- 62 Appendix G · Pause and predict
- 63 Postscript · The official 1.3234× result
No matching chapter. Try another term.
I · The challenge and the model / 01
The run that crossed 1.30×#
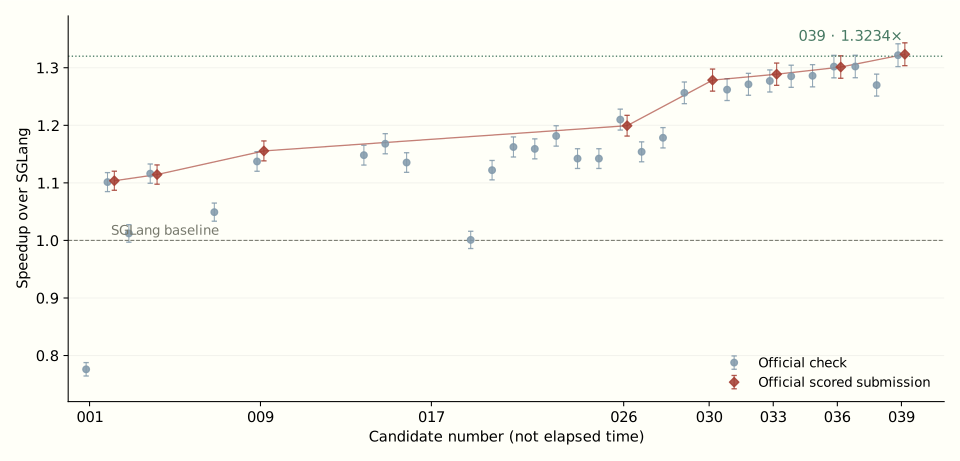
Here's the result I was aiming for, then the rewind to the version that was slower. A speedup below one means the baseline won.
Start with the evidence
The number on the screen is 1.3012. It is the official speedup of my dense projection submission over SGLang, not an estimate from my own benchmark. The independent check came back at about 1.302. This article is the story of how I got there. I will follow the mathematics, the hardware, the experiments, and the decisions. I will also follow the mistakes, because the first candidate was slower than the baseline, and several sophisticated ideas stayed slower.
What this victory actually measures
A speedup is baseline time divided by candidate time. At 1.3012, the corresponding time is about seventy 6.85 percent of the baseline. That is approximately twenty 3.15 percent less time. It is not thirty percent less time, and it is not a claim that the entire model serves users thirty percent faster. The competition aggregates several projection workloads. Later I will reconstruct that aggregation and identify exactly where the gains appeared.
Rewind to a disappointing first result
My first recorded candidate passed correctness and checked at 0.7761× the baseline. Correct arithmetic had not made it a competitive kernel. One important diagnosis in the research notes was insufficient parallel work. Some GPU resources were waiting while the available blocks performed long reductions. The lesson was uncomfortable but useful: a more compact implementation can still use the machine less effectively. That finding set up the split router experiment, rather than a celebration of fusion for its own sake.
The path was a branching investigation
The progress line looks smooth only after I choose which results to draw. The actual work branched into vector kernels, split reductions, transposed weights, packed weights, library algorithms, custom CUDA, compression, and new reduction schemes. Some branches failed to execute. Others passed every arithmetic test and lost on time. I will keep those distinctions visible. When the available record supports a decision, I will explain it. Where I reconstruct the rationale from code and measurements, I will say so instead of inventing private deliberations.
The result that almost fooled me
Near the end, my local comparison against SGLang measured 1.3234. That looked as though the later 1.32 target had been reached. It had not. The official scored submission was 1.3012. Measurement conditions, paired ratios, and run variation matter when the remaining gap is small. This is why the article treats the local result as useful evidence for investigation and the official result as the competition outcome.
How to watch the investigation
I will repeatedly ask seven questions. What was slow? What did I think caused it? Why was the proposed change plausible? What changed in the implementation? Did correctness survive? What did the measurements establish? And what decision followed? The first part builds the vocabulary needed to answer those questions. The middle follows my experiments in order. The final part reads the winning design and shows how to reproduce and challenge the result. You do not need to arrive already knowing CUDA. The visual grids are schematic: small groups of cells illustrate a subset of a larger tensor or machine, rather than its literal unit count. Measured results are identified separately. The main story reconstructs my 1.30 milestone. A later official 1.3234 result arrived during production and is documented separately in the postscript.
I · The challenge and the model / 02
What the competition actually asks#
Before writing a faster kernel, I needed to know what counted as a valid submission and what the competition actually measured.
Two related competitions
The Open Kernel Challenge asks competitors to make Muse Spark Open run faster. There are two related stages. In the kernel stage, a submission replaces a particular computation and is compared with the corresponding SGLang baseline. In the serving stage, a submission modifies the serving system and runs the whole model on an eight GPU node. A faster isolated kernel can help the serving system, but the two stages measure different outcomes. Understanding that distinction prevents me from optimizing a leaderboard number and assuming the same gain for a user's request.
What I submit
For a kernel problem, the central artifact is one Python file defining the required entry point. It may call supported libraries, launch Triton, or compile native CUDA inside the file. The environment is a specified SGLang image. It does not provide network access for installing arbitrary new packages during evaluation. A design therefore has to work with the software that is actually present, and compilation has to fit within the run's time limit. My native extension choices were made inside those practical boundaries.
Checks and scored submissions
An official check runs the correctness and timing path without putting the candidate on the leaderboard. A scored submission makes a leaderboard attempt. Both consume separate daily allowances, which the service can change with load. The local command reporting current limits is more reliable than a number remembered from an earlier day. I used checks to investigate changes and scored submissions to establish results. An attractive checked score is still labeled checked throughout this article, even if a nearby version was later submitted for scoring.
The calendar and the prizes
At the schedule checked for this project, the kernel stage closes on November fourth, 46, at 70 in the evening Pacific time. The serving stage opens November fifth at noon and closes November nineteenth at 70 in the evening. The cash prizes are awarded in the serving competition. Kernel standings can provide priority access to the serving queue. So the original question about November fifth mixed a kernel deadline with the start of a different stage. Dates and rules should be rechecked before a real deadline.
What a legal improvement preserves
The challenge is designed to find improvements that could be used upstream. Required computations and numerical contracts must remain intact. Repacking static weights is allowed, and lossless compression can be allowed, but replacing required precision with an arbitrary cheaper format is not the task. Fresh evaluated inputs must produce fresh outputs. The rules also exclude manipulating the timing process or caching evaluated answers. These requirements are not administrative extras. They define the optimization problem: achieve the same specified computation through a better implementation.
How to read competitors’ scores
A leaderboard tells me that a result was achieved under the evaluation rules. It does not tell me which algorithm, assembly instruction, or tuning strategy produced it. I can use other scores to understand the competitive gap, but I cannot honestly attribute a particular design to another team without source evidence. Rankings also move as more teams submit. The film will date historical ranking snapshots and concentrate on what my own artifacts establish. That keeps competitive intelligence useful without turning guesses into a technical explanation.
I · The challenge and the model / 03
The complete competition map#
The challenge has several related problems. This is the map I used to keep a projection win separate from an attention or whole-layer win.
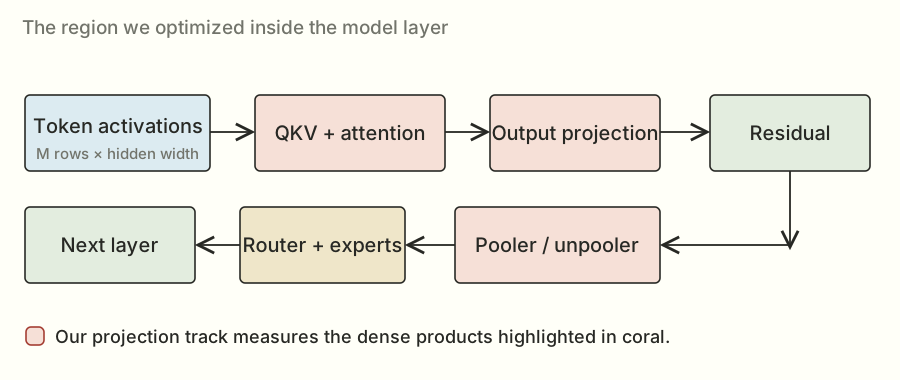
A map of the five problems
The competition separates a model layer into several opportunities. Dense projections cover matrix products around attention and the expert block. Attention decode covers the interaction between queries and the cached context. Routed experts cover the selected expert computations. The whole decoder layer joins those pieces with normalization, residual updates, and routing. Prefill runs a whole layer on larger prompt-processing shapes. These are related computations, not five unrelated puzzles. I will use one model diagram and repeatedly highlight the region each problem measures.
Dense projections: my main storyline
My 1.30 result belongs to dense projections. The operation is an input matrix multiplied by a transposed weight matrix. Four weight families are BF16, and the router weights are FP32. The workload contains single-token decode, larger decode batches, and speculative verification batches. Although the equation is the same, the geometry changes the best implementation. Much of the investigation was learning where a direct vector reduction, a custom tensor-core kernel, or a library matrix product deserved to run.
Attention decode: a growing history
Attention decode takes newly produced queries, keys, values, and gate information, then works with a paged key and value cache. Some layers attend over a sliding window, while others attend over the full available context. Preparation, cache writes, the attention calculation, merging partial results, normalization, and gating all contribute work. A long-context attention kernel can spend most of its time reading cached values. That changes the optimization question from merely making a matrix multiplication fast to organizing reuse, parallelism, and reductions across a large history.
Routed experts: irregular work
The expert problem selects eight of 256 experts per token. One GPU holds its local expert shard. The routing distribution is deliberately uneven, so some experts receive much more work than others. The computation includes two expert matrix products, the SwiGLU activation, and output normalization before weighted combination. Here the dimensions of each expert batch vary. Efficient grouping, padding, alignment, and dequantization can matter as much as a fast individual matrix multiplication. A square dense benchmark would hide those difficulties.
The whole decoder layer
The whole-layer problem includes projections, attention, expert routing, expert computation, normalizations, and residual updates. It exposes a common trap: independently faster components do not imply the product of their individual speedups. Their original shares of total time differ, integration can introduce extra materialization, and the actual execution path may differ from a standalone test. My whole-layer result improved, but it was smaller than the strongest component results. That makes it an important part of the story rather than an inconvenient number to omit.
Prefill and the separate board
Prefill handles many new prompt tokens, including large chunks and continued long conversations. Larger matrix dimensions offer much more reuse of weights than single-token decode, and grouped expert products become prominent. The supplied task states that prefill has its own board and does not contribute to the overall decode board. I will explain it so the competition map is complete, while keeping it separate from the projection accomplishment. This distinction also explains why optimizing the largest-looking kernel is not automatically the best route to a particular ranking goal.
I · The challenge and the model / 04
From a message to generated tokens#
Start with the message you type. I'll follow how it becomes token IDs, numbers inside the model, and eventually the next piece of text.
Text becomes a sequence of IDs
A language model does not read a paragraph as a single object. A tokenizer converts it into token identifiers. A token may represent a word, part of a word, punctuation, or another learned text unit. The identifiers select embedding vectors, which become the numerical input to the model. The important systems consequence is that a conversation becomes arrays with concrete shapes. Once those shapes and formats are fixed, GPU kernels perform arithmetic on them. My optimization work begins far below the level of the original words.
Parameters versus activations
Parameters are the model's learned values, including the weight matrices. Activations are intermediate values produced for a particular request. During inference, these weights are mostly reused across many calls, while activations change as new inputs arrive. That difference creates an important opportunity: prepare static weights once in a useful layout, then consume them efficiently for fresh activations. It also creates a boundary. Anything derived from an evaluated activation belongs to that invocation's computation; it cannot be treated as a reusable model constant.
A layer transforms representations
Each transformer layer takes a representation and changes it using attention and a feed-forward or expert block, with normalization and residual connections around those operations. The vector width describes how many features represent each token. A projection mixes those features by multiplying by learned weights. The matrix product does not understand English; it computes weighted combinations of numerical features. Thinking at that level helps me separate the required mathematical transformation from the many possible ways to schedule its arithmetic on the hardware.
Why the key/value cache exists
During generation, previous tokens' keys and values would be expensive to recompute at every step. The system stores them in a key and value cache. New queries attend to that stored history according to the layer's attention pattern. The cache grows with context, while the new activation at a single decode step may be tiny. This explains an apparent paradox: generating one new token can still require reading substantial GPU memory. Small new input size does not imply a small amount of total work.
Logits and the next token
After the layers, the model produces logits representing scores for possible next tokens. A sampling or selection procedure chooses a token, and the next generation step begins. This autoregressive dependency limits how much work one request can expose at once: the next step depends on the previous output. Serving systems therefore batch multiple requests and can use speculative decoding to expose more work. Those systems choices directly create the small and medium token counts seen in my kernel shapes.
Where a kernel speedup can matter
Imagine a request spends only ten percent of its time in a computation I make twice as fast. The request does not become twice as fast. That portion falls from ten time units to five, while the other ninety remain. Total time becomes 95, for only about a five percent improvement. I will formalize this as Amdahl's law later. For now, remember that a kernel's importance depends on both its own performance and how much of the real system's time it occupies.
I · The challenge and the model / 05
Inside the transformer layer#
A model layer is a sequence of calculations. Here I unpack the names so the projection kernels have somewhere to live in the bigger story.
The fused QKV and gate projection
The attention side starts with a projection that produces queries, keys, values, and gate information. These names describe different roles, even when a single matrix product computes them together. Queries ask what information a token needs. Keys provide features used to score relevance. Values provide the information to combine. The gate later modulates the attention output. Under the specified tensor-parallel partition, my local fused projection has a particular output width. The correct kernel must preserve that local arrangement so later operations read the right slices.
Normalization and position
Queries and keys are normalized according to the layer's definition. Sliding-window layers apply rotary positional information, often called RoPE. Then new keys and values are written into the cache in its specified format. These operations sit between the projection and the main attention calculation. They can be small individually yet costly as separate launches. That is why an attention preparation fusion can be useful even without changing the main attention algorithm. But the fusion must preserve scaling, rounding, positions, and cache addressing.
Attention combines the history
Attention compares the new queries with eligible cached keys, applies a softmax to the scores, and uses the resulting weights to combine cached values. The word eligible matters. A causal mask excludes future positions, and a sliding-window layer restricts the history to its window. A full-attention layer keeps the full specified history. An optimization cannot simply skip inconvenient keys or replace the softmax with an approximation outside the rules. The task is to organize all required work more efficiently.
Gating, output projection, and residuals
The attention result is normalized and multiplied by a sigmoid gate, then projected back through the output matrix. Residual updates combine the new contribution with a continuing representation, using the scales and normalizations in the model definition. These surrounding operations explain why an isolated projection result has a narrower meaning than a whole-layer result. They also create potential fusion opportunities, because an intermediate tensor written by one kernel may immediately be read by another. Whether fusion helps depends on dependencies and hardware resource use.
Router, pooler, and local experts
The router produces scores used to select the top eight experts. The expert input is formed through the pooler projection and normalization. Only routes to experts local to this GPU are computed in the isolated expert workload. Each selected expert applies its first learned projection, a SwiGLU transformation, and a second projection. The expert output is normalized and weighted by its route contribution. Uneven routing creates uneven batches, so the execution problem is an irregular collection of matrix products rather than one uniform large GEMM.
Unpooler and the next layer
The expert result is projected through the unpooler and merged into the residual path. A final normalization prepares the representation for subsequent work. At small token counts, the task specifies a special local unpooler slice, which is why a tiny matrix product becomes relevant in my optimization story. I now have the complete loop: attention changes what a token reads from history, and routed experts transform the resulting features. The dense projection challenge isolates five matrix products along that path.
I · The challenge and the model / 06
Prefill, decode, and verification#
Reading a prompt and generating the next token create different jobs for the GPU. That difference explains a lot of the shape-specific choices later.
Prefill exposes many token rows
When a prompt first arrives, or a conversation adds a block of new text, the model can process many new token rows together. Causality still constrains attention, but the projections can reuse the same weight values across many rows. The matrix's token dimension is therefore large compared with single-token generation. A larger matrix product often makes tensor-core reuse and high arithmetic throughput more valuable. It also changes expert batch sizes and the cost of preparing irregular grouped work. This is why prefill needs its own performance analysis.
Decode can starve a large GPU
A single autoregressive request normally supplies one new token per decode step. Its projection is a matrix-vector-like computation: many weight values contribute to a small output. There may be enormous total data movement but few useful token rows. A kernel designed around large square matrices can waste work or expose too little parallelism here. Serving multiple requests together increases the token dimension, but latency requirements limit how long the system can wait to collect a larger batch.
What speculative verification changes
In speculative decoding, a drafter proposes several tokens and the main model verifies a block. The workload described here uses eight-token verification blocks. With sixteen requests, that creates 128 token rows for the projection. With 32 requests, it creates 256 rows. The verification attention remains causal within the block. The larger projection shape offers more weight reuse, which is one reason its best kernel can differ from the best one-token kernel.
My six effective M values
For the projection task, the six scored effective token counts are one, sixteen, 32, eight, 128, and 256. They correspond to three decode loads and three verification loads. The ordering reflects workload names rather than numerical sorting. For each load, five projection families are timed. That produces thirty scored cases. A dispatch policy must handle those cases and nearby shapes sensibly, because final review also examines generality rather than accepting a design that behaves well only at six isolated numbers.
Why M changes arithmetic intensity
Ignore activation and output traffic for a moment and suppose each BF16 weight is read once. The matrix product performs approximately two times M times N times K floating-point operations and reads about two times N times K weight bytes. Dividing gives roughly M operations per weight byte. This is a useful first approximation: increasing M creates more arithmetic for each weight value fetched. It is not a complete performance prediction, because launch costs, other traffic, cache reuse, and implementation choices still matter.
The consequence for my strategy
I did not treat the six loads as scaled copies of one problem. Single-token kernels needed efficient streaming and reduction. Small batches needed enough independent work without excessive split overhead. Larger verification shapes could benefit from library tensor-core implementations and better layouts. The resulting source looks less elegant than a single universal kernel, but it reflects the machine's changing constraints. The important requirement is that the dispatch depend on legitimate shapes and configuration, with correctness and performance checked around the selected ranges.
I · The challenge and the model / 07
One GPU inside an eight-GPU model#
The full model runs across eight GPUs, but my kernel experiments run one GPU's local work. Here's how those two views fit together.
The model is partitioned
The workload comes from serving the model across eight H200 GPUs. Tensor parallelism divides parts of tensor computation across devices. Expert parallelism distributes experts across devices. These are different partitioning ideas, although the serving setup uses both. A single GPU's local matrix dimensions therefore need not equal the full model's dimensions. When reading my projection shapes, remember that they describe the local work specified by the task, not a complete unpartitioned layer running on one device.
Column and row partitions
A matrix multiplication can be partitioned by output features or by a reduction dimension. Splitting output features lets devices compute distinct output slices. Splitting a reduction dimension creates partial results that normally need combination. Which communication follows depends on the model's parallel layout. The isolated task specifies what this GPU computes and how communication is represented. I must not infer an all-reduce that the evaluator does not request, or omit a local computation because another GPU would normally participate in the production system.
Where the experts live
The expert workload describes 32 local experts out of 256, consistent with eight-way expert parallelism. Every input token arrives, but this GPU computes only routes to its local experts. The routing is skewed, and the cases make this GPU the busiest shard. This avoids a falsely easy benchmark where the measured GPU happens to receive very little work. It also means a local kernel must handle unequal expert counts rather than assume the input is divided evenly among experts.
What the isolated layer leaves out
The supplied whole-layer task models communication as the identity on this GPU's partial result, as though the other devices contribute nothing. That isolates local computation. It does not imply that real distributed inference has free communication. Network transfer, collective synchronization, and scheduling remain relevant in the serving stage. This separation is useful for comparing kernels, but it limits the claim I can make from an isolated score. A local optimization may move the full system's bottleneck toward communication rather than improve overall throughput proportionally.
The special unpooler slice
For the small-token projection cases, the unpooler's local output width is 1,024 rather than its larger full local width of 8,192. The task explicitly describes this slice. That reduces how much weight data and output work the kernel must handle. It helps explain why a tiny GEMM route was attractive. Treating this shape as an accidental benchmark quirk would be a mistake: the required local computation itself changes, and a correct implementation follows that specified shape.
What I can conclude from one device
From the kernel evaluation, I can conclude that a candidate computes the required local outputs within tolerance and achieves its reported local-workload score. I cannot conclude the same speedup for an eight-device request, or for arbitrary model shapes. To make that larger claim, I would need a serving evaluation with communication, scheduling, latency, and throughput included. Keeping the scope precise does not diminish the kernel accomplishment. It tells me what experiment has actually been performed and what experiment remains necessary.
I · The challenge and the model / 08
The software stack beneath SGLang#
There are several layers of software between Python and a GPU instruction. This is a tour of the tools, starting with what each one does.
A framework call is not a hardware instruction
At the top of the stack, SGLang manages serving work and invokes computations. PyTorch provides tensor operations and memory abstractions. Those operations eventually launch GPU kernels. A line such as matrix multiplication may dispatch into a highly optimized library implementation rather than execute a simple loop. That is why replacing a short PyTorch expression with much more custom code is not automatically a performance improvement. The original expression may already select excellent hardware-specific code for a particular shape.
Triton and native CUDA
Triton lets me describe blocks of tensor work in Python-like code and compile them into GPU kernels. Its compiler chooses instruction and data layouts subject to the program and launch parameters. Native CUDA gives more direct control over threads, shared memory, assembly instructions, and launch features, at the cost of more implementation complexity. My final source uses both styles. A useful mental model is to ask what control a particular experiment needs, rather than assume either language is intrinsically the faster option.
cuBLAS and cuBLASLt
cuBLAS supplies optimized linear algebra routines. cuBLAS Lt exposes additional choices around matrix multiplication layouts, algorithms, workspace, and related configuration. A default library call applies a dispatch policy; an explicit plan can explore alternatives. This is still genuine implementation work when I preserve precision and the computation. The important questions become which operand layout the library sees, which algorithm it selects, whether its reduction scheme preserves the required precision, and whether the plan remains sensible on nearby shapes.
Specialized libraries
FlashInfer supplies inference-oriented kernels and includes the tiny GEMM route used in my small unpooler path. Marlin appears in the expert baseline's low-bit matrix products. DeepGEMM, CUTLASS, and QuACK offer other specialized building blocks or kernel designs. Their names describe capabilities, not performance guarantees for every shape. A library can be excellent in its intended regime and lose on the exact skinny matrix or small batch in this challenge. The investigation therefore compared actual captured execution rather than choosing by reputation.
Version and API details can decide an experiment
An implementation can fail before timing because a low-level API expects a different operand rank or layout. That happened in the QuACK branch: the split-K path needed batched rank-three operands. Repairing the integration with unsqueezed views made the experiment executable without copying or changing values. Only then could performance be evaluated. I will keep that sequence separate from the question of whether QuACK was fast. An API mistake is evidence about integration, not evidence that the underlying algorithm is slow.
Read the installed implementation
The evaluation environment is pinned, while online libraries continue to change. I used installed source and version-specific references to understand the actual functions available. That is especially important for optional Hopper kernels and low-level matrix multiplication interfaces. A tutorial for a newer release can suggest a useful idea and still give the wrong call signature for the judge image. Reliable optimization work connects each code choice to the environment in which it will execute, then validates the result there.
I · The challenge and the model / 09
The mathematics of our projection#
A projection is a collection of weighted sums. I'll build up the matrix notation from that idea and explain what M, N, and K count.
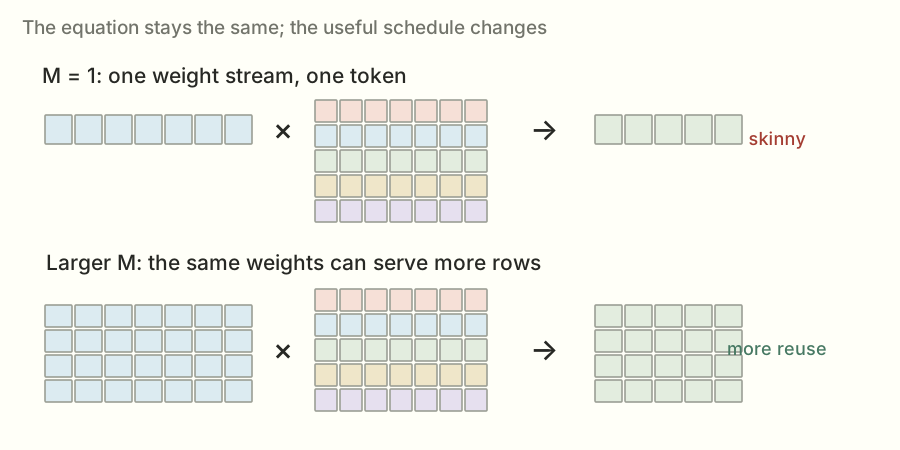
One output is a dot product
Take one token's feature vector and one output feature's weight vector. Multiply matching entries and add the products. That sum is one output value. Repeat for every output feature and token row, and I obtain the projection matrix. If the input has M token rows and K input features, and the stored weights have N output rows and K columns, the output has M rows and N columns. This is the meaning of input times weight transpose. The transpose aligns the shared K dimension; it need not imply a physical copy.
The operation count
Each output contains roughly K multiplications and K additions. Across M times N outputs, the conventional floating-point operation count is approximately two M N K. This count helps estimate arithmetic cost, but it does not describe memory transactions, launch overhead, or reductions introduced by a particular kernel. Two implementations can perform almost the same useful arithmetic while moving very different numbers of bytes. Conversely, a method that performs some padded arithmetic can still win because it uses tensor-core hardware more effectively.
Strides tell me where values live
A tensor's shape says how I index it; its strides say how an index maps to memory. A contiguous row-major weight matrix stores adjacent K values together within each output row. A transposed view changes the indexing interpretation without moving values. A contiguous transpose physically rearranges values. A packed layout can go further by arranging tiles in the order a kernel wants to read them. These transformations preserve the mathematical weights when they are lossless, but they can change both memory coalescing and library dispatch.
GEMV and skinny GEMM
At one token, the input is effectively a vector, so the projection resembles a matrix-vector product. At a few tokens, it is a skinny matrix multiplication. At larger token counts, weights can be reused across more rows. A single-token kernel might stream weight rows and reduce them directly in registers. A tensor-core kernel groups many products into tile instructions. A library may choose yet another schedule. The equation does not tell me which implementation wins; the shape and machine constraints influence that choice.
Different reduction orders
In exact real arithmetic, splitting a dot product into partial sums and combining them gives the same answer. Floating-point arithmetic is finite, so changing the summation order can change rounding. Split-K, atomics, and different tensor-core tile schedules can therefore produce slightly different outputs even while retaining the required formats. The challenge's numerical tests define what is acceptable. I preserve the required precision and validate actual outputs, rather than assume algebraic equivalence guarantees identical machine results.
Equivalent products, different execution
The identity relating a product and its transpose lets me exchange how a matrix multiplication is presented to a library. Computing a transposed output and returning a view can sometimes expose a faster algorithm. But output strides, alignment, dimensions, and downstream expectations matter. I explored these orientations explicitly and later added alignment-based fallbacks. This is a recurring theme: a mathematically simple identity can open a useful implementation branch, while the practical details determine whether it is a robust optimization.
I · The challenge and the model / 10
The exact projection workload#
These are the actual sizes the projection benchmark tested. Think of a shape as the dimensions of one particular job.
QKV and the output projection
The local QKV-and-gate weight has 2,304 output rows and 8,192 input features. In BF16, its weight payload is about thirty 7.7 megabytes in decimal units. The output projection has 8,192 output rows and 1,024 input features, about sixteen point eight megabytes. These sizes explain why even a single token can require substantial weight streaming. The small activation does not make the weight matrix disappear.
Pooler and unpooler
The pooler has 4,096 output rows and 8,192 input features. The full unpooler has 8,192 output rows and 4,096 input features. Each contains about sixty 7.1 megabytes of BF16 weights. For token counts up to eight, the specified unpooler projection only returns its 1,024 output slice, substantially reducing the weight rows it needs. A kernel should read the requested slice rather than automatically stream the whole matrix.
The FP32 router
The router has 256 output features and 8,192 input features. Its stored weights are FP32, about 8.4 megabytes. The output is also FP32, unlike the dense projection outputs, which are BF16. Although the router matrix is smaller than the pooler, its stricter numerical contract and low output-feature count make its kernel design interesting. At small token counts, enough parallelism can be difficult to expose without splitting the reduction.
Thirty scored cases
Each of the six loads times all five projection families. Within a load, each shape has the same listed weight, 62, corresponding to repeated layer work in the model. That common factor cancels in the load's speedup ratio, but the individual projection times do not. A one-microsecond saving on a twenty-microsecond pooler and a one-microsecond saving on a five-microsecond router contribute the same absolute reduction to that load's time. Comparing percentage improvements alone can therefore mislead my priorities.
Nominal lower bounds are guides
The task publishes floors based on moving data at 4.8 terabytes per second or performing arithmetic at 989 tera floating-point operations per second, whichever takes longer. These are nominal hardware bounds. Actual kernels also pay for instruction scheduling, imperfect traffic patterns, synchronization, and launch-related costs. My practical read probes were slower than the nominal floor. I used both figures: the nominal bound explained what could not be beaten, while the practical measurement suggested what this machine and access pattern could realistically achieve.
The shape atlas becomes a decision map
Instead of remembering that one method was generally good, I built a table across layer and token range. That table becomes the dispatch plan. It captures where a vector reduction wins, where cluster split-K helps, where packed pooler weights help, and where a library should remain in control. The appendix exposes every official projection case and its measured result. This makes the final 1.30 score inspectable: you can see which cases improved, which stayed near baseline, and which still regressed.
I · The challenge and the model / 11
Numerical formats and error#
A computer has to choose how many bits to spend on a number. That affects storage, speed, and how close an answer can be to the reference.
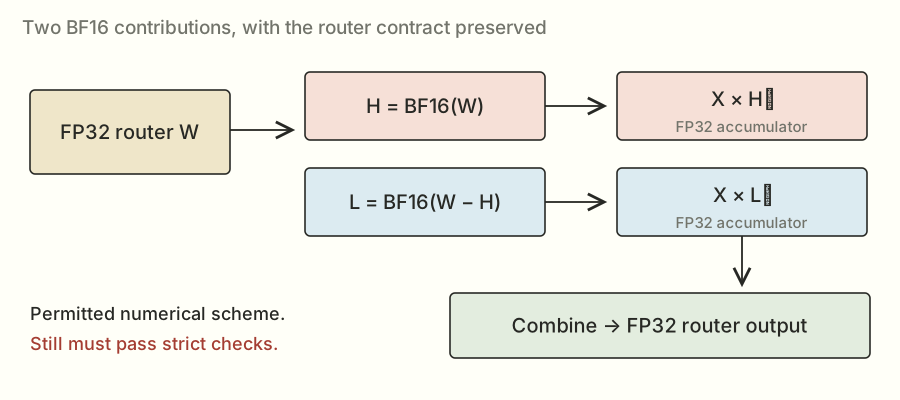
Bits divide range and precision
A floating-point representation divides its bits among sign, exponent, and significand information. The exponent largely determines range; the significand determines how finely values are represented within that range. FP32 uses one sign bit, eight exponent bits, and 23 stored fraction bits. BF16 uses one sign bit, eight exponent bits, and seven stored fraction bits. Sharing the exponent width does not make their precision equal. BF16 can cover a broad range while rounding many distinct FP32 values to the same stored value.
Storage precision and accumulation precision
A matrix product can read BF16 operands and accumulate partial sums in FP32. That preserves the original operand values while making the running sum more precise than a BF16 accumulator would be. The final dense result is converted to the required BF16 output. These are separate choices: operand storage, product instruction behavior, accumulation, split reduction, and output format. A library configuration that changes a reduction to a lower-precision type can violate the intended numerical design even if its output tensor has the correct dtype.
Why summation order matters
Consider adding a small value to a much larger finite-precision value. The small contribution may fall below the larger value's representable spacing and disappear after rounding. If several small values are summed first, their combined contribution may survive. A split reduction changes grouping, and atomic contributions may arrive in different orders. This is why two legitimate implementations can differ slightly. The task does not ask for arbitrary bitwise identity, but it does impose concrete error tests, including row-level checks that can expose concentrated failures.
How the projection error is checked
The task compares outputs with a high-precision reference using relative L2 error. Dense outputs have a one-percent bound, while the router has a much tighter 0.01 percent bound. There are also per-row safeguards and special sparse probe rows. Roughly one row in eight has one nonzero power-of-two input, exposing a weight column directly. That check helps catch a method that quietly stores approximate weights. It is possible for a global norm to look acceptable while a particular row is unacceptable.
The other formats belong to other contracts
The attention cache uses the specified FP eight format, while the expert weights use NVFP four. Those facts do not authorize changing the dense projection weights to FP eight or four-bit weights. Each problem has its own representation and numerical rules. A tempting optimization can be scientifically interesting and still be outside this challenge's contract. My compression experiments therefore attempted lossless representations of the original BF16 values, rather than substituting a lower-precision approximation and hoping the aggregate error would hide it.
The high/low router exception
For the router, the rules explicitly permit a BF16 high part plus a BF16 low part, accumulated in FP32. First round a weight to the high part. Then compute the residual in FP32 and round that residual to the low part. The pair approximates the original FP32 weight much more accurately than the high part alone. It is not an arbitrary permission to reduce precision elsewhere, and it should not be described as a mathematically exact decomposition for every FP32 value.
I · The challenge and the model / 12
Why the router needs special care#
The router helps select which experts process a token. Its numerical requirements are stricter, so I couldn't treat it like every other projection.
A small matrix controls a discrete decision
The router's outputs help determine which experts process a token. That selection is discrete: an expert is included or excluded. If two scores are close, a small numerical change can alter their ordering. The projection task measures the router's numeric output directly with a tighter bound, and the full-layer task also cares about routing behavior. A relatively small matrix therefore carries important correctness consequences. It is not safe to assume its values can be approximated as loosely as a downstream dense activation.
Constructing the two weight parts
Let a router weight be w. Define the high part by converting w to BF16. Convert that high part back to FP32, subtract it from w, and convert the residual to BF16 to obtain the low part. The low part represents detail that was too small to fit in the first rounding. Preparing these static parts once avoids repeating the conversion for every activation. The evaluated matrix products still use fresh input activations and FP32 accumulation.
Two products and a sum
The intended computation can be organized as an input product with the high weights plus an input product with the low weights. A straightforward implementation might use two GEMMs and then an addition. That is easy to understand but can pay multiple launch and intermediate-memory costs. Other implementations place the two weight parts into one larger or interleaved operand so a tensor-core kernel produces both contributions in one path. The final sum must combine corresponding high and low outputs, not unrelated adjacent features.
Packing high and low values
I explored layouts that place high and low contributions in paired output columns. A kernel can load the packed weight region, accumulate the two contributions in FP32, and combine the pair in its epilogue. This changes memory access and the shape seen by the dot-product instruction. It also changes the amount of intermediate state the kernel holds. Packing is useful only if the saved launches or better transactions outweigh register pressure, repeated activation reads, and any reduction overhead introduced by the new design.
Why the router invited split-K
There are only 256 router outputs. If a block handles many outputs and several token rows, the output grid can contain too few blocks to occupy the GPU well. Splitting the long input-feature reduction creates additional blocks. Each block computes a partial contribution and must participate in a correct final sum. This is the central tradeoff behind my early router improvement: more parallelism can reduce the long per-block work, but the resulting communication and synchronization must remain cheap enough.
The router as a recurring test case
The router appears repeatedly in my story because it exposes several systems lessons at once. Insufficient parallelism can dominate. Extra launches can dominate. Packed layouts can help or hurt. Atomic reductions can change rounding order. Fresh graph replay can reveal counters that were not reset. Finally, a substantial router-only speedup may translate to a modest overall projection score because the larger weight matrices still consume much of the load's time. I will examine both the local router gain and its aggregate contribution.
II · Hardware, kernels, and measurement / 13
A guided tour of the H200#
The H200 was my experiment machine. Here's the useful hardware vocabulary, with each part connected to the work it does.
A GPU is many execution resources
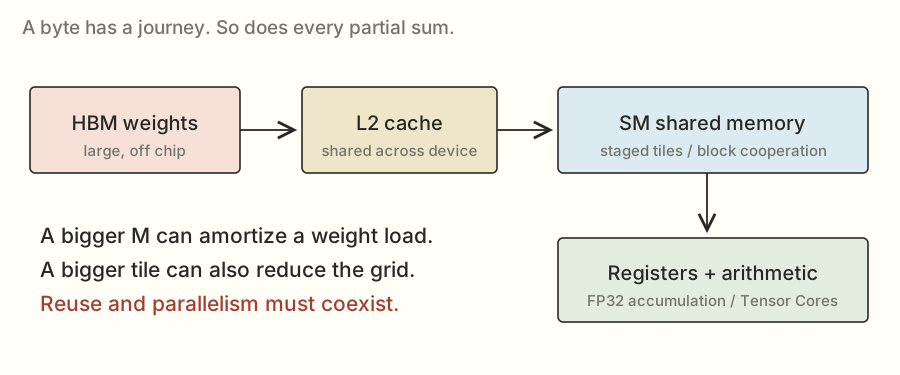
A GPU is not one enormously fast CPU core. It contains many streaming multiprocessors, or SM units, that execute groups of threads. Each SM has instruction execution resources, registers, shared memory resources, and access to specialized tensor-core arithmetic. The device also has a shared last-level cache and high-bandwidth external memory. A kernel's design determines how much of that machine can work at once and how efficiently data reaches it. Owning a fast GPU is therefore only the beginning of obtaining a fast result.
HBM supplies the large tensors
High bandwidth memory holds the model weights and large activation or cache arrays. Its capacity allows these arrays to reside on the GPU, but capacity and bandwidth are different properties. Even when the weights fit comfortably, reading them still takes time. At single-token projection shapes, a large fraction of useful work involves streaming weights with little reuse across token rows. This is why the payload sizes in the shape atlas matter. A memory-bound kernel can leave arithmetic hardware waiting even though the GPU has plenty of free memory.
L2 changes what reaches HBM
The L2 cache sits between execution resources and external memory. If data is reused while resident, later accesses can avoid another external fetch. That is valuable in production, but it complicates isolated benchmarking. A candidate repeatedly timed on the same small weight set may appear fast because the benchmark warms the cache. The judge deliberately begins each replay with cold L2 conditions and rotates weight copies. I copied that principle into the lab so a method would not win solely because my test accidentally favored cached weights.
Shared memory and registers
Registers are fast storage private to executing threads. Shared memory is explicitly managed storage accessible to threads in a block. Kernels use these resources to hold tiles and reuse data rather than repeatedly fetch from external memory. But both resources are finite. A larger accumulator consumes registers. A deeper load pipeline consumes shared memory. Those choices can reduce the number of resident blocks or warps, making it harder to hide latency. Resource use is therefore part of the algorithm's performance cost, not just a compiler detail.
Specifications and measured floors
The task's nominal bandwidth and arithmetic rates give useful lower bounds. They do not imply that every access pattern reaches those rates. My practical probes measured how quickly this machine streamed selected payload sizes under the lab's conditions. For example, the handoff recorded about ten point 43 microseconds for a thirty 7.7 megabyte read, slower than the task's nominal bandwidth-only floor. I used such measurements to ask whether a kernel was leaving obvious room, while remembering that a matrix kernel must also compute and synchronize.
Match the evaluation machine
The remote lab used an H200 S X M and the specified SGLang image so that architecture, libraries, and toolchain resembled the judge. I also read clocks and power settings rather than assume any machine named H200 behaved identically. This reduces avoidable differences but cannot eliminate all run variation. The judge and pod had different driver versions in the recorded machine metadata. A useful local result is evidence for a promising change, not a replacement for evaluating it on the official system.
II · Hardware, kernels, and measurement / 14
Threads, warps, blocks, and scheduling#
Threads, warps, and blocks are different ways of grouping GPU work. The key question is whether the grouping leaves enough useful work to schedule.
From a grid to blocks
A GPU kernel launch describes a grid of blocks. Blocks are units the device can schedule onto streaming multiprocessors. Within each block, threads cooperate on a piece of the computation. The mapping from a block's index to token rows, output features, and reduction work is a core part of kernel design. If the grid exposes too few blocks, many SM units may have no useful work. If each block repeats too much work, adding blocks can also increase traffic and arithmetic waste.
Warps execute together
Threads are organized into warps of 32. Instructions are issued for groups of lanes, with masks controlling which lanes participate. When branches lead lanes down different paths, the hardware may have to execute those paths separately under different masks. Data layout and reduction layout determine how values are distributed across lanes. A kernel that looks like a vector operation at the source level still becomes a concrete pattern of warp instructions, lane communication, and memory requests.
Latency hiding
A warp waiting on data cannot immediately use the result. If other independent warps are ready, the scheduler can issue their work during that wait. This is latency hiding. It does not make memory infinitely fast; it supplies enough independent work to keep resources busy while requests complete. Increasing block or warp count can help until some other limit intervenes. The important quantity is useful independent work, not merely the number of thread identifiers in a launch.
Occupancy and resource limits
Occupancy describes residency of warps relative to hardware limits. Register usage, shared-memory usage, thread count, and block limits can all restrict it. High occupancy is not a guarantee of high performance: an efficient kernel may need fewer resident warps, and extra residency can introduce unnecessary work. Low occupancy is also not automatically a defect. It becomes a concern when the kernel cannot hide latency or fill available throughput. I examine occupancy as one explanation for timing results, rather than optimize it as a scoreboard of its own.
Why small output grids are difficult
Suppose a block handles many output features and all the token rows in a small projection. The output grid may contain fewer independent tiles than the GPU can use effectively. The reduction dimension can still be thousands of elements long, leaving each scheduled block busy for a relatively long time. Splitting that reduction creates more blocks from the same output geometry. That is the motivation behind split-K. The price is that several blocks now contribute to the same logical output and must combine those contributions correctly.
Why I sweep launch parameters
A warp-count sweep is not arbitrary numerology. Changing warps per block changes how many lanes share loads and reductions, how much state each thread carries, and how many blocks fit on an SM. The optimum can differ across matrix shapes and cache policies. My final single-token change moved selected kernels to sixteen warps, but the later 32-warp candidate regressed officially. The hardware rewards a balance. A larger launch configuration is a hypothesis that needs measurement, not a monotonic upgrade.
II · Hardware, kernels, and measurement / 15
The journey of a byte#
Before the GPU can multiply a value, it has to get that value. I'll follow the memory path and explain why moving data can dominate the calculation.
Movement can dominate arithmetic
Consider a single-token projection with a large BF16 weight matrix. Each weight value participates in a small amount of useful arithmetic before the kernel moves on. The tensor cores may be capable of tremendous arithmetic throughput, but they cannot use values that have not arrived. If the required byte movement takes longer than the minimum arithmetic time, memory is the limiting resource. Optimizing a few arithmetic instructions in that regime may barely change the measured time. Improving access patterns or avoiding extra traffic can matter much more.
Reuse changes the cost per output
When multiple token rows use the same weight tile, a kernel can keep that tile in a faster level of memory and apply it to several rows. This amortizes weight movement over more useful operations. But reuse requires storage and a schedule that makes the reused values available at the right time. Large tiles can capture more reuse while increasing shared-memory and register demands. A design therefore trades movement against resource pressure. The ideal tile for one token need not resemble the ideal tile for 256 tokens.
Scratch traffic is real traffic
Split algorithms often write partial outputs into scratch memory and read them back during a reduction. That traffic is additional to the original input, weights, and final output. Scratch also introduces a dependency: the final answer cannot be complete until the needed partials exist. A second reduction kernel adds another launch. A fused last-arriving-block design replaces that launch with counters and synchronization. Neither arrangement is free. The correct comparison counts all of these costs, not just the shortened matrix-product loop.
Cache policies are implementation choices
A load can be configured to interact with cache levels differently. In my single-token experiments, streaming weight loads with the selected .cg policy helped specific kernels. The input vector had a different reuse pattern from the large weight stream, so treating both identically was not obviously optimal. Cache policy syntax is architecture and compiler dependent, and invalid combinations can fail during assembly. I encountered that distinction during the search. A failed policy configuration is not a measured performance result.
Kernel launches create boundaries
A kernel boundary can mean another launch, another synchronization dependency, and another set of intermediate memory accesses. Fusion can remove some of those costs. But fusion also combines resource needs and can reduce parallelism. My first slow router and later failed fused reductions demonstrate both sides of that tradeoff. It is better to ask which boundary is expensive and what replacing it costs than to assume fewer launches always wins. The complete captured graph is the object I ultimately time.
Account for the whole byte budget
For any proposed kernel, start by listing weight bytes, activation bytes, output bytes, and scratch bytes. Then ask which reads are reused through cache or shared memory and which values are redundantly fetched by multiple blocks. This accounting is approximate, but it often explains why a seemingly clever method loses. A compressed representation may read fewer weight bytes yet add metadata traffic and decoding instructions. A split kernel may expose more blocks yet reread activations. The byte budget turns intuition into a testable prediction.
II · Hardware, kernels, and measurement / 16
Coalescing, tiling, and weight layout#
The same numbers can be arranged in memory in different ways. Some arrangements make neighboring threads' reads much easier to serve together.
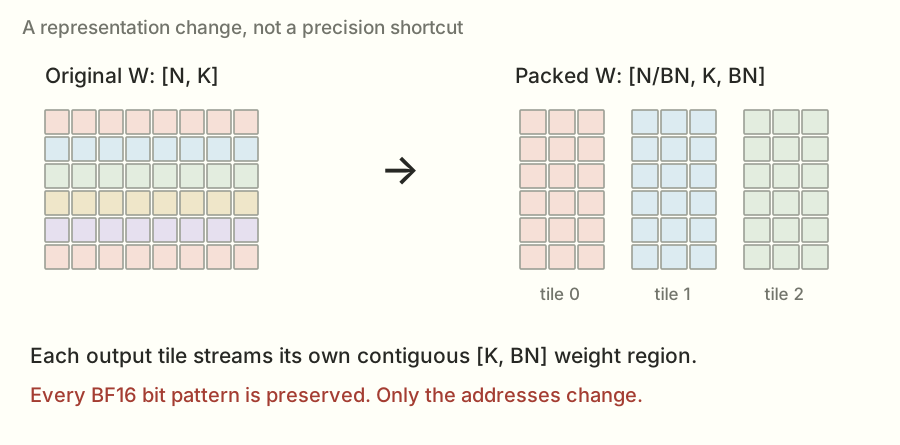
Adjacent lanes should help each other
A warp's memory accesses can be combined efficiently when nearby lanes request nearby addresses in a suitable alignment pattern. This is the intuition behind coalescing. If lanes access widely separated locations, the hardware may need more transactions to deliver the same useful values. The precise transaction behavior depends on the access size, alignment, and architecture, but the design principle is simple: arrange work so the machine transfers useful contiguous regions rather than many poorly utilized fragments.
Why a tile is more than a rectangle
A tile describes the subset of matrix values a block loads and computes. Its shape determines which dimension is contiguous, how data is reused, which tensor-core instructions fit, and how much shared memory is required. The tile can also change the number of independent blocks. A wider output tile may improve reuse but reduce the grid size. A narrower output tile may expose more blocks but repeat activation loads. Tuning is a search through these interacting effects, not a search for the largest rectangle that fits.
A physical transpose
A contiguous transpose rearranges weights so a different matrix dimension becomes contiguous in memory. That can change the memory path seen by a custom kernel or the layout seen by a library. Because the weights are static, I can perform the rearrangement during preparation and reuse it. The tradeoff includes preparation time and additional resident memory. A transposed view without a copy is different: it changes stride metadata while keeping the same physical values in the same places. I distinguish those operations carefully in the code walkthrough.
The packed pooler layout
My packed pooler groups output features into tiles and stores each tile as a contiguous sequence across K and the tile's output columns. A block then streams the weight region it owns in the layout expected by its dot product. This is a lossless reordering: every original BF16 value is preserved. The selected tile width was 32 output features for the included pooler paths. The benefit came from the complete access and execution pattern, not from changing the mathematical projection or quantizing its weights.
Shared-memory bank conflicts and swizzling
Shared memory is organized into banks. Certain access patterns make multiple lanes contend for bank resources, which can serialize work. The custom cluster kernel rearranged shared-memory positions with a swizzle so its matrix-load instruction pattern encountered a more favorable bank mapping. The swizzle changes addresses within the staging tile, not the mathematical values. Such details are where a high-level matrix equation becomes a hardware-specific implementation. They are also a reason to validate both address mapping and final outputs after changing a layout.
Alignment and nearby shapes
An output layout that is well aligned for a token count divisible by eight may behave badly for an odd token count. My alternate library orientations encountered this risk, so the final design retained a fallback when the swapped output's leading dimension did not meet the chosen alignment condition. Nearby-shape measurements were valuable here. Without them, a method could look excellent on the scored values while collapsing on a legitimate neighboring shape. Robust specialization uses meaningful shape properties and preserves a safe general route.
II · Hardware, kernels, and measurement / 17
Tensor cores and matrix instructions#
Tensor Cores do specialized matrix arithmetic. This note connects that hardware to the tiles and accumulation steps in the kernels.
Many products in one instruction
Tensor-core instructions operate on small matrix fragments distributed across warp lanes. They perform many multiply-accumulate operations together, which can be much more efficient than issuing separate scalar products. But the instruction expects particular operand shapes, layouts, and numerical formats. A kernel must load and arrange data to meet those expectations. Much of its work is therefore feeding the arithmetic efficiently: moving tiles, staging them, loading register fragments, and making the next operands ready before the current computation finishes.
BF16 products with FP32 accumulation
The relevant matrix instructions can consume BF16 values and accumulate into FP32. My custom kernels preserved that accumulation choice. For the router, both high and low weight contributions also remained in FP32 accumulators before combination. A high-performance library may offer several reduction schemes, so the final output dtype alone is not enough to establish numerical behavior. I explicitly constrained the cuBLAS Lt split reduction to the compute type where that configuration was used.
What a skinny dimension wastes
An instruction operates on its supported tile even if the logical problem has fewer useful rows or columns. A kernel may mask loads and stores while still executing arithmetic on padded entries. This can be worthwhile when tensor cores are efficient enough, but the fraction of useful work changes with the shape. Single-token projections are especially awkward for large token tiles. A direct vector reduction can avoid that particular waste, although it gives up some matrix-instruction throughput. This is one reason my final dispatch contains both styles.
Loading matrix fragments
In the custom cluster kernel, asynchronous copies stage weight and activation tiles in shared memory. Matrix-load instructions, called ldmatrix, transfer the staged data into the register fragments expected by MMA. The MMA instruction updates FP32 accumulators. This sequence repeats across K tiles. The source code's tile dimensions determine shared-memory addressing and which lanes supply which fragments. When I animate this path, the colored values follow one tile all the way from global memory into the accumulator.
MMA and WGMMA are different designs
The kernel that helped my QKV path used synchronous warp-level MMA instructions and block-cluster reduction. It did not use warp-group MMA. Hopper also supports more advanced designs involving warp-group operations and tensor memory transfers. Those capabilities are important to understand, but naming them does not mean my experiment implemented them or that they would win automatically. I will distinguish an implemented path, a tested losing path, and a proposed future path throughout the investigation.
Fast arithmetic cannot outrun missing data
Imagine doubling arithmetic throughput while keeping the weight stream unchanged. If the kernel was already waiting mainly for weight data, total time may barely improve. Conversely, a larger verification batch may create enough arithmetic reuse that instruction throughput matters more. The roofline model formalizes this relationship. It also explains why a hand-written tensor-core kernel can lose to a simple library call: the library may have a better balance of data movement, scheduling, and arithmetic for that exact matrix geometry.
II · Hardware, kernels, and measurement / 18
Rooflines and practical limits#
How fast could a kernel plausibly be? I used rough compute and data-movement limits to decide where more experiments might still be worthwhile.
Deriving the two lower bounds
There are two simple lower bounds on execution time. Required floating-point operations divided by peak arithmetic rate gives an arithmetic bound. Required bytes divided by peak bandwidth gives a movement bound. A kernel cannot finish faster than the larger of these idealized quantities, because both resources must provide the necessary work. The bounds ignore many real costs, so they are optimistic. They are still valuable for detecting impossible expectations and for deciding whether to focus first on arithmetic or data movement.
The roofline curve
Arithmetic intensity is useful floating-point work divided by data movement. At low intensity, attainable throughput rises with intensity because bandwidth limits the supply of operands. At high intensity, the curve reaches an arithmetic ceiling. For the task's nominal BF16 rates, a simple curve is the smaller of 4.8× intensity and 989 tera operations per second. The diagram is a bound based on those assumptions, not a set of measured kernel speeds. Real points generally sit below it.
Move M across the curve
Under the weight-only approximation, my projection's intensity is roughly M. A single-token case begins at very low intensity. Increasing token rows allows more computation per fetched weight, moving the idealized point rightward. But repeated weight loads across blocks, activation traffic, output traffic, and scratch can lower the effective intensity. This is why I do not use the simplified formula to declare a kernel compute-bound with certainty. I use it to explain the regime, then inspect the implementation and measure its behavior.
My practical streaming probes
The handoff recorded practical read times for several relevant payload sizes: about 3.84 microseconds for 8.4 megabytes, 5.79 for sixteen point eight, ten point 43 for thirty 7.7, and sixteen point 65 for about 67 megabytes. These are local measurements under a particular probe, not universal physical limits. They helped explain why large weight projections had limited remaining room and why enough concurrent memory streams mattered.
Choose high-value experiments
Suppose a projection takes eighteen microseconds and its plausible practical floor is around sixteen and a half. A complex design cannot reasonably promise a ten-microsecond saving without changing the traffic model. Another case might have several microseconds of avoidable launch or reduction overhead and more attainable room. I estimate potential savings in absolute time, account for which loads are affected, and compare that potential with implementation complexity. This is how roofline reasoning becomes a prioritization tool rather than a decorative chart.
A bound is not a guarantee
Near the end of the project, the remaining official gap to 1.32 was small. That did not make the target guaranteed. A nominal floor leaves out synchronization, scheduling, compiler choices, and variation between runs. Several plausible designs were already close to practical limits, and some advanced alternatives had failed. The correct conclusion was that specific opportunities remained worth testing, not that the arithmetic implied an inevitable result. Honest bounds help me make better experiments without pretending to know their outcome in advance.
II · Hardware, kernels, and measurement / 19
Split-K and the cost of combining work#
Split-K means dividing a long sum into partial sums. It creates more parallel work, then charges me for putting the answers back together.
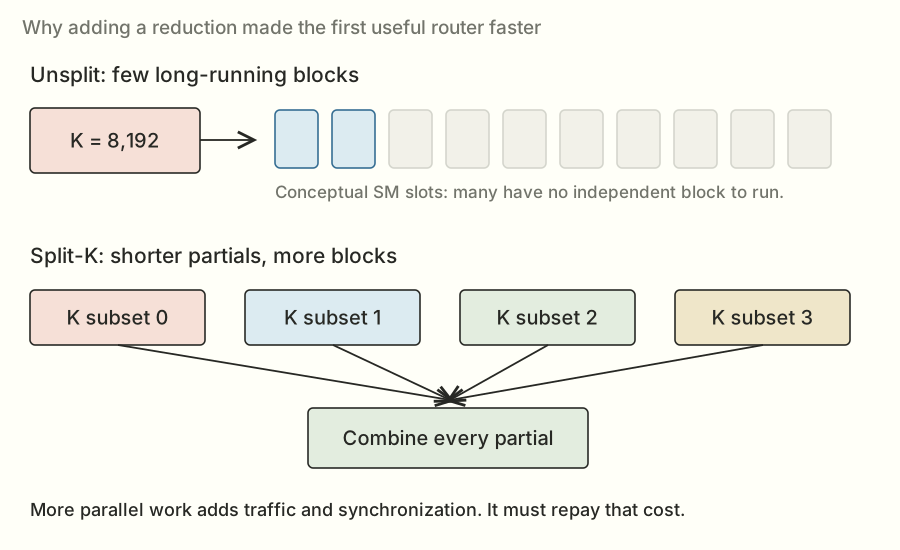
Start from one long reduction
An output tile is a set of token rows and output features. Each output value sums products across the input-feature dimension K. In an unsplit design, one block can own that whole reduction for its tile. This avoids communicating partial results to other blocks, but it leaves the grid size determined by output geometry. When that grid is too small, the block can have plenty of work internally while the overall device has too little independent work to schedule.
Turn K into another grid dimension
Split-K assigns different portions of K to separate blocks for the same output tile. With four splits, each block performs approximately a quarter of that reduction. There are now four times as many contributing blocks, potentially improving utilization and hiding latency. The useful multiplication count is broadly similar, although padding and implementation details can change it. The final output is incomplete until all four contributions are combined. Split-K exchanges a long local reduction for a parallel reduction followed by a combination problem.
A separate reduction kernel
The straightforward design writes FP32 partials to a scratch tensor. A second kernel reads the partials, sums across splits, and writes the required output. This makes dependencies easy to understand: the second launch follows completion of the first on the stream. But it adds scratch traffic, another launch, and final reduction work. For a large matrix, the new parallelism may easily repay that cost. For a tiny router or a kernel already close to a latency floor, the extra cost can consume the entire benefit.
Atomic addition into an output
Another approach initializes the output to zero, then lets each split atomically add its FP32 partial contribution. An atomic operation protects the update from conflicting simultaneous writers. This can avoid a separate partial-sum reduction kernel, but the output-zeroing operation remains part of the captured call path. Contention and arrival order also matter. FP32 atomic addition preserves the intended accumulator type while potentially changing reduction order, so correctness and run behavior must still be checked on fresh inputs.
The last-arriving-block design
A fused design can write each partial, increment a per-tile counter with suitable memory ordering, and let the last arriving block perform the final sum. This removes one launch but introduces global synchronization logic, partial reads, and a correctness-sensitive reset. A counter that is not returned to the initial state can fail on the next graph replay. Memory ordering must ensure the last block sees completed partial writes. This is a good example of complexity that must earn its place through measured savings, not merely fewer launches.
How I choose a split count
Too few splits can leave the GPU underused. Too many can increase scratch, atomics, repeated activation reads, and synchronization. The best count depends on M, N, K, tile dimensions, and hardware residency. I therefore sweep candidate counts and retest finalists with paired timing and nearby shapes. The early split-router result showed the value of added parallelism. Later failed fused reductions showed that combining the work is often the harder half of the optimization. Neither lesson makes split-K universally good or bad.
II · Hardware, kernels, and measurement / 20
Hopper pipelines and block clusters#
The next hardware ideas are about overlap and cooperation: fetch the next tile while computing this one, and let selected blocks combine their work.
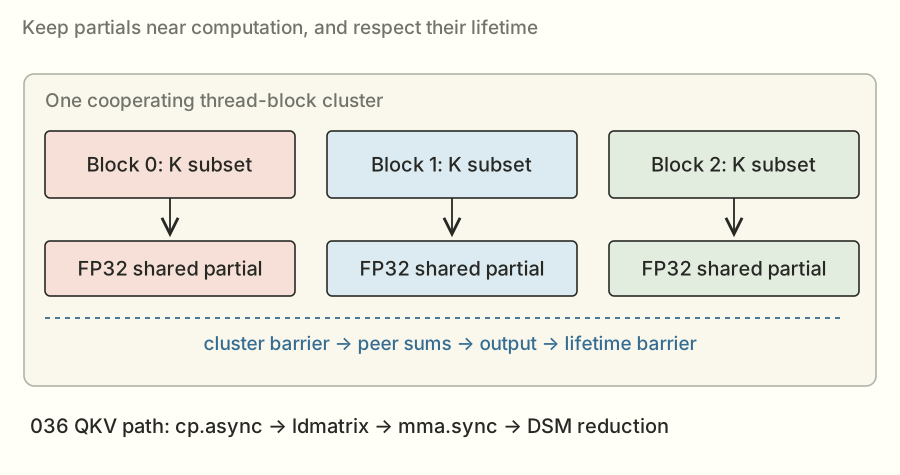
Overlap loading and computation
A simple tiled kernel loads data, waits, computes, and repeats. A pipelined kernel tries to load a future tile while computing a current tile. Multiple staging buffers keep these tiles distinct. The goal is to hide movement latency behind useful arithmetic. But more pipeline stages consume more shared memory and may reduce resident blocks. They can also be wasted if each block has only a few K tiles. A deeper pipeline is therefore a tunable tradeoff, not a free source of throughput.
What cp.async supplies
The custom QKV kernel uses asynchronous global-to-shared copies. Groups of copies are committed, and the kernel waits for an appropriate number of groups before using a tile. Shared-memory addresses are swizzled for the later matrix loads. Threads then synchronize where needed before consuming staged values. These operations let the design organize movement and computation explicitly. They also create obligations: a consumer must not read unfinished data, and a staging slot must not be overwritten while another operation still needs its previous contents.
ldmatrix and mma.sync
After staging, the kernel loads matrix fragments from shared memory into registers using ldmatrix instructions. Warp-level MMA updates FP32 accumulators. The loops walk through the K tile, then advance the pipeline. Different warps own output-feature rows, and the token tile determines how many input rows the block reuses. The implementation is specialized to the matrix instruction's fragment layout. My diagram follows one subset of weights and activations so the assembly-level names stay connected to actual data and arithmetic.
Distributed shared-memory reduction
Hopper thread-block clusters let cooperating blocks access distributed shared memory. My QKV design splits K among blocks in a cluster, places each block's FP32 partial result in shared memory, synchronizes the cluster, and reads peer partials to form the final answer. A second cluster synchronization protects the lifetime of that shared state. This avoids a separate global scratch-reduction launch, but cluster barriers and peer accesses still have costs. The method was useful in a particular small-token QKV range, not automatically across the whole workload.
TMA, multicast, and WGMMA
Hopper also offers tensor memory transfers and warp-group matrix operations. A well-designed kernel can use these mechanisms to arrange bulk tile movement, reduce repeated transfers, and feed larger cooperative arithmetic structures. However, these features require compatible layouts, synchronization, and scheduling. My separate TMA experiment did not demonstrate a win, and my selected QKV kernel did not become a TMA-plus-WGMMA implementation. I explain the capabilities because they inform future hypotheses, while keeping the actual implemented and measured designs clearly identified.
Why deeper cluster pipelines lost
The later cluster sweep tried different stage counts, warp counts, K widths, and token tile variants. The deeper designs did not provide a useful improvement over the selected path. That outcome is consistent with several possible limits, including shared-memory pressure and the amount of per-block work available to overlap, but the exact cause needs more profiling than the available counters supplied. I keep the measured rejection separate from a proven microarchitectural diagnosis. Timing tells me the design lost; it does not by itself identify every reason.
II · Hardware, kernels, and measurement / 21
The submission contract#
A fast implementation still has to fit the task's interface. Here are the preparation, input, output, and runtime boundaries I had to work within.
One source file and two phases
For the projection problem, the submitted Python file defines a preparation function and a timed kernel entry point. Preparation receives static weights once and returns reusable state. The kernel receives fresh activations and shape configuration, uses that state, and returns the required output tensor. This is a natural inference boundary: model weights persist while requests change. A useful implementation makes the boundary explicit so it is clear which work is legitimate static preparation and which work belongs to each evaluated invocation.
What preparation can do
Preparation can build lossless transposes or packed layouts of static weights and compile the native extensions the kernel needs. The task gives preparation up to 300 seconds. That budget is generous enough for meaningful layout work, but it is finite. Retaining every experimental layout also increases resident memory and setup cost. Candidate 37 later removed layouts the selected dispatch never consumed. That was a practical cleanup with an official check, not a change to the mathematical output.
What belongs inside the timed call
The timed entry point must compute its output from the fresh input values. Dynamic host synchronization such as reading a GPU scalar back with item or transferring an activation to the CPU is incompatible with the required CUDA graph capture. Branching on known shapes and configuration is allowed. My dispatch chooses by layer and token range. Allocations with fixed shape can be captured as supported by the environment; branching or allocating based on activation values is a different and prohibited behavior.
Compilation and the environment
Native CUDA can be compiled within the submission through PyTorch's inline extension mechanism. Compilation time counts toward the overall run time limit, though not the reported kernel score. The code must rely on libraries and tools in the specified image, with no network installation during evaluation. I therefore keep extension variants bounded and hash their sources for reliable identity. A design that wins after a long manual compilation session still needs to fit the actual evaluation lifecycle.
General shape behavior
The scored cases are public, but the implementation should compute the specified operation across legitimate configurations and nearby shapes. Shape specialization is normal performance engineering. A fallback triggered by meaningful alignment or tile conditions can make that specialization robust. A method that only returns correct answers for memorized cases would not satisfy the task. My correctness runner includes neighboring token counts, fresh graph replays, and distributions beyond the simplest normal input to expose those risks.
A submission is an auditable artifact
Each promising implementation becomes an immutable experiment snapshot. Its source can be hashed, submitted, and associated with a job identifier and saved result. That chain matters when several similar versions are being explored. It prevents a successful result from accidentally being attributed to later edited code. The final project submission was copied byte for byte from the officially scored winner, and the previous working source was preserved. Reproduction begins with that exact source, not a vaguely similar current file.
II · Hardware, kernels, and measurement / 22
What correctness really tests#
One random input isn't enough to trust a kernel. These checks look for numerical mistakes, indexing problems, and answers that accidentally survive from an earlier call.
A reference more precise than the candidate
The dense projection checks compare against a high-precision reference. Relative error measures the size of the difference compared with the size of the reference output. The dense bound is looser than the router bound, because the router participates in expert selection. There are additional row-level constraints and checks against invalid numerical values. Passing is therefore more than matching an output shape or observing a small average absolute error. The exact supplied reference and checking functions are the authority for this problem.
Sparse probe rows reveal weight changes
A particularly useful check places one nonzero power-of-two entry in an input row. Multiplying such a row by the weight matrix selects a scaled column of the weights. This makes it hard to hide a change in the stored weight values behind cancellation across a dense random vector. A method that uses an unapproved lower-precision weight representation can fail here even if its global average error looks small. The probe directly connects the numerical contract to the values the kernel actually consumes.
Outliers and near-zero rows
Random normal inputs are useful but incomplete. Outliers can create large dynamic ranges, and near-zero reference rows can make a naive relative-error interpretation unstable. The supplied checks define how those cases are handled, including a floor based on average row scale. I run the official reference checks rather than invent a more permissive metric. A robust implementation should tolerate the specified distributions across seeds, not merely one convenient sample that happened to match.
Fresh graph replays
My runner captures the candidate as a CUDA graph and then replays it on different fresh activations. This catches a class of bugs that eager validation can miss. A stale scratch buffer, an output accidentally reused from capture, or a counter that was not reset may pass the first call and fail the next. The output must follow the new input each time. The graph's structure can be reused; the evaluated answer cannot be cached across different activations.
Scored cases and neighboring shapes
The local correctness runner includes the judge's listed difficult cases, every scored projection shape, and nearby token counts such as seven, nine, seventeen, 24, 96, and 192 where appropriate. Some official tests also use much larger shapes. These cases challenge masks, tile boundaries, alignment, and dispatch transitions. A method that works at 32 tokens but mishandles 33 may reveal a general indexing problem rather than a small edge-case inconvenience.
Correctness gates performance decisions
The selection process has a strict order. First establish that a candidate computes the required outputs. Then time the complete valid path. If an integration fails, repair it before drawing a performance conclusion. If arithmetic fails, a fast timing does not count as an improvement. If arithmetic passes but timing loses, keep the result as evidence and reject that route for the selected dispatch. This ordering makes the experiment tree trustworthy and prevents attractive but invalid shortcuts from contaminating the final source.
II · Hardware, kernels, and measurement / 23
How the judge times a kernel#
A timing depends on how it was taken. This is why I used replay, fresh inputs, cold-cache treatment, and paired baseline/candidate measurements.
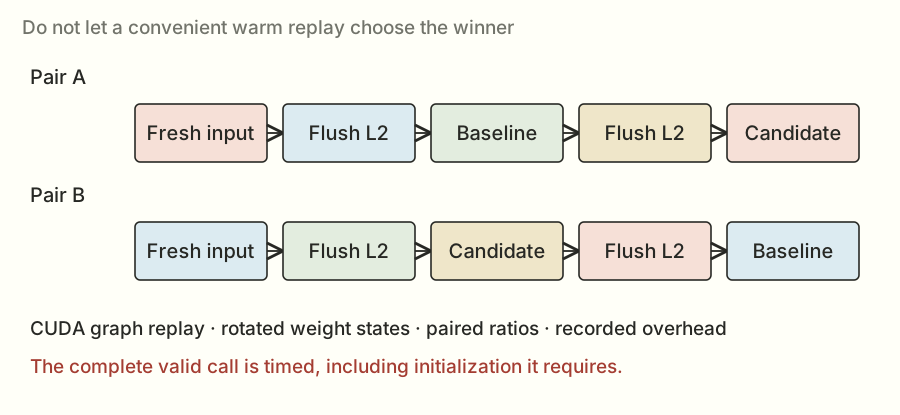
Eager time is not replay time
A Python call can include dispatch overhead, allocation behavior, compilation, and synchronization effects. The challenge instead captures the required call as a CUDA graph and measures graph replay, resembling the production decode path. A candidate that looks good in eager execution may lose under captured replay, and the reverse can happen. I therefore compare the execution mode the judge actually uses. Timing a different mode is useful for debugging, but it cannot establish the competition result.
Start with cold L2
Before each timed replay, the judge reads a buffer larger than the cache to remove an accidental warm-cache advantage. The local timer uses the same basic principle. It also rotates independent weight states so repeatedly using one convenient resident copy does not become the basis of the result. This does not reproduce every detail of the official evaluator, but it aligns the lab with a central property of the benchmark. I am trying to improve the required data path, not exploit a cache state the real test deliberately excludes.
Alternate the execution order
Suppose the first of two measurements tends to experience a different condition from the second. Always running the baseline first could bias the ratio. The judge pairs repetitions with the order swapped: baseline then candidate, and candidate then baseline. It computes paired ratios and uses a median summary. This helps cancel simple order effects and reduces sensitivity to isolated outliers. Pairing does not eliminate every possible difference, but it is much stronger evidence than comparing two unrelated best-case timing numbers.
Subtract the fixed replay cost
For a short kernel, the graph replay's fixed cost can be a substantial fraction of the raw event interval. The evaluator estimates that fixed overhead and subtracts it from both sides before calculating the kernel comparison. My local runs used an explicitly recorded overhead value, around four microseconds. Subtracting a nearly fixed number from very small timings increases sensitivity to measurement differences. That is one reason I avoid interpreting a tiny local percentage change as a guaranteed official gain.
Profiling and scoring are different tools
A profiler tells me which kernels ran and helps identify where time went. The official paired benchmark establishes the score. Profiling can introduce overhead or show durations affected by waits and overlap, so adding profiler rows is not always the same as measuring a complete call's wall time. My investigation used profiles to form hypotheses and paired timing to choose implementations. This separation prevents a beautiful profile breakdown from being mistaken for an independently reproduced speedup.
Reproduce the method, then use the judge
The remote lab matched important conditions: graph replay, fresh activations, cold cache, rotated weights, and swapped-order pairs. It still differed from the judge in machine details and parts of the surrounding harness. The local 1.3234 measurement was therefore a reason to submit, not proof of an official 1.32 score. This distinction is central to the story. A good local benchmark narrows the search; the official evaluation tells me what the competition recorded.
II · Hardware, kernels, and measurement / 24
How thirty timings become one score#
Thirty shape timings become one score through two aggregation steps. I'll work through those steps so a big individual speedup doesn't mislead us.
Define a speedup carefully
For a single comparison, speedup is baseline time divided by candidate time. If the baseline takes ten microseconds and the candidate takes eight, the speedup is 1.25. The time reduction is two out of ten, or twenty percent. Those percentages are different descriptions of the same change. Confusing them makes performance claims sound larger or smaller than they are. Whenever the article says 1.3012, it means a time ratio, not a direct percentage subtraction from execution time.
First aggregate the shapes within a load
A load contains the five projection families. The evaluator sums their measured times after applying their listed shape weights. For projections, the listed weight is 62 for each family in a load, so it cancels when forming that load's baseline-to-candidate ratio. The shape times themselves still matter. Saving two microseconds on a large matrix and saving two on the router have the same immediate effect on the summed load time, regardless of the individual percentage labels.
Then combine the six loads
The problem score is the geometric mean of the six load speedups. Multiply the six ratios and take the sixth root. Equivalently, average their logarithms and exponentiate. Each load has equal influence in this geometric aggregation, but the five shapes inside a load are weighted by their actual time contributions. This two-level structure explains why choosing winners by the arithmetic average of thirty shape percentages can select the wrong overall candidate. The score follows the stated workload aggregation, not an intuitive average of colorful bars.
A numerical example
Imagine three illustrative load speedups of two, one, and one half. Their product is one, so their geometric mean is one. The dramatic improvement in the first load is balanced multiplicatively by the regression in the third. An arithmetic mean would misleadingly report more than one. My actual problem has six loads, but the lesson is the same: a regression can undo a win elsewhere. I need to examine the complete vector of load results when composing a dispatch plan.
What the reported aggregate time means
The saved winning result reports a baseline aggregate of 4,830 point eight microseconds and a score-equivalent candidate time of about 3,712 point 56. These are aggregate values associated with the workload score. They are not the duration of one physical GPU kernel launch. Dividing the baseline aggregate by the official speedup gives the reported candidate equivalent. I label this clearly because a score's time unit can look concrete while representing a combination of several workloads.
Amdahl connects the score to decisions
Suppose a fraction f of a workload's time is accelerated by a factor s while everything else remains unchanged. The new normalized time is one minus f plus f divided by s. The total speedup is the reciprocal. If the component is small, even making it infinitely fast leaves a strict limit on total improvement. This is why I look for attainable absolute savings in important loads. It also explains why the router's impressive individual ratios did not turn into the same overall projection speedup.
II · Hardware, kernels, and measurement / 25
Noise, uncertainty, and moving ranks#
A measured time wiggles from run to run. This note explains what uncertainty means and why a leaderboard rank is a dated observation.
Repeated runs are not identical
GPU execution time varies with scheduling, clocks, temperature, surrounding system activity, cache details, and measurement procedure. Repeating the same source can yield different summary ratios. My records include official checks and independently scored runs with slightly different results. This does not automatically indicate a bug, nor does it prove a tiny improvement. It means I need repeated, appropriately paired measurements and an honest description of uncertainty. The closer two candidates are, the more important that discipline becomes.
Why a median helps
A median is the middle value after sorting measurements. It is less sensitive than a mean to a few unusually slow or fast repetitions. The judge uses medians of paired ratios rather than selecting a single best time. This is important because best-case timing can reward luck. A candidate should perform well across the relevant repetitions, not only on one favorable replay. Medians still do not reveal everything, so saved distributions and confidence information remain useful when the result is close.
Read a confidence interval honestly
The winning scored result includes an interval from approximately 1.2817 to 1.3207. The point estimate is 1.3012. The upper end touching a desired target does not establish that the target was achieved. The competition records the score and performs later review. An interval is a statement about uncertainty under the evaluator's method; it is not permission to advertise whichever endpoint I prefer.
Searching many candidates creates selection risk
When many variants are tried, one can look unusually good partly by chance. Selecting the maximum of noisy observations tends to select some favorable noise as well as real performance. My local search therefore screened configurations, then retimed finalists with more repetitions and nearby shapes before combining them. Independent official evaluation provides another check. These steps reduce the risk of promoting a lucky result, though they do not make every small difference statistically conclusive.
A better score can have a worse rank
At one historical snapshot, my 1.2888 result was around the high fifties on the projection board. Later, the stronger 1.3012 result appeared at rank eighty of 768. More competitors and stronger submissions had arrived. A rank is relative to the live population, while my speedup is a measurement against the baseline. I will show both with dates, rather than imply that a stronger implementation must permanently improve an earlier rank number.
What improvement claims I can defend
The source contains real implementation changes, and local paired comparisons show useful shape-level gains. The official best increased from 1.2888 to 1.3012. I can state those recorded outcomes. I should be more cautious about claiming a tiny precise causal percentage from two separate official runs whose intervals overlap. The strongest explanation combines controlled local evidence, correct arithmetic, exact source identity, and independent official results, while preserving the practical limits of each.
II · Hardware, kernels, and measurement / 26
Building an auditable investigation#
I wanted to be able to come back and identify exactly what earned a score. That meant saving code, commands, results, and the state of unfinished work.
Every experiment needs an identity
An experiment is more than a filename saying best version. It needs a concrete source, a hypothesis, a validation path, and a recorded outcome. I stored numbered source snapshots and job identifiers in a ledger. A source hash identifies the exact bytes that were evaluated. This matters when two agents or multiple branches explore similar designs. Without that chain, it is easy to remember the best score while losing track of which code actually produced it.
Separate local and official evidence
The local lab saved paired timings, raw ratios, configuration choices, and correctness logs. The official service returned its own tests, timing records, machine metadata, and score. Those records answer related but different questions. Local evidence helps isolate changes and explore variants quickly. Official evidence establishes the competition outcome. I preserve the distinction in file names, plots, narration, and result cards. A synthetic example or theoretical floor gets a different label again, so the viewer can always tell what was actually measured.
Keep rejected results
A failed or slower experiment is useful if it changes what I try next. The compression branches showed that moving fewer bytes was not enough. The QuACK integration failures showed an API requirement that had to be repaired before timing. The expanded launch candidate showed that doubling warps could regress. Keeping those results prevents repeated dead ends and makes a handoff more useful. Deleting the losses would produce a cleaner-looking success story and a less truthful account of engineering work.
Make the build reproducible
The lab used a pinned image, explicit commands, independent weight states, fresh input generation, and saved configuration parameters. Native extension names were derived from source hashes so compiled artifacts corresponded to code. A reproduction still needs to verify its own environment and machine state, because libraries and drivers can differ. The goal is not to pretend every run is identical. It is to expose enough information that another person can reproduce the method, interpret differences, and test the same claim.
Resource lifecycle belongs in the record
The remote GPU bills while allocated, even after a bounded search ends. My first lab session remained allocated longer than its productive benchmark work and accrued idle cost before stopping. That is a real operational failure to learn from. A complete workflow should synchronize evidence and stop compute promptly, with a verified shutdown mechanism for unattended work. Storage retention is a separate cost and data-preservation decision. Performance engineering is not complete if the result is reproducible but the experiment lifecycle wastes my budget.
The chain behind the final result
For the final 1.3012 source, I have the immutable experiment file, the scored job result, an independent check result, local correctness and timing evidence, a dated leaderboard read, and a snapshot manifest. The project submission was replaced with the exact scored bytes, with the previous source backed up. That chain is the basis for the ending of this article. I can open the files, inspect the selected methods, and ask whether a future result actually improves the same defined workload.
III · The experiment story / 27
A correct kernel that lost#
The first candidate got the answers right and still lost on time. That was the starting point for looking at how much independent work it exposed.
Candidate 001: a plausible starting point
The first recorded projection candidate used direct vector reductions for single-token work, a custom high-and-low router kernel for other token counts, and the baseline dispatch for the remaining dense products. The router held FP32 accumulators and looped through K tiles. On paper, it was straightforward: prepare static router parts, perform the required products, and combine them. It passed the reference checks. That established a usable starting implementation, but it said nothing yet about whether the GPU was being used efficiently.
The first check: 0.7761×
The official check reported 0.7761. That is a slowdown: a ratio below one means the candidate takes longer than the baseline on the aggregated workload. The result was not a failed arithmetic test. It was a correct implementation whose performance was worse. This distinction matters because the next action should address execution structure rather than relax numerical requirements or declare the reference too strict. I needed to understand what the kernel asked the GPU to do.
Too little independent router work
The unsplit router output grid was determined by token tiles and output-feature tiles. For a small batch and only 256 router outputs, that can expose few blocks. Each block still traverses the long K dimension, so a large amount of work remains serial within the available blocks. The research notes identify insufficient parallelism as an important diagnosis. This is a concrete mechanism: idle SM capacity cannot help a block unless the computation is partitioned into schedulable independent work.
Fusion had not solved the real limit
The candidate combined useful work, but reducing source-level steps is not the same as reducing elapsed time. If the resulting kernel exposes too little parallelism or uses resources inefficiently, a library with more launches can still win. This is the first major change in the investigation's direction. Rather than ask only how to fuse more, I asked how to create enough useful work across the device. The mathematics allowed splitting the reduction, provided the partial results were combined correctly.
A falsifiable next hypothesis
The proposed change was to distribute the long router reduction across multiple blocks. Each block would compute a subset of K and write a FP32 partial. A final kernel would sum those partials. This adds work, traffic, and a launch, so it could have failed. The prediction was that better utilization would save more time than the extra reduction cost. That is a useful hypothesis because a complete correctness check and paired performance run can test it directly.
What this failure contributed
Candidate 001 did not become the final submission, but it contributed a valid reference-compatible custom path and a clear negative result. The source and check remain in the ledger. Keeping them lets me explain the next improvement as a response to evidence rather than pretend the winning architecture was obvious from the beginning. The lesson is not that custom kernels are bad. It is that correct arithmetic and a plausible implementation are starting points, while measured execution determines the next engineering decision.
III · The experiment story / 28
Split the router: our first useful win#
The first useful change split the router's long reduction into more blocks. Here's the extra work it added and why it could still finish sooner.
Candidate 002 changes the work grid
Candidate 002 added a split dimension to the router launch. For the small token ranges, it selected sixteen splits; larger ranges used a different count. Each block traversed its assigned interleaved K tiles and accumulated high and low products in FP32. The output grid now contained many more independent blocks than the unsplit version. This directly addressed the earlier diagnosis while preserving the mathematical operation and the router's stricter output requirements.
The partial tensor and final sum
The partial tensor had a split dimension followed by token and output dimensions. Each contributing block stored its fresh result into the slice it owned. A reduction kernel then walked the split dimension and wrote the final router output. The implementation had a simple stream dependency between launches, making completion easy to reason about. The performance question was whether the extra global reads and writes were cheaper than the underutilized long reduction they replaced.
The official evidence changed direction
The new check returned about 1.1014, and the independently scored submission returned 1.1037. Both passed. The aggregate result had moved from a slowdown to a useful improvement over SGLang. It was important to obtain that independent scored run rather than report the check as though it were already on the board. The improvement supported the parallelism hypothesis for the selected workload, even though it did not establish the same benefit for every individual shape.
The profile revealed uneven gains
The recorded analysis of the split-router result showed strong router improvements at several small token counts, while the 256 token router case regressed. This uneven behavior is not surprising once I consider the output grid. Larger M already creates more independent tiles, so the benefit of splitting can shrink while reduction overhead remains. The same implementation choice can therefore be useful at one end of the workload and harmful at the other. That observation became the next dispatch question.
Why I did not stop at the aggregate
An aggregate win can hide a serious regression. If I only kept the final number, I would know the candidate was better overall but miss an opportunity to improve it further. The saved per-shape records let me identify where custom work helped and where baseline dispatch deserved to remain. This moved the strategy from replacing a whole operation family to selecting complementary paths. It also made the investigation more auditable: the next change had a specific target rather than an unspecified hope for another few percent.
The first decision pattern
The sequence now had a recognizable structure. I observed a slowdown, identified a plausible utilization problem, introduced split parallelism, validated the arithmetic, and measured a better result. Then the measurements exposed shape dependence. This pattern repeats throughout the project. A successful experiment rarely answers every question. It often reveals the next constraint more clearly, which is why a useful result should include both its achievement and the conditions under which it stops helping.
III · The experiment story / 29
Learning to dispatch by shape#
I started choosing implementations by layer and token count. Dispatch is just that decision: look at the job, then pick a suitable method.
Candidate 003 tests selective GEMV
A direct vector kernel had attractive behavior for some single-token cases, so candidate 003 narrowed where it was used. Its aggregate check was about 1.0121, much weaker than the split-router route and with uncertainty that did not establish a clear overall improvement. This is a useful warning about component intuition. A method can win a few selected cases and still fail to produce a compelling complete candidate when other paths differ or remain weak.
Layers have different geometry
Single-token QKV, output projection, pooler, and unpooler do not have the same N and K. The small unpooler slice is especially different from a full-width projection. A vector block owning four output rows may expose a different grid and register pattern for each matrix. The baseline also dispatches differently by shape. It was therefore reasonable to keep a direct vector method for some layers and avoid it for others. Shape-dependent dispatch reflects real computational geometry, not a departure from the mathematical task.
Candidate 004 adjusts router ranges
The next router dispatch candidate retained split work where it helped and adjusted split counts and token tiling for other ranges. It also narrowed single-token vector use rather than apply it universally. The checked score was about 1.1161, and the independent scored result was 1.1144. The improvement was incremental, but it demonstrated the value of choosing a policy over several correct methods rather than searching only for one replacement kernel.
A dispatch plan is an algorithm
The final implementation eventually represented each layer as ordered token ranges mapped to methods and parameters. The first matching range chooses a path, and an applicability check can fall back if necessary. That policy is part of the algorithm. It determines preparation requirements, code size, compilation cost, and which performance risks need testing. A clean dispatch plan also makes review easier: each region can be connected to an experiment rather than hidden behind a collection of ad hoc conditions.
Guard the boundaries
Whenever a method changes at a token threshold, nearby counts deserve attention. Masks must handle partial tiles, and a library layout may have alignment requirements. A dispatch that wins exactly at sixteen and 32 can still behave poorly at seventeen or 31. My later validation expanded these neighboring cases and used alignment-based fallback rules. Generality is not achieved by avoiding specialization; it is achieved by expressing meaningful conditions and verifying the transitions around them.
The next question becomes layout
After adding parallelism and narrowing dispatch, the remaining router path still involved separate high and low weight layouts and reduction costs. A larger-token case might be better served by a library matrix product if the high and low values were packed into one operand. That became the next important branch. Notice how the question changed: I was no longer merely increasing block count. I was asking whether a different representation could expose a better implementation without changing the required values or output precision.
III · The experiment story / 30
Packed router: reaching 1.1555×#
The router's high and low weight parts could be packed into one library operand. This was an arrangement change with different methods retained for different sizes.
Candidate 009 prepares a paired operand
Candidate 009 formed a packed router matrix by concatenating the transposed high and low BF16 weight parts along output columns. The original FP32 weights were still retained, and the decomposition followed the permitted high-plus-low scheme. Preparation performed this static rearrangement once. The goal was to let a library matrix multiplication compute both product families in a single call for the larger token range, rather than force that range through the same small-batch custom split kernel.
One product produces two output regions
The packed product has twice as many output columns as the logical router. The first region contains the high-weight product, and the second contains the low-weight product. Adding corresponding columns returns the FP32 router result. This is a different packing from the later interleaved-column kernel, where each high and low pair sits adjacent. Both encode the same two contributions, but their memory layouts and epilogues differ. Keeping those distinctions clear is necessary to understand which experiment actually changed what.
Keep the small-batch custom path
For smaller token counts, candidate 009 retained the split-router implementation and final reduction. For the larger range, it used the packed library product. This was not a claim that the library route had replaced custom kernels everywhere. It was an explicit combination of two regimes. Selected single-token dense layers also kept direct vector reductions. By this point, the submission was becoming a policy over several methods, each chosen for a different geometry and measured tradeoff.
The check and scored run
The packed-router candidate checked at about 1.1372. Its independently scored result was 1.1555. The difference is another reminder that checks and scored executions are separate noisy evaluations. The scored result became the early projection incumbent. I do not rewrite the check to match the better number, or treat the difference as a new code improvement. Both measurements belong to the same experiment history and should remain visible.
Why this still left a large gap
The router improved substantially, but many dense projections still used baseline dispatch or modest one-token custom paths. The larger weight matrices occupied much of the load time. Further progress therefore required work beyond the router. The per-shape breakdown suggested transposed weights, optional Hopper GEMV routes, wider K tiles, and alternative library kernels. I would test those ideas rather than assume the packed-router gain could simply be repeated on unrelated matrix families.
A useful principle emerges
The packed-router result established a practical pattern: transform static weights to present an equivalent computation to a better execution path, then dispatch by the shape regime where that path helps. This principle later reappeared in the transposed dense experiments, packed pooler tiles, and cuBLAS Lt orientation searches. The implementations were different, but the reasoning connected them. I was using freedom in representation and scheduling while preserving the operation the challenge actually required.
III · The experiment story / 31
The attention side story#
This is the attention side quest. Its scores belong to a different problem from projections, but the preparation and split decisions are useful to compare.
Why look beyond projections?
The broader project also explored attention and experts because the overall model spends time across several components. Those results do not count as progress toward the specific 1.30 projection target, but they explain the full investigation and provide useful systems lessons. Attention had both preparation overhead and a large long-context computation. Profiling could identify which part was worth changing. I kept the projection source and its results separate while evaluating these other problem contracts.
Candidate 005 fuses preparation
The attention preparation path includes splitting the fused projection output, normalizing queries and keys, applying rotary position transforms where required, and writing new cache entries. Candidate 005 fused compatible preparation work rather than change what keys the attention must consider. This can reduce intermediate writes and launch boundaries. The hard part is preserving position indexing, cache locations, scale handling, and numerical behavior. A fused implementation that writes the wrong cache row can corrupt later attention even if some immediate values look plausible.
Sliding and full attention differ
A sliding layer attends over its specified recent window, while a full layer attends over the entire allowed context. Their costs and scheduling behavior differ. The workload includes long contexts, grouped-query heads, and paged cache metadata. The preparation kernel is only one part of this path. For some large full-attention cases, the main attention kernel accounted for almost all profiled GPU time. That limited how much another preparation-only improvement could accomplish on those cases.
The official attention result
Candidate 005 passed and independently scored about 1.1323 on the attention problem. That is a useful improvement for its own defined workload. It is not a 1.13 multiplier that can be multiplied directly by my projection score to get a whole-model result. The baseline time shares, workload composition, and integration behavior matter. I keep the result on its own branch of the experiment tree, linked to its actual problem and source.
Candidate 012 explores local split choices
A later attention branch explored sliding-attention split choices and related partial-output merging. The motivation was to reduce scheduling and merge overhead where the profile showed room, while preserving the full key set and causal behavior. Its checked result was close to the earlier attention result rather than a new dramatic breakthrough. This is another example of a reasonable hypothesis producing a small outcome. A plausible mechanism is worth testing, but its narrative should end with the actual measurement.
The lesson for the main story
Attention taught the same prioritization lesson as projections. Removing small boundaries helps only to the extent those boundaries contribute to the load. If the main long-context kernel dominates, further gains need a better main computation or data-reuse strategy. I carry that lesson back to the dense work: look at absolute time and dominant traffic, not only the elegance of a proposed fusion. The next side story, routed experts, makes the same point through irregular GEMM batches.
III · The experiment story / 32
The routed-expert side story#
The routed-expert experiments had their own tile choices and fusion opportunities. I'll keep their results separate while explaining what improved.
Uneven expert popularity creates uneven batches
The routed-expert problem computes only selected local experts, and expert popularity is skewed. A few experts may receive many tokens while others receive few or none. Implementations often group token-expert pairs and pad work to tile boundaries. Padding simplifies kernels but can waste substantial work when local counts are small. Choosing alignment and tile size therefore changes both the useful arithmetic fraction and how effectively tensor-core kernels execute. This is a different optimization landscape from one fixed dense matrix product.
Two low-bit matrix products
Each expert applies a first projection producing gate and up features, a SwiGLU transformation, and a second projection. The weights follow the specified NVFP four representation, while activations stay in their required format. Efficient dequantization and matrix scheduling are central. The baseline used Marlin paths for the important expert products. Profiling showed those products consuming a large share of GPU time, especially at larger token counts, so improving only a small surrounding normalization had a limited ceiling.
Candidate 010 fuses post-expert work
Candidate 010 reorganized the post-expert normalization and weighted combination work. The required normalization applies to each expert output before its route contribution is combined. That dependency matters: moving normalization after summation would be a different computation. The fused path aimed to reduce intermediate work while preserving that order. Its independent scored result was about 1.1454, establishing a useful expert improvement before the later tile-policy change.
Candidate 006 was a warning about alignment
An earlier local-tile or alignment experiment, candidate 006, checked at about 0.9945. It did not establish a win. This negative result mattered because changing several alignment assumptions can alter both padded work and kernel efficiency. A smaller local count is not automatically a faster call. The next useful experiments separated the tile-size hypothesis from earlier alignment changes, making the comparison easier to interpret rather than repeat the same broad adjustment.
Candidate 013 finds a better middle regime
Candidate 013 retained the validated earlier small-batch path and used a token tile size of sixteen for the selected larger-token region. The checked result was about 1.2706, and the independently scored result was 1.2684. This was a meaningful expert-track result. It illustrated how a modest dispatch or tiling change can outperform a more ambitious restructuring when it better matches the actual distribution of work.
What the side story contributes
The expert branch reinforced three habits. Inspect the actual distribution of local work. Preserve the placement of nonlinear operations and normalization. And choose tile policies from complete captured measurements rather than assume bigger or smaller is always better. Its score belongs to the expert problem, not my projection milestone. Later, when I discuss whole-layer composition and serving, these separate results become evidence about opportunities and limits in the larger model path.
III · The experiment story / 33
Why whole-layer gains were smaller#
Why didn't component wins turn into the same whole-layer speedup? Other calculations and integration costs were still there.
Assemble the full local computation
The whole decoder layer combines the projection paths with attention, routing, experts, normalizations, gates, and residual updates. Candidate 011 integrated validated components into that larger contract. The output includes more than one dense tensor, and the routing behavior is also part of validation. Integration therefore required more than pasting fast functions together. Each component had to receive the expected layout and values at the correct point in the dependency graph.
The whole-layer result
The candidate checked at about 1.0933 and independently scored about 1.0953. That was an improvement over the whole-layer baseline, but smaller than some standalone component ratios. It was not a contradiction. The integrated workload has its own distribution of time and overhead, and not every component improvement applies equally to every layer or load. The full-layer test is the experiment that answers the composition question.
Amdahl explains a large part of the intuition
If an expert computation occupies a large share of a load, a small projection improvement has a limited total effect. If long full attention dominates another case, fusing a few preparation steps may move the total only slightly. The shares differ across loads, so one component's headline ratio cannot summarize the layer. An accurate prediction would need the actual baseline time shares and compatible candidate timings, followed by a validation run. Without those ingredients, multiplying component speedups is just the wrong arithmetic.
Integration can introduce its own costs
A component may return a view or layout that is efficient locally but forces a copy before its consumer can run. A fusion may retain more temporary state and reduce occupancy. Separate normalizations and residual paths may remain on the critical path even after a matrix product improves. These are possible mechanisms to inspect, not a claim that every one caused my measured difference. The general lesson is to profile the integrated execution and trace actual tensor transitions before assigning a precise cause.
Do not hide the smaller result
A success story focused only on the strongest number would omit the whole-layer branch. That would hide a central engineering lesson: local improvements have a scope. I preserve the 1.0953 result alongside the stronger component results and attach each to its own problem. This gives me a more useful understanding of what has been accomplished. It also keeps the later serving discussion honest, because serving adds still more scheduling and communication beyond this local layer.
Return to the projection target
My immediate target was the projection score. The side tracks expanded the investigation and improved other workloads, but they did not satisfy that target. I therefore return to the projection branch with the packed-router incumbent and a clearer prioritization framework. The next set of experiments explores dense matrix layouts, optional kernels, wider K tiles, and library alternatives. The goal is a fresh improvement in the same defined projection workload, not a more impressive number from a different task.
III · The experiment story / 34
Transposes, wider K, and QuACK detours#
Some ideas changed memory layout. Others failed at the library interface before timing. I needed to fix the second kind before drawing a performance conclusion.
Three plausible dense hypotheses
Candidates 014, 015, and 016 probed different dense opportunities. The first used an optional Hopper GEMV route for selected single-token work. The second stored lossless transposed weights to alter the matrix layout presented to cuBLAS. The third explored wider K tiles in a custom dense design. All were plausible responses to the remaining profile. None could be selected merely because the hardware feature or library sounded more advanced than the incumbent.
Read their actual checked outcomes
The recorded checks were approximately 1.1481 for the Hopper GEMV candidate, 1.1680 for transposed dense weights, and 1.1353 for wider K. These are aggregate results for the complete candidates. The transpose branch showed useful potential, while simply widening K did not establish a stronger complete result. A small combination of the measured changes was still well short of 1.30, so another step in implementation was necessary.
The QuACK branch fails before timing
Candidates 017 and 018 attempted QuACK paths and failed during execution. The investigation identified an integration requirement: the chosen low-level split-K interface expected batched, rank-three operands. This is an important point in the story because the correct response was to fix the operand interface, not declare the library slow from a run that never completed. An experiment must reach a valid timed state before it can answer a performance question.
Repair the rank with views
The repaired candidates introduced an outer batch dimension through unsqueezed views for inputs and output. That changed the interface shape without copying data or reducing precision. Candidates 019 and 020 then passed, checking at about 1.0009 and 1.1221. The full paths were not compelling replacements for the stronger incumbent. The branch now had a valid performance outcome, distinct from its earlier API failure.
The odd-shape transpose hazard
Reformulating a matrix product can create an output whose leading dimension is the token count. A favorable alignment at 128 or 256 can disappear at a neighboring odd value. The handoff records severe nearby-shape slowdowns in some transposed orientations. This made generality checks essential. Later library-layout work retained baseline fallbacks for alignment conditions, rather than publish a path that won the scored matrix and collapsed on legitimate nearby inputs.
What survived this round
The surviving lessons were more specific than a library ranking. Transposing static weights could help particular layers. Optional GEMV and custom tile choices needed per-shape selection. A repaired advanced library could still lose on this workload. And every new output layout deserved nearby-shape checks. These findings fed the measured bundle and later systematic searches. The investigation advanced by preserving useful pieces and rejecting full paths that did not earn their place.
III · The experiment story / 35
Systematic vector and library searches#
Instead of guessing one setting at a time, I searched related configurations. The hard part was keeping the search valid and retesting promising results.
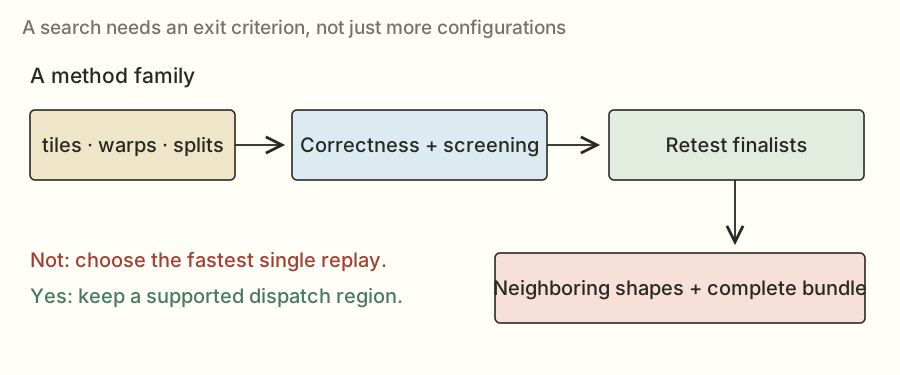
A search needs an explicit hypothesis space
Instead of changing one number repeatedly without a record, the next candidates explored defined families. Vector kernels varied output rows per block and warp counts. Router designs varied token tiles, output tiles, K tiles, splits, and reduction strategies. cuBLAS Lt searches varied operand layouts and validated algorithm choices. Each family represented a mechanism I could explain. Bounding the space made the search reproducible and prevented compilation or preparation from consuming the whole run.
Candidate 022: reusable library plans
The cuBLAS Lt plan search explored how an equivalent product could be presented to the library and which suggested algorithms were valid. Plans were reused rather than performing expensive heuristic selection on every timed invocation. FP32 compute and acceptable reduction schemes were retained. The complete checked result was about 1.1590. That alone did not establish the target, but per-shape results could identify useful regions for a later combined policy.
Candidate 023: direct vector reductions
The vector search explored direct reductions for the smallest-token regime. A block's row grouping and warp count influence memory streams, register distribution, and the final reduction. The checked aggregate reached about 1.1815, stronger than several earlier dense branches. I still needed to examine which layer shapes produced that benefit and avoid assuming the same settings would help larger token counts. A direct vector method is a regime-specific tool, not a substitute for all matrix multiplication.
Candidates 024, 025, and 027: router alternatives
Several router searches examined tile choices, paired high/low layouts, and fused reduction ideas. Their complete checked results stayed around 1.14 to 1.15. A design that reduced a launch count did not automatically beat the best composed route. Counter logic, global partial traffic, and repeated activation loads could outweigh the proposed benefit. The exact microarchitectural cause was not always established, but the complete timings were sufficient to avoid promoting those candidates as aggregate winners.
Candidate 028 broadens algorithm choices
The expanded library search considered validated split, tile, and stage variants beyond a narrow default choice. It checked at about 1.1783. This broadened the evidence without proving that exhaustive search would be efficient or that one algorithm index would generalize to every neighboring shape. The later C2 investigation would revisit library orientations more explicitly. At this point, the important outcome was a collection of candidate paths with measured strengths that could be composed carefully.
Screen, retest, then compose
A broad search should spend fewer repetitions screening clearly poor configurations and more repetitions on finalists. The finalists also need fresh-input correctness, outliers, and neighboring shapes. Only after that should complementary methods enter a combined source. This process cannot remove all selection noise, but it is stronger than choosing the fastest single replay from thousands of trials. It also gives a clear explanation of a decision: a method was kept because repeated measurements supported a useful region, not because its best isolated number looked exciting.
III · The experiment story / 36
Composing gains into 1.1993×#
Putting several useful methods in one file creates a new candidate. Its preparation, dispatch, and full workload still need another complete test.
A bundle is a new experiment
Candidates 021 and 026 combined selected methods from earlier measured branches. The source snapshots were hash-named to preserve their exact identity. A combined dispatch may reuse correct component functions, but it is still a new experiment. Its preparation can differ, its selected paths can interact through memory footprint or layout, and its complete score follows all six loads. I therefore validate the bundle rather than multiply the component scores and declare the result established.
Preserve the best regime of each method
The bundle strategy selected paths for particular layer and token families rather than replace every projection with one library or custom kernel. The exact selections are preserved in source and selection files. This is a pragmatic form of algorithm design: one path streams efficiently at one token, another handles a small batch, and a library remains preferable for a larger matrix. The challenge is to keep the dispatch understandable and supported by measurements, instead of accumulating unreviewable special cases.
Candidate 021 establishes a modest combined result
The earlier measured bundle, candidate 021, checked at about 1.1623. That was useful evidence but still far below the requested 1.30. The estimated benefit of a few obvious dense changes was limited, so the investigation continued into broader method selection. The important decision was to avoid treating a passing combination as completion merely because it improved part of the source. The target required an independently scored projection result at or above the requested threshold.
Candidate 026 reaches the next milestone
The expanded bundle checked at about 1.2099 and independently scored 1.1993. The check-to-score difference was recorded rather than hidden. The scored result became a new milestone, but it remained short of 1.30. This is a useful place to pause: the project had made substantial progress from the initial slowdown, yet the remaining gap still required more than polishing a result card. The code needed another genuinely better set of execution paths.
Why percent gains do not stack freely
A method's local advantage applies only to the cases where it is selected. Those cases contribute different absolute times inside a load, and the six load ratios are then geometrically averaged. A five-percent improvement in one small component can have a tiny effect on the complete score. Meanwhile, a hidden regression in a larger component can erase it. The bundle must therefore be judged by its complete measured path. Selection heuristics help narrow choices but are not a substitute for that final evaluation.
Prepare a useful handoff
The next stage benefited from a handoff that preserved the incumbent, the tested alternatives, and the practical remaining gaps. This is how multiple agents can contribute without repeatedly rediscovering the same failures. A useful handoff includes exact sources, commands, environment settings, observed bottlenecks, and untested hypotheses labeled as such. It should make the next experiment easier to justify, while leaving the previous best reproducible. Candidate 029 and the custom H200 lab work followed that accumulated evidence.
III · The experiment story / 37
The handoff and the measured best-of plan#
The handoff saved useful experiments and remaining gaps. It let the next round start with a working map rather than repeat every earlier attempt.
What the Claude handoff established
The saved Claude handoff describes the H200 lab, the benchmark method, the best selected source, and several failed families. I can attribute that artifact and its documented work without inventing a transcript of private thought. It records useful practical read floors and highlights remaining projection gaps. Those observations helped the next round focus on QKV, small-batch pooler, and router behavior rather than restart every earlier library experiment from scratch.
Candidate 029 chooses among measured methods
Candidate 029 was a best-of dispatch over methods that had been explored and validated. Its official check returned about 1.2564. The result represented a stronger composed policy rather than one new universal kernel. The source supported several routes, allowing experiments to select by layer and token range. This organization made further work more efficient: a new method could be compared against the incumbent for a specific region and included only if it earned that region.
What stayed with the libraries
At larger token counts, library matrix products remained difficult to beat across many dense shapes. The handoff reports alternatives including DeepGEMM, FlashInfer, QuACK, CUTLASS, and custom large-batch kernels that failed to provide a better complete path in the tested regimes. That is not a universal ranking of those libraries. It is a record about these shapes, this environment, and these implementations. Retaining the library where it wins is a positive engineering decision, not evidence that the custom investigation was incomplete.
Practical read floors narrow expectations
The read probes suggested that many dense kernels were already not far from practical streaming times. They also showed that a kernel needed enough concurrent memory streams to use the device well. That explains why reducing arithmetic alone was unlikely to produce a large single-token gain. It also suggested that small tile grids and repeated activation reads could matter. These were testable directions, not guarantees, and the later searches would confirm some while rejecting others.
The next router decision
The source contained several ways to combine split-router work. A promising next route used FP32 atomic additions into a freshly zeroed output, avoiding a separate final reduction over a partial tensor. The complete call still included output initialization. The intended benefit was to shorten the combination path enough to improve the relevant token ranges. Candidate 030 tested and scored that direction, producing the next major milestone.
A handoff is a map, not a prophecy
The handoff also included proposed future directions and observations that were necessarily incomplete. I treat those as hypotheses. A profiler limitation can prevent a definitive microarchitectural explanation, and a practical floor can be specific to its probe. The correct use of a handoff is to preserve what was established, understand what remains uncertain, and choose the next experiment accordingly. This habit is essential when several agents work on the same optimization without a single continuous private memory.
III · The experiment story / 38
Atomic router: reaching 1.2785×#
Could each router split add directly to the output? Atomic addition helped, as long as I also included the fresh zero-fill and checked the arithmetic.
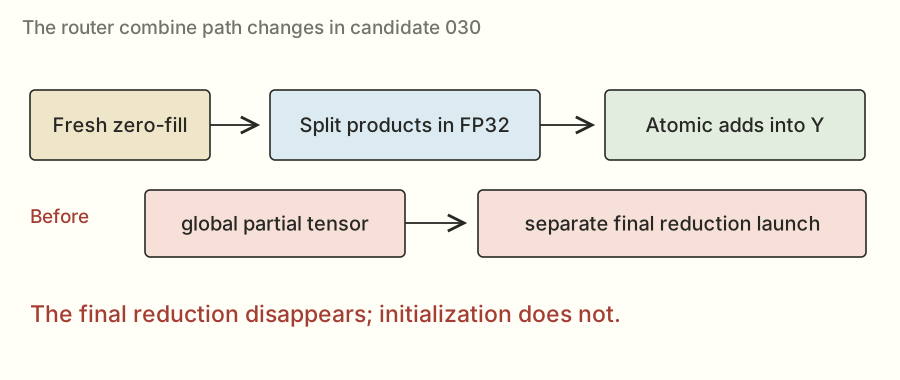
The dedicated reduction was a target
A split-router path can spend useful time computing partials and then additional time writing, reading, and reducing them. Candidate 030 explored accumulating split contributions directly into the final FP32 output with atomics. This targeted the combination path rather than changing the high-and-low representation or relaxing its precision. It was a plausible next step because the router's small overall computation made launch and reduction overhead a meaningful part of the total.
Initialize a fresh output
Before atomic accumulation, the output must contain zeros. Reusing an output with old sums would make the next invocation incorrect. The selected function therefore allocates a zeroed FP32 output and launches the split matrix kernel against it. This is an important qualification to the phrase single-launch router: there is no dedicated final reduction launch, but output initialization still belongs to the complete captured path. The benchmark must include it, as my complete-call timing does.
Interleave high and low contributions
The router weights are arranged so corresponding high and low columns form pairs. The matrix kernel accumulates those products in FP32, reshapes the paired accumulator, combines each pair, and atomically contributes the split result. Token and output masks preserve the logical shape. This layout differs from the earlier concatenated packed library route. The difference matters because it changes which values a block loads together and how the epilogue forms each router output.
What atomics guarantee and what they do not
Atomic addition coordinates conflicting updates so one contribution does not simply overwrite another. It does not promise the same summation order every time. FP32 rounding can therefore differ slightly across arrivals. The task's strict router checks and fresh-input replay tests remain necessary. The implementation must also ensure each split contributes once to each valid output location. Correctness comes from valid indexing, the intended arithmetic, initialization, and synchronization semantics together, not from the word atomic alone.
The independently scored milestone
Candidate 030 independently scored 1.2785. This was a substantial step beyond the earlier 1.1993 bundle. It established a stronger projection incumbent while retaining selected dense paths. I keep the exact source and result linked rather than infer a score from the router-only improvement. The aggregate milestone reflects the full dispatch and all six loads, including cases where the baseline library remained the selected route.
What remained after this win
The router improvement did not remove the dense weight-traffic floor. QKV, pooler, output, and unpooler still occupied important shares of the loads. The next useful changes targeted a small unpooler slice and custom cluster reduction for small-token QKV. This is the repeated pattern of the investigation: after a successful change, inspect the remaining shape profile rather than apply the same technique everywhere. The best next hypothesis often belongs to a different part of the computation.
III · The experiment story / 39
The small unpooler opportunity#
The small unpooler slice was a smaller matrix problem than the full projection. That made a specialized tiny-matrix library route worth testing.
A small slice changes the regime
The task's small-token unpooler returns only 1,024 output features. Its K dimension is 4,096, so the relevant weight slice is much smaller than the full unpooler. A method chosen for the full matrix may have unnecessary scheduling or launch costs here. This created a focused opportunity: compare small-matrix paths for the actual local slice rather than assume the general unpooler route was optimal. The source preserved the task's shape condition rather than truncate an output that was required in another regime.
FlashInfer tinygemm as a candidate
The installed FlashInfer package included a tiny GEMM path. The experiment compared it for the small unpooler region where a specialized inference-oriented kernel could reduce overhead. This was a library selection decision based on the available environment, not a new precision approximation. The chosen path still read the original BF16 weights and activations and produced the required output. The important question was the complete captured cost at the small shapes, including any wrapper behavior.
Candidate 031 was not a standalone score milestone
Candidate 031 checked at about 1.2620 as a complete submission. That number should not be narrated as an independently scored improvement over candidate 030's 1.2785. Its useful contribution was a selected component path that could enter the evolving bundle. This distinction is a recurring source of confusion in optimization histories: a new experiment may contain a valuable local change without its aggregate check being the best final score.
Retain different one-token and few-token paths
The eventual plan kept a direct vector route at one token and used tiny GEMM for the small unpooler range above that. At larger token counts it returned to transposed library products and later an explicit library orientation for the large range. This structure reflects different sources of overhead and reuse. It also shows why names such as unpooler do not identify one universal best algorithm. The layer name plus the actual matrix geometry determines which candidates deserve comparison.
A modest component can still be worth keeping
The small unpooler does not dominate every load, so even an attractive component ratio has limited aggregate leverage. But a clean, validated improvement in a stable shape family can still contribute useful microseconds without adding excessive complexity. I evaluate it as one piece of the final policy. The next QKV work targeted a larger weight stream, where enough absolute time remained to matter across the small-token loads.
The decision that survived
The final source did not adopt every FlashInfer backend or use tiny GEMM for every projection. It retained one specific measured route for the specified unpooler regime. That is the right resolution of the experiment: a capability was available, a concrete shape made it plausible, measurements supported a useful region, and the dispatch kept that region. This is more informative than declaring one library faster than another without naming the shape and complete call being compared.
III · The experiment story / 40
Custom cluster QKV: reaching 1.2888×#
This QKV kernel combined partial results through cooperating blocks' shared memory. The barriers mattered as much as the matrix instructions.
Why QKV remained a target
The small-token QKV projection streams about thirty 7.7 megabytes of weights. Its execution remained above the practical read floor, and its skinny token dimension made ordinary large-GEMM strategies awkward. The custom cluster design attacked the long K reduction and data movement together. It used tensor-core arithmetic within blocks and split contributions across a cooperating block cluster. The goal was not to eliminate required work but to schedule it so more of the machine contributed effectively.
Stage swizzled weight and activation tiles
The CUDA kernel asynchronously copies tiles into shared memory. The shared tile stores weight rows and token rows, with a swizzle designed for its matrix-load pattern. Several stages allow a future tile to be in flight while the current tile computes. Threads then load register fragments and issue BF16 matrix products with FP32 accumulation. Each block owns a K subset and a set of output rows. The staging layout and fragment ownership are explicit in the native source.
Reduce through the block cluster
After finishing its local reduction, each block writes its FP32 accumulator into shared memory. The cluster synchronizes so peer partials are available. Blocks then read distributed shared-memory partials in a defined rank loop and write their assigned final output elements in BF16. A final cluster barrier protects the shared memory's lifetime. This replaces a separate global reduction path with cluster cooperation, whose own synchronization cost has to be repaid by better execution.
Candidates 032 and 033
Candidate 032 checked at about 1.2712. Candidate 033, with the selected deeper cluster QKV configuration, checked at about 1.2771 and independently scored 1.2888. These are complete projection results. The cluster path was selected for the appropriate small-token QKV range, while the other projection families retained their chosen methods. The source therefore joined a specialized native kernel with vector, Triton, and library routes.
The next official incumbent
The 1.2888 result became the incumbent for the C2 round. It was archived with source and result evidence. I wanted at least 1.30 and then 1.32, so this result was progress rather than completion. It also came with a measured map of remaining gaps: QKV at other token ranges, small pooler behavior, larger router activation rereads, and dense paths already close to library performance.
What this design did and did not prove
The selected kernel showed that a carefully matched custom CUDA design could help this skinny QKV regime. It did not prove that custom CUDA beat cuBLAS at larger token counts, or that adding more stages would continue to improve it. Later sweeps tested deeper variants and did not find another useful win. This is the boundary I carry forward: preserve the successful region, keep its mechanism understandable, and make the next experiment earn a separate region rather than extrapolate from one victory.
IV · The H200 investigation and the finish / 41
Building our remote H200 laboratory#
The GPU ran remotely, so a useful experiment needed more than code: a matching environment, a working benchmark, recovered logs, and a machine that wasn't left billing idly.
A local Mac controls a remote GPU
The editing workspace was on the Mac, while the performance experiments needed an H200. The lab synchronized source and the supplied problem files to a Runpod machine, then ran correctness and timing through SSH. Results were copied back into the workspace. This separated authoring from execution without changing the submitted computation. The submission itself did not contact the network. Remote orchestration happened outside the evaluated source, as ordinary experiment infrastructure.
Match the judge image and verify readiness
The pod used the specified SGLang development image and a CUDA-compatible H200 host. A running status alone was not enough to establish a useful lab. I checked SSH access, the visible GPU, framework versions, and machine settings before trusting performance work. The recorded environment used PyTorch two point fourteen point one with CUDA thirteen and Triton 3.8. Those details helped keep the kernel and compiler behavior close to the official environment, while still requiring official checks.
The lab benchmark and correctness runner
The benchmark captures candidate and baseline calls as graphs, rotates independent weight states, supplies fresh inputs, flushes L2, swaps execution order, and records paired ratios. The correctness runner uses the supplied reference, difficult official cases, scored shapes, outliers, neighboring token counts, and fresh graph replays. Keeping these tools stable matters. Changing the benchmark to make a candidate look better would invalidate the investigation. I changed candidate methods while preserving the measurement and reference contracts.
The profiler limitation
Nsight Compute hardware counters were unavailable on the Runpod host because the required performance-counter permission was not exposed. The handoff records the corresponding permission error. I could still use available timing and activity profiling, but I could not pretend to have counter evidence for occupancy stalls or memory behavior that had not been measured. This limited some causal diagnoses. I could establish that a candidate lost and offer a plausible explanation, while labeling the explanation as a hypothesis requiring deeper profiling.
The cost of leaving allocation idle
The pod's quoted compute price was five dollars and 29 cents per hour. The recorded bill for the first session reached about 37 dollars and fifty cents, including allocation after productive searches had ended. The pod was already stopped when work resumed later. That was an operational cost, not a hidden amount of successful optimization. A better workflow needs evidence synchronization and verified compute shutdown, especially when a turn can be interrupted or a long job completes unattended.
Resume with the evidence intact
The stopped disk retained exploratory logs. A later restart was initially rejected because the account lacked credit; I added funds, and the pod became reachable again with a new SSH port. The recovered broad library-search log showed a time limit rather than a completed breakthrough. This sequence belongs in the story because operational state affects what can honestly be claimed. Prepared source, a scheduled job, a completed run, and a recovered result are four different states.
IV · The H200 investigation and the finish / 42
The packed pooler experiment#
For the pooler, I tried keeping each output tile's weights together. The original values stayed the same; their addresses changed.
The C2 hypothesis
The pooler had a large weight stream and a small output-tile grid at low token counts. The C2 packed design rearranged the original BF16 weights into contiguous regions for each output-feature tile. The hypothesis was that a block could stream its owned K-by-output region efficiently and accumulate the output directly, avoiding a split reduction for this regime. Preparation paid the lossless repacking cost once, leaving fresh activations for the timed kernel.
What the packed tensor means
Start from a stored weight with N rows and K columns. Group N into blocks of BN output features, then reorder each block so K steps contain adjacent output columns. The packed representation has a conceptual shape of N divided by BN, then K, then BN. Every original BF16 value has a new address but the same value. The kernel selects its output tile, streams along K, and uses a dot product to update a FP32 accumulator for its token tile.
Tune a balanced tile
The search varied token tiles, output tiles, K widths, warps, and pipeline stages. The included pooler choices used output tiles of 32 features. For the smaller token range, the selected configuration used a sixteen-row token tile and K width 512; for the next range it used a 32-row token tile. The stage count differed. These values balanced streaming, grid size, shared-memory use, and dot-product efficiency. The search results, rather than a single theoretical rule, selected the final combinations.
Repeated pooler gains
Local paired screening and retesting found useful gains in the small-token pooler cases. The exact ratios varied across runs, but the selected regions repeatedly improved by several percent rather than rely on one isolated replay. Finalists were checked on fresh inputs and neighboring shapes. That made the packed path worth including in a combined candidate. It did not by itself establish a 1.32 complete score, because the pooler occupies only part of each of several loads.
Candidate 034 did not beat the official incumbent
The first combined packed-and-library candidate, 034, passed its official check at about 1.2852. That was below the 1.2888 scored incumbent. I did not turn the local pooler win into a claim of official aggregate progress. Instead, the per-shape evidence remained useful while the combined design needed further work. This is exactly why complete official evaluation follows local selection: a promising part can coexist with an unimproved whole result.
What I carried forward
The packed pooler route remained a measured candidate for selected small-token regions, while the larger pooler and QKV ranges invited more explicit library-layout choices. The next round expanded cuBLAS Lt orientations and algorithms. I preserved the original incumbent and created new immutable snapshots, so a losing combined check could not overwrite the verified best. This allowed exploration to continue without confusing the current experiment with the current proven result.
IV · The H200 investigation and the finish / 43
Exploring cuBLASLt orientations#
An equivalent matrix product can look different to a library. I tried layouts and algorithm choices, then checked the neighboring sizes too.
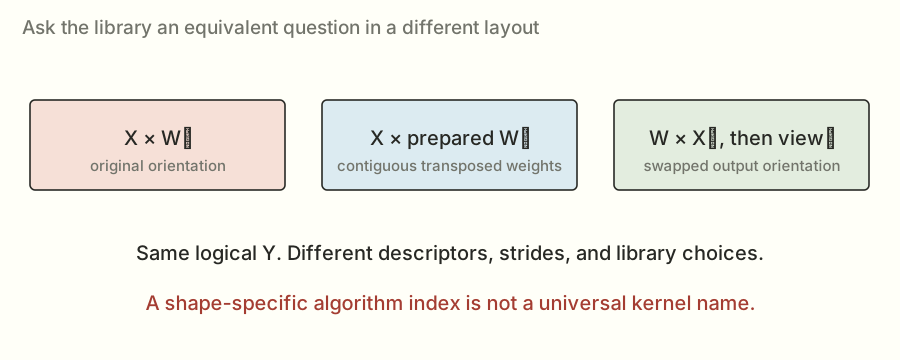
The library sees a layout, not just an equation
cuBLAS Lt chooses among implementations based on matrix descriptors, dimensions, types, strides, workspace, and algorithm settings. Two mathematically equivalent products can therefore lead it to different execution paths. My C3 and C7 work explored the original weight orientation, a lossless transpose, and swapped products returning a transposed output view. The objective was to expose a faster valid algorithm for a shape family, while preserving the original values and the required accumulation behavior.
Constrain the reduction scheme
The extension requested FP32 compute and restricted split reductions to the compute-type scheme. Lower-precision output-type reductions were excluded from the intended search. This matters because a BF16 output tensor does not tell me how intermediate split results were combined. Workspace was allocated for valid algorithms, and algorithm checks screened configurations before execution. Those safeguards did not replace numerical tests, but they aligned the search with the required precision rather than let a cheaper reduction silently change the problem.
Heuristics, splits, and retesting
The search enumerated library heuristics and additional validated split choices for several orientations. It timed captured calls against the incumbent, then retested finalists with more repetitions and neighboring shapes. Algorithm positions in a heuristic list can differ with shape, so a configuration that looks strong at one M can choose an unsuitable path nearby. This was one reason to inspect neighboring behavior rather than treat an index as a universal algorithm identity.
Useful regions emerged
The expanded orientation search found useful local improvements for the larger pooler, QKV around 32 tokens, and the large unpooler range. Some nearby configurations looked good at a scored shape but regressed badly at a neighbor and were rejected. The selected combined source retained different orientations and indices for the supported regions. These were library dispatch improvements, not a new approximation to the matrix product. Their per-shape contribution is visible in the later official result and the shape atlas.
Add alignment-based fallbacks
Swapped-output products make M the leading dimension of the allocated transposed output. For the selected routes, token counts not divisible by eight retained the original path instead of forcing an unfavorably aligned swapped layout. The pooler also retained the original transposed path through an intermediate token range where the newer plan regressed. These choices made the dispatch more robust across neighboring shapes. They expressed layout and range conditions rather than pretending the faster orientation was universal.
Candidate 035 stayed around the incumbent
The layout-focused candidate 035 passed its official check at about 1.2860. The local bundle had looked promising, but this official result still did not beat the earlier scored incumbent. I preserved the useful shape-level evidence and continued looking for another complementary gain. This is an important narrative point: the last step over 1.30 did not come from declaring the layout search successful enough. It required the later single-token streaming improvement and another independent evaluation.
IV · The H200 investigation and the finish / 44
Lossless compression: fewer bytes, slower execution#
Reading fewer bytes sounded useful. The lossless compression attempts also had to decode those bytes, and that extra work overwhelmed the savings in the tested versions.
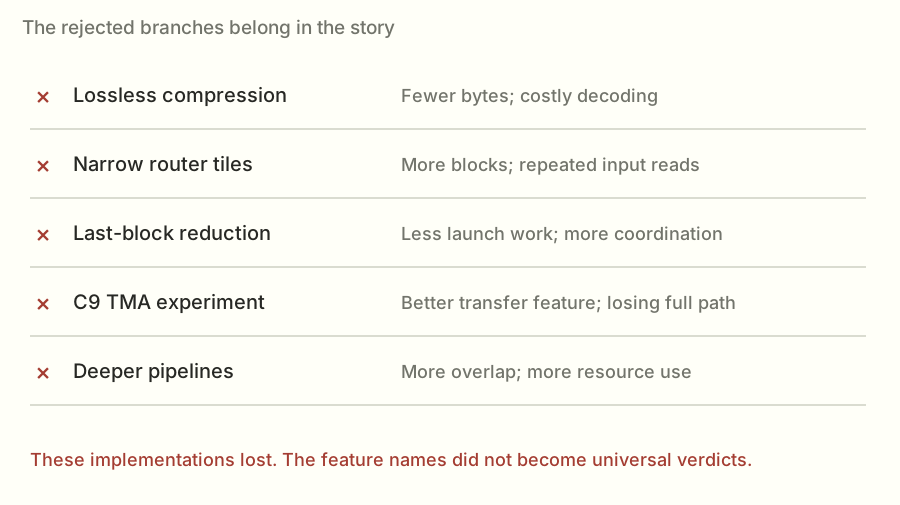
A tempting response to the bandwidth limit
The large dense weights made a lossless compression experiment plausible. If fewer stored bytes could be read and reconstructed cheaply inside the kernel, a memory-bound projection might improve without changing required values. The word lossless is essential: the original BF16 bit patterns had to remain recoverable. These experiments were not attempts to replace the dense weights with lower-precision approximations. They explored representations whose decompression cost might be repaid by a smaller external-memory stream.
Blocks, metadata, and escapes
The compression branches explored different ways to exploit structure in BF16 values. Some packed portions of the exponent or mantissa information, used block metadata, or kept escape paths for values that did not fit a compact local representation. Such schemes add addressing logic and integer instructions. An escape path can require another original-weight read. A block's metadata must also be fetched and interpreted. The compressed byte count therefore describes only part of the new execution path.
Register pressure can erase a bandwidth saving
A direct projection already needs input values, weight values, products, and reduction state. A decoder may add bit masks, shifts, offsets, metadata, and intermediate representations. That can increase registers per thread and reduce residency. It may also serialize instructions before the arithmetic can proceed. These are plausible mechanisms to inspect when compression loses, but timing alone does not prove their exact share. The measured fact in my branch was simpler: the tested exact encodings were too slow for the selected regime.
The C4 through C6 outcomes
The lossless branches preserved the required arithmetic in tested cases but performed far below the incumbent in the local searches. Some configurations were less than half as fast as the existing route. That is not a small tuning loss to hide within measurement noise. The byte reduction was overwhelmed by the complete execution cost. I therefore rejected the compressed methods for the winning bundle and kept the reports as evidence of a tested hypothesis that did not work in these implementations.
The model needs a new cost term
A bandwidth-only prediction compares original bytes with compressed bytes. The actual compressed kernel also pays decode instructions, metadata movement, possible escapes, and any resource-efficiency loss. If that added cost exceeds the saved memory time, total execution gets worse. This is a useful refinement of roofline reasoning: reducing one resource demand can introduce another limiting demand. I do not abandon modeling after a failed prediction. I update the model to include the work the implementation actually performs.
The decision was to move on
There may be other lossless encodings or architectures where this idea helps. My evidence does not disprove compression in general. It does establish that these branches did not earn a place in the current dispatch. The rational next decision was to preserve the negative results and focus on better-supported opportunities, including launch sizes, cache policies, and library orientation choices. An honest optimization story can end a technically interesting chapter with a rejection rather than force every idea into the final design.
IV · The H200 investigation and the finish / 45
Router redesigns that did not help#
These router redesigns moved tile, read, and combine costs around. None of these tested branches earned a place over the atomic incumbent.
A smaller matrix can still be difficult
After the atomic-router improvement, the remaining router calls were short enough that overhead and repeated input reads mattered. The C2 round tried several reorganizations rather than assume the existing method was optimal. These included changing where high and low weights were interleaved, narrowing output tiles, and packing partial results for a fused final reduction. Each design preserved the intended high-plus-low computation. The open question was whether a better access or synchronization pattern would beat the complete atomic path.
C8 interleaves along the reduction dimension
One design placed high and low contributions along an expanded K-like dimension and loaded the corresponding input value for each pair. The attraction was a unified dot-product path. The cost included a new operand layout and duplicated input use. Local screening found the tested configurations slower, increasingly so in some larger token cases. The result showed that simplifying the source expression did not simplify the generated execution enough to help. I retained the report and excluded the method from the final bundle.
C11 explores smaller output tiles
Smaller output tiles can create more independent blocks from the same router width. That sounds attractive when the output grid is small. But each tile may reread activations, and a narrower dot-product shape can be less efficient. The C11 sweep varied token, output, K, split, and launch choices. Its best tested finalists still did not provide a useful improvement over the incumbent. The search narrowed an opportunity rather than support the simple rule that more blocks must be faster.
C14 packs partials for an in-kernel reduction
Another branch wrote split partials into a tile-local packed buffer and let the last completing block reduce them. It explored different partial layouts, including which dimension made the split contributions contiguous. This targeted the combination path and memory layout together. But it still paid partial writes, counter synchronization, last-block reads, and a final sum. Sampled results were clearly slower than the atomic incumbent, so the search was stopped rather than spend more GPU time on an unpromising branch.
What the rejection establishes
The measurements establish that these implementations did not improve the tested regimes. They do not prove every possible version of the ideas must lose, or isolate every hardware reason without counters. That distinction lets the evidence remain useful. A future design could remove a specific cost and deserve another test. For the current result, however, none of these router branches entered the winning submission. Keeping a correct, measured incumbent was better than promoting a more elaborate but slower path.
A new router idea remained only a proposal
Later source preparation explored a block-cluster router using distributed shared-memory reduction, adapting ideas from the useful QKV kernel. In the record available to this written companion, that later design was prepared but not validated as a winning experiment. It therefore belongs on a proposed branch, not on the path that achieved 1.30. Showing this boundary is part of an honest story: writing code and having a plausible mechanism are not the same as completing correctness and performance evaluation.
IV · The H200 investigation and the finish / 46
Advanced features that still lost#
New hardware features and deeper pipelines were worth trying, but they still had to win a complete timing. Here are the versions that didn't.
C9 tests tensor-memory transfers
The C9 branch used Triton tensor descriptors to test Hopper tensor-memory transfers for dense matrix products. It explored tile sizes and split choices, with FP32 accumulation and the required BF16 output. This was a concrete TMA experiment, not merely a suggestion in a strategy document. The full design still needed a good schedule, sufficient reuse, efficient arithmetic, and an acceptable reduction path. A more capable load mechanism could not guarantee those other requirements were satisfied.
The TMA result did not beat the incumbent
The tested TMA configurations failed to provide a useful local win for the target shapes. Some larger pooler configurations came close, while other shapes were substantially slower. The search did not establish that tensor-memory transfer hardware is ineffective. It established that this particular implementation and parameter family did not outperform the existing route. A more complete persistent or warp-specialized design would be a different experiment and should not be credited with a result that had not been measured.
C12 deepens the cluster search
The deeper QKV cluster sweep varied stage counts, warps, and K widths across additional compiled instances. The chosen incumbent configuration remained difficult to beat in its useful small-token regime. Some variants looked close enough to be noise, while many were worse. Adding pipeline depth can consume shared memory, change residency, and exceed the useful overlap available in a short per-block loop. The result supported keeping the existing path rather than assume the next level of staging would produce another milestone.
C13 refines the packed pooler
The pooler refinement revisited output tiles, K widths, warp counts, stages, and load cache policy. The best choices were broadly consistent with the already selected packed path. A .cg variant could look slightly better in one retest without establishing a clear incremental aggregate gain. This is where search discipline matters: replacing a validated configuration based on a tiny noisy difference can create churn without progress. I kept the clearer wins and treated marginal alternatives as uncertain.
Why advanced designs can disappoint
A feature can improve one part of a kernel while another part becomes limiting. TMA may improve movement but leave too few useful tiles. More stages may improve overlap but reduce resident work. A wider tile may improve reuse but lower grid parallelism. These examples are mechanisms to examine, not universal diagnoses of every failed variant. The useful habit is to compare the complete resource tradeoff with the practical limit suggested by the workload, then let correctness and paired timing decide.
The search returns to a simpler opportunity
After these complex branches, the next useful gain came from the single-token vector path: launch width and cache behavior. That is not a moral that simple code always wins. It is a reminder that the best remaining opportunity can be a concrete mismatch in an existing method, even after exploring sophisticated hardware mechanisms. I returned to the measured path, changed a small set of meaningful parameters, and found a complementary gain that the combined candidate could use.
IV · The H200 investigation and the finish / 47
The final single-token streaming gain#
The next gain came from revisiting an existing one-token path: how many warps it used and how it treated the large weight stream in cache.
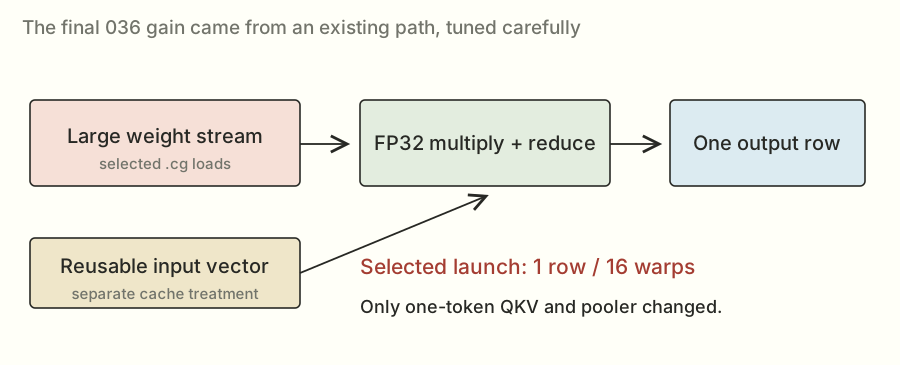
One token still streams millions of weights
The direct single-token kernel loads an input vector, reads weight rows, multiplies in FP32, and reduces each row. It does not reuse a weight across many token rows because there is only one token. Efficient streaming and lane distribution are therefore central. The C10 sweep revisited output rows per block, warps per block, and cache policy. This was a focused hypothesis about how the existing reduction used the memory system, not a new approximation or a larger model change.
Change the warp distribution
A block with more warps distributes the row's values across more lanes. That can change instruction count per thread, register use, reduction structure, and residency. The selected sixteen-warp choice helped the QKV and pooler single-token cases in repeated local measurements. Other layers did not show the same clear opportunity, so the final plan did not apply the change everywhere. The later 32-warp check is a useful counterexample to the idea that more parallel lanes must continue to improve performance.
Stream weights with the selected cache policy
The winning single-token variants used .cg weight loads. The input vector's reuse differed from the much larger weight stream, so the kernel could treat those access patterns differently. Earlier policy combinations also exposed assembly constraints: a configuration that combines unsupported load and eviction attributes can fail before performance is measured. The corrected sweep separated valid policies and launch choices. That preserved the distinction between an invalid generated instruction sequence and a valid kernel that happened to be slow.
Retest the useful gains
The single-token sweep found around six to seven percent local QKV improvement and around five percent local pooler improvement in promising configurations. A later full paired comparison showed roughly six percent and just under five percent for those selected shapes. The exact ratios varied, as expected, but the effect was useful enough to combine with the packed pooler and library-layout work. Fresh-input correctness and graph replay checks remained in place. The arithmetic still used the original BF16 weights with FP32 reductions.
Only two selected dispatch entries change
The combined source changed the first QKV and pooler dispatch entries to the streaming vector method with one output row per block, sixteen warps, and the selected cache policy. Other token ranges retained the measured cluster, packed, or library routes. This small source change mattered because it affected the single-token load, which counts equally with the other loads in the final geometric mean. A modest gain in that load could complement gains already present at larger token counts.
Candidate 036 becomes the next complete test
The new vector path was added to the combined layout candidate, producing experiment 036. The full local correctness runner passed across its tested seeds, official difficult cases, scored shapes, outliers, neighbors, and fresh graph replays. The complete paired benchmark then compared this bundle with the immutable 033 incumbent. This sequence matters: the final milestone came from a freshly validated combination, not from adding two component percentages on paper and assuming the resulting source was correct.
IV · The H200 investigation and the finish / 48
Read the winning implementation end to end#
The winner was a collection of selected routes. I'll follow preparation, dispatch, fallback, and output so the final source reads as one program.
Preparation builds static representations
The winning source starts from contiguous original weights. It forms the router's high and low BF16 parts, transposes and packs the representations required by its methods, prepares dense transposes, and creates packed dense tiles. It also compiles the cluster and library extensions and reserves library workspace. No evaluated activation is available in this static phase. The later lean-preparation experiment removed unused layouts, but the officially scored 1.3012 source is the exact original 036 snapshot.
QKV chooses three regimes
At one token, QKV uses the streaming vector reduction. Through sixteen tokens, it uses the selected custom CUDA cluster path. Through 32, it uses an explicit cuBLAS Lt orientation and algorithm choice, with the alignment fallback where required. Larger token counts use the retained library dispatch. Each region corresponds to a different geometry and measured comparison. The final source is therefore a compact policy over specialized methods rather than an assertion that one kernel is best for the whole QKV matrix family.
Pooler uses packing and library layouts
At one token, the pooler uses the new streaming vector path. The small-batch ranges use the direct packed-weight Triton kernel with different token tiles and stage choices. An intermediate range retains the original transpose route, protecting nearby-shape performance. The larger selected ranges use explicit library orientations. This is where the C2 investigation contributes most of its layout work. Every route preserves the original BF16 values and produces the required dense output format.
Output and unpooler keep complementary paths
The output projection retains a direct vector method at one token and library dispatch otherwise. The unpooler uses a vector at one token, tiny GEMM for the small local slice above that, a transposed product through the medium range, and a selected library orientation for the large range. Some official output-projection cases still regress slightly relative to baseline. I keep those visible. The complete score is the result of all selected paths, not a promise that each individual shape is faster.
Router keeps exact FP32 output behavior
At one token, the router uses a direct reduction over its original FP32 weights. Larger token ranges use paired high-and-low BF16 products with FP32 accumulation and atomic combination. The method allocates a freshly zeroed FP32 output, so a new invocation does not inherit previous sums. The split and tile parameters change by token range. The complete call is captured and timed, including the initialization that supports its correctness.
Dispatch, fallback, and return
The timed entry point reads the actual input shape and the supplied layer configuration, chooses the first matching plan region, checks method applicability, and invokes the selected function. It returns a GPU tensor of the required shape and dtype. The source does not inspect reference outputs or cache evaluated answers. The exact winner's hash and official job identifier are saved in the snapshot. That identity matters more than a filename saying best, because a future edit may no longer be the source that earned the recorded score.
IV · The H200 investigation and the finish / 49
Local 1.3234×, official 1.3012×#
My local 036 benchmark looked like 1.32×. The judge recorded about 1.30×. Both measurements stayed in the notes with their actual labels.
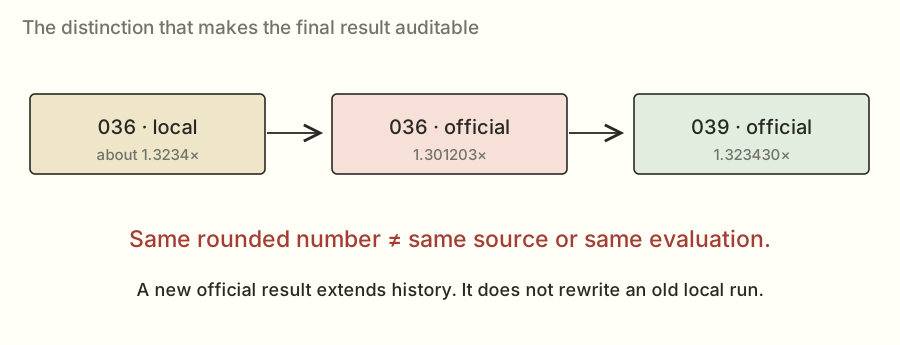
The paired incumbent comparison
The complete local bundle was compared against the immutable 033 incumbent with eight weight copies and 120 repetitions under the recorded benchmark conditions. The aggregate local gain was about 1.0241× the incumbent. That was a useful controlled comparison: both paths ran on the same machine under paired conditions. It suggested the bundle was worth official evaluation. It did not imply the same multiplicative gain would transfer exactly onto an earlier official run taken under different conditions.
The direct local SGLang comparison
The same candidate also measured about 1.3234 against the local SGLang baseline. That was an encouraging number because my later target was 1.32. But the local benchmark was not the official result. It matched important features of the judge while still differing in machine metadata and surrounding implementation details. The right response was to submit and inspect the official evidence, not declare the target guaranteed from a nearby local point estimate.
The official check
The official check passed and returned about 1.3020. This validated the source under the competition's own correctness and timing path. It also showed that the local 1.32 result did not transfer at that magnitude. The candidate still exceeded the original 1.30 milestone. I preserved the check result as its own artifact and kept the independently scored submission separate, rather than round one result into the other.
The independently scored outcome
The scored job also passed and returned 1.301203, rounded here to 1.3012. This is the result that entered the projection leaderboard. The close check and scored values supported a result near 1.30, while neither established the later 1.32 target. The official point estimate and its interval are shown together. My story ends the accomplishment at the number the evaluation actually recorded.
What could explain the local-to-official difference?
Possible contributors include driver and machine differences, measurement overhead estimates, exact baseline dispatch behavior, memory placement, and ordinary run variation. The saved records show that local and official environments were not identical. They do not isolate a single proven cause for the entire gap. I therefore present the discrepancy as a measurement lesson rather than invent a precise diagnosis. A model that explains why differences can occur is useful, but a causal claim requires an experiment that controls or measures the suspected factor.
The correct decision
The decision was to promote the exact officially scored source as the new best, preserve the earlier source, archive all evidence, and state the remaining gap honestly. The source contained real layout, dispatch, and launch improvements. The competition result crossed 1.30, and the next target still needed more work. That is a stronger outcome than a larger unsupported claim, because another person can inspect and reproduce the exact achievement and identify what remains to be improved.
IV · The H200 investigation and the finish / 50
What crossing 1.30× established#
This is what the first official 1.30× milestone established, including which benchmark it applies to and which bigger claims it doesn't measure.
The exact official artifact
The winning scored job is identified in the archive as d 296 d zero c one b 1774 e five e. You do not need to memorize that identifier. Its purpose is to connect the result to the exact source and saved evaluation. The archive includes the scored JSON, independent check JSON, local correctness and timing reports, a dated leaderboard read, and a hash manifest. The project submission was copied byte for byte from experiment 036.
Translate the ratio into time
The official aggregate baseline value is 4,830 point eight microseconds. The score-equivalent candidate value is about 3,712 point 56 microseconds. That corresponds to about twenty 3.15 percent less aggregate time under the scoring construction. These values should not be confused with a single kernel call. The individual shape timings are generally measured in single or tens of microseconds, and their load aggregation creates the reported overall quantity.
Look at the individual shapes
The official profile shows strong router ratios and useful gains in selected dense cases. For example, the one-token QKV ratio is about 1.397, while the eight-token router is about 5.16. The output projection at some larger token counts is still slightly slower than baseline. The appendix exposes all thirty cases, with their actual times and ratios. This prevents the final score from turning into an unexplained headline or a claim that every selected path won independently.
The uncertainty belongs with the number
The scored interval runs from approximately 1.2817 to 1.3207. The independent check was close to the point estimate, but the recorded uncertainty still matters. The increase over the prior best is smaller than the full width of these intervals, so I avoid claiming a precisely established causal percentage from the two official point estimates alone. The local paired and shape-level evidence helps explain the changes, while the official score states the competition outcome.
The dated rank snapshot
At the saved October twenty fourth snapshot, the projection leaderboard placed the account at eighty of 768 with 1.3012. That is historical context, not a permanent rank. Other teams continued submitting, and the leader's performance also changed. Earlier rank snapshots used different populations. The result I preserve is the evaluated source and score, while the rank is always attached to its date and board.
The accomplishment and its boundary
I started with a correct slowdown, found useful split parallelism, selected methods by shape, improved static layouts, kept strong library routes, added custom cluster QKV, and obtained a final single-token streaming gain. The resulting submission officially crossed 1.30 on dense projections. It did not establish 1.32 or a 1.30 end-to-end serving gain. Those boundaries define the next experiments. They do not erase the work that made the verified result possible.
V · What the result teaches / 51
The epilogue: tuning can regress#
The next file wasn't automatically better. A preparation cleanup was close, and the thirty-two-warp follow-up regressed.
Candidate 037 removes unused preparation
After the winning submission, the source still prepared several experimental weight layouts that its selected dispatch did not consume. Candidate 037 created only the representations needed by the selected paths and fallbacks. This reduced static memory and setup work without changing the projection arithmetic. Its official check passed at about 1.3022. That is close to the prior check and does not establish a new substantial speedup. It is useful evidence for a cleaner preparation policy, not another scored milestone.
Candidate 038 doubles selected warps
The next launch experiment moved the selected single-token QKV and pooler vector kernels from sixteen warps to 32. If more lanes were always better, this would have been an obvious upgrade. It passed correctness but checked at about 1.2699, a regression from the useful configuration. More threads can change residency, instruction distribution, and memory behavior in unhelpful ways. I therefore retained the earlier officially scored source rather than promote a larger launch simply because it sounded more parallel.
The broad C15 search hit its time limit
The broad cuBLAS Lt extension explored additional tile, stage, swizzle, and cluster configurations beyond the earlier search. The recovered log showed a very large candidate space and a time limit while screening the first target. That is an incomplete search outcome, not a completed new winning method. It illustrates another tradeoff: expanding a hypothesis space can reduce the chance of thoroughly validating useful finalists within the available time. A narrower, informed search can be more productive than a huge undirected one.
Prepared source is not validated work
The workspace also contains later vector, packed split-K, and cluster-router experiment sources. At this written companion's evidence cutoff, those prepared designs were not established as completed correctness-and-performance wins. They remain useful future proposals. I explicitly label them that way in the experiment atlas. This is especially important in an agent workflow, where writing a source file or scheduling a job can look like progress in a transcript even when no successful result has been recovered.
Keep the best verified artifact
A later file is not automatically a better file. The exact 036 source remains the officially scored 1.3012 winner in the preserved record. A cleanup can be attractive, and a proposed kernel can be promising, but promotion should require the appropriate fresh evidence. This protects me from losing a reproducible result while exploration continues. The source archive also lets me compare a future candidate against the actual incumbent rather than an accidentally modified approximation of it.
The investigation remains open
The epilogue does not erase the crossing of 1.30. It shows what happened when the goal moved to 1.32: a near-identical cleanup check, a launch regression, a broad search that timed out, and several unvalidated proposals. That is the honest state from which another engineering round should begin. The next chapter turns the remaining numerical gap into a concrete savings budget, so future work can target plausible improvements instead of repeat the demand for a guaranteed number.
V · What the result teaches / 52
The remaining road to 1.32×#
At this point in the story, 1.32× still needed more work. I translated that gap into time savings; the later result is in note 63.
Calculate the relative gap
The official point estimate is about 1.3012. To reach 1.32 against the same baseline, a new candidate would need roughly 1.32 divided by 1.3012, or 1.01445× the incumbent's speed. Equivalently, its time would need to fall by about 1.424 percent. This arithmetic describes the point-estimate gap. It does not guarantee that a local change of that size will reproduce as an official target-crossing result.
Allocate savings across loads
The score geometrically averages six load ratios. A savings confined to one load must be large enough there to move the six-load average. For small changes, the logarithm of the overall speedup is approximately the average of the load-level fractional improvements. That gives a useful planning approximation, but the final calculation should use actual times. I can ask whether a plausible microsecond saving affects one load, several loads, or all of them, and compare that contribution with the remaining target gap.
Separate possible room from attainable room
A nominal lower bound can make a remaining gap look easy. A practical implementation may already be close to its attainable streaming rate, or its remaining overhead may be difficult to remove without introducing another cost. I should therefore compare each target with both the nominal model and practical measurements. A proposed savings larger than the remaining gap is useful only if the mechanism can plausibly realize it while preserving correctness, neighboring-shape behavior, and the complete call path.
Rank the next hypotheses
A useful next-round ranking would consider absolute time, affected loads, implementation risk, and available evidence. Candidates could include a more focused library configuration search, a genuinely cheaper router reduction, or a better small-tile weight-streaming design. These are proposals, not promised wins. A failed earlier branch deserves another test only if the new version removes a specific measured or strongly supported cost. Otherwise the project risks spending more time on an idea whose best evidence is still that it lost.
What would establish completion?
For the stated target, completion requires a valid projection source that passes the official evaluation and independently scores at or above 1.32, with the corresponding entry confirmed on the board. A local 1.32 measurement, a confidence interval endpoint, a fast individual shape, or a score from another problem does not substitute. Repeated or review-time evaluation is also relevant because final rankings remain provisional. This is a concrete completion condition rather than a vague feeling that the implementation is probably fast enough.
Use uncertainty to design the next test
Because the remaining gap is close to normal measurement variation, a future change should ideally create margin through several complementary gains or a clearly strong important region. Independent local retests and official checks can then test whether that margin survives. I cannot honestly guarantee the outcome before those experiments. What I can do is make the next hypothesis specific, preserve the incumbent, control the comparison, and stop unpromising searches before they consume resources without adding evidence.
V · What the result teaches / 53
From kernel wins to serving wins#
A kernel benchmark is only one part of serving a model. To connect them, I need to look at both throughput and how long a person waits for tokens.
A request follows a larger critical path
A user's request includes tokenization and scheduling, model computation, cache management, communication, sampling, and repeated decode steps. Multiple requests may overlap or compete for resources. Improving one projection kernel changes only part of that critical path. The next bottleneck may become attention, expert work, collective communication, or scheduler delay. This is why a kernel score has a precise scope and why the serving stage measures the whole system separately.
Throughput and interactivity are different
Throughput asks how many tokens the system produces over time, often normalized per GPU. Interactivity asks how quickly each user receives tokens. Batching can improve total throughput while increasing how long one request waits. A configuration that maximizes aggregate tokens per second may therefore make a lightly loaded user experience worse. The serving score examines behavior across concurrency levels rather than reward one peak-throughput point. A useful optimization must be evaluated along that performance curve.
Time to first token matters
A user also cares how long it takes before generation begins. The serving rules impose a time-to-first-token constraint relative to stock SGLang at each load. A system cannot simply delay requests excessively to create favorable batches and claim the resulting throughput as an unconstrained win. This connects kernel engineering back to user-visible behavior: a faster matrix kernel is useful partly because it can improve throughput without needing the same latency tradeoff as more aggressive batching.
Communication and eight-device execution
The serving stage runs the model on a full eight-GPU node. The communication simplified away in isolated kernel tasks is now part of the system. Collective synchronization, expert traffic, scheduling, and work imbalance can affect completion time. A local kernel may improve its own computation while the step remains limited by a peer or a transfer. End-to-end profiling is therefore necessary before predicting serving gains from the collection of component results.
Drafting and hidden workloads
The serving workload uses multi-turn agentic coding conversations at several concurrency levels. The rules also constrain the drafter and require the model's intended computation and outputs to remain valid. This is not permission to change the model into an easier system or skip requested work. Some serving strategies may target scheduling, overlap, or implementation efficiency, but they need their own validation under the hidden workload. The projection film provides a foundation for that work rather than evidence that it is already completed.
The correct bridge from this project
The practical bridge is to take the verified kernel source, integrate it where its shapes and contracts match, measure the full system, and inspect both throughput and user latency. The component evidence tells me where to look and what numerical behavior has been tested. It does not remove integration risks or the need for a serving run. This is the final boundary of my 1.30 accomplishment: a real projection improvement that can inform a larger system experiment.
V · What the result teaches / 54
Reproduce and audit the result#
If you want to check the result yourself, start with the exact source and saved environment rather than a filename that happens to say best.
Start from the immutable winner
Open the archived experiment 036 source and its manifest. Compare its hash with the saved winner and the current project submission if you intend to reproduce that result. Do not begin from an edited file merely because its name says submission. The archive also contains the earlier source, so later investigation can preserve a known fallback. Exact source identity is the first step in reproduction; otherwise a different implementation may be compared with an old result without anyone noticing.
Verify the execution environment
Use the specified image and a compatible H200 machine. Record the driver, visible GPU, framework and compiler versions, clocks, and the command used. Confirm the workload can execute rather than assume a running pod means a ready lab. If a tool is unavailable, such as restricted hardware counters, record that limitation. Reproduction does not require pretending every environment detail is identical. It requires enough detail to understand the comparison and identify meaningful differences.
Run correctness before timing
The local correctness runner can evaluate the winner against the supplied reference with multiple seeds. Include the difficult official cases, scored shapes, outliers, neighboring dimensions, and fresh graph replays. A failure should stop performance selection until it is understood. A passed local check still does not replace the official service's independent tests, but it is an efficient way to catch mistakes before spending an official attempt. Preserve the complete output rather than only the final word pass.
Reproduce the paired timing method
Capture the complete candidate and baseline paths, rotate weight states, feed fresh activations, flush L2, and alternate execution order. Record repetitions, overhead handling, and raw or paired timing summaries. Compare the winner with the official baseline and with a known incumbent when isolating changes. If a result differs, inspect the shape-level profile before assuming the entire reproduction failed. A small aggregate difference can come from several localized timing changes.
Ask the official evaluator the same question
With an authenticated competition account and the human-accepted rules in place, an official check evaluates the immutable candidate off the board. A scored submission establishes a leaderboard attempt. Save the returned job identifier, source identity, and full result. The project helper records these in the experiment ledger. If a submission times out or fails, retain that as an outcome rather than silently replace it with a local timing. The official result is what resolves the competition claim.
Finish the experiment lifecycle
Synchronize source and results before stopping remote compute. Verify that the resource is actually stopped rather than trust a background command that may never execute. Retained disk can still incur storage charges, while termination can destroy unsynchronized files. A reliable cost guard must use a supported mechanism and have the credentials needed to stop the intended pod. The lesson from my idle allocation is to test that lifecycle as carefully as the workload, especially when unattended work can outlive an agent turn.
V · What the result teaches / 55
The decision-making playbook#
These are the habits I would carry into another optimization round: make a specific prediction, keep the checks honest, and save enough to explain the decision later.
The path was built from changed beliefs
At the beginning, a correct custom router was slower than the baseline. The result changed the question from whether the arithmetic was valid to whether enough work reached the GPU. Split-K produced the first useful win. The uneven shape profile then changed the question again, toward dispatch. This is the central pattern of the project: measurements did not merely rank finished ideas. They changed which problem I thought needed solving next.
Representation was a recurring lever
Packed high and low router columns, transposed dense weights, tiled pooler weights, and alternative library orientations all used the same broad freedom: represent static data differently while preserving the required operation. Some representations improved memory access or exposed a better library algorithm. The compression branches showed the opposite possibility, where a smaller representation created too much decode work. The useful principle is to account for the complete representation cost, not declare rearrangement or compression inherently good.
Hardware features needed a workload match
Custom cluster QKV helped its small-token region. Deeper pipelines and a separate TMA design did not establish another useful win. Library calls remained strong at many larger shapes. Finally, a focused warp and cache-policy change helped single-token streaming, while doubling warps later regressed. These outcomes resist a simplistic ranking of technologies. The best implementation is the one whose parallelism, movement, arithmetic, and resource use match the actual shape and execution conditions.
Validation made the story credible
The local 1.3234 result was exciting, but official evaluation recorded 1.3012. Preserving both made the conclusion more useful. Fresh-input graph tests protected against stale state. Nearby shapes exposed alignment risks. Immutable sources linked the final score to actual code. These practices are not obstacles around optimization. They are how I distinguish a reusable improvement from a lucky timing, a hidden assumption, or a story attached to the wrong file.
State the result with its scope
The project officially achieved about 1.3012× SGLang on the dense projection workload. That corresponds to about twenty 3.15 percent less aggregate score-equivalent time. The later 1.32 target remained open, and the same ratio was not established for the full serving system. This precise statement is the accomplishment I can defend. A future improvement should strengthen the evidence and the implementation rather than blur the boundary of the claim.
Your reusable investigation loop
For your next kernel problem, begin with the contract and a reproducible baseline. Build a rough arithmetic and byte model. Identify the dominant measured cost. Form a specific hypothesis, implement it, and validate correctness before timing. Retime useful finalists, test boundaries, and evaluate the combined path. Preserve failures, promote exact verified sources, and finish the resource lifecycle. That loop is the deeper result of this project: a way to turn uncertainty into experiments, and experiments into an improvement another engineer can inspect.
Appendices · The complete evidence atlas / 56
Appendix A · Every experiment#
Every saved candidate belongs here, including the losing and source-only branches. I'll say what was actually measured for each one.
001 · first fused router
Experiment 1, first fused router. The first custom path combined a direct single-token vector reduction with a high-and-low router kernel. Its output grid left the long reduction inside relatively few blocks, motivating a parallelism experiment. The official check returned 0.776071× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
002 · split router
Experiment 2, split router. This design added a split dimension across K and wrote FP32 partial results. A separate reduction combined those partials, exchanging additional traffic and a launch for more independent GPU work. The official check returned 1.101364× the baseline, and the saved status records a passed evaluation. The independently scored submission returned 1.103685× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
003 · selective GEMV
Experiment 3, selective GEMV. This branch narrowed direct vector use to selected single-token work. It tested whether shape-specific GEMV choices could improve the complete candidate rather than assume every one-token matrix favored the same kernel. The official check returned 1.012148× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
004 · router dispatch
Experiment 4, router dispatch. This branch adjusted split and token-tile choices and selected vector paths by layer. It developed a policy over regimes rather than require one implementation to win across all shapes. The official check returned 1.116059× the baseline, and the saved status records a passed evaluation. The independently scored submission returned 1.114445× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
005 · attention preparation
Experiment 5, attention preparation. This attention branch fused compatible normalization, rotary-position, and cache-write preparation. It preserved the attention contract while targeting intermediate work and launch boundaries around the main attention kernel. The official check returned 1.132496× the baseline, and the saved status records a passed evaluation. The independently scored submission returned 1.132288× the baseline, and the saved status records a passed evaluation. This entry belongs to attention decode, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
006 · expert local tiles
Experiment 6, expert local tiles. This expert branch changed local tiling or alignment behavior. Its near-baseline outcome warned that reducing apparent padding or choosing smaller local groups does not automatically improve the complete expert call. The official check returned 0.994488× the baseline, and the saved status records a passed evaluation. This entry belongs to moe w4a16, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
007 · dense split-K
Experiment 7, dense split-K. This dense branch explored reduction splitting for the larger weight matrices. The same parallelism-versus-partial-traffic tradeoff from the router applies, but the dense shapes and output precision create different costs. The official check returned 1.049125× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
008 · layer integration source
Experiment 8, layer integration source. This source prepared a whole-layer integration branch. A source file is evidence that an implementation was prepared, but without a linked completed evaluation it does not establish either correctness or a speedup. No linked completed run is present in the extracted experiment ledger for this source. This entry belongs to the whole decoder layer, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
009 · packed router
Experiment 9, packed router. This candidate retained small-batch split-router work and used concatenated high-and-low output columns for a larger library product. Static packing changed the execution path while preserving the permitted router arithmetic. The official check returned 1.137166× the baseline, and the saved status records a passed evaluation. The independently scored submission returned 1.155506× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
010 · expert post-normalization fusion
Experiment 10, expert post-normalization fusion. This expert candidate fused compatible post-expert normalization and weighted combination work. The order mattered: normalization belongs to each expert output before the route contributions are combined. The official check returned 1.147244× the baseline, and the saved status records a passed evaluation. The independently scored submission returned 1.145379× the baseline, and the saved status records a passed evaluation. This entry belongs to moe w4a16, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
011 · whole-layer validated components
Experiment 11, whole-layer validated components. This candidate joined validated pieces into the complete local decoder-layer contract. Its result illustrates why standalone component ratios do not multiply into a whole-layer speedup. The official check returned 1.093329× the baseline, and the saved status records a passed evaluation. The independently scored submission returned 1.095338× the baseline, and the saved status records a passed evaluation. This entry belongs to decode layer, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
012 · attention local splits
Experiment 12, attention local splits. This attention branch explored sliding-attention split choices and related scheduling or partial-output work. It targeted a specific overhead opportunity while preserving the full required attention key set. The official check returned 1.134850× the baseline, and the saved status records a passed evaluation. This entry belongs to attention decode, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
013 · expert middle tiles
Experiment 13, expert middle tiles. This expert candidate retained the validated small-token route and selected a sixteen-token tile in a larger-token range. It separated the tile-policy hypothesis from earlier broader alignment changes. The official check returned 1.270556× the baseline, and the saved status records a passed evaluation. The independently scored submission returned 1.268370× the baseline, and the saved status records a passed evaluation. This entry belongs to moe w4a16, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
014 · optional Hopper GEMV
Experiment 14, optional Hopper GEMV. This branch invoked an installed optional Hopper matrix-vector route for selected single-token dense work. Its useful regime had to be established from the exact workload and installed implementation. The official check returned 1.148147× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
015 · transposed dense weights
Experiment 15, transposed dense weights. This branch prepared lossless dense transposes and used the changed layout to expose different library behavior. It preserved mathematical values while paying static preparation and storage costs. The official check returned 1.167969× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
016 · wide K dense tiles
Experiment 16, wide K dense tiles. This branch increased K tile width in the custom dense path. Wider tiles can change load efficiency and loop overhead, but also shared-memory demand and residency. The official check returned 1.135331× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
017 · QuACK large dense integration
Experiment 17, QuACK large dense integration. This attempted QuACK integration did not reach a valid performance result. The later repair addressed the chosen low-level split-K interface requiring batched rank-three operands. The recorded evaluation failed. There is no valid speedup to report for that failed execution. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
018 · QuACK skinny swapped integration
Experiment 18, QuACK skinny swapped integration. This alternate QuACK orientation also encountered integration problems before a usable timing. It must be distinguished from a correct kernel that ran and lost. The recorded evaluation failed. There is no valid speedup to report for that failed execution. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
019 · repaired QuACK large batched
Experiment 19, repaired QuACK large batched. This repaired branch added the required batch dimension with views. Passing the interface and correctness gates allowed a real timing comparison, which was not a compelling complete-path improvement. The official check returned 1.000884× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
020 · repaired QuACK skinny batched
Experiment 20, repaired QuACK skinny batched. This repaired skinny route also used batched views rather than copies. The resulting valid timing was informative, while still below the strongest combined candidate paths. The official check returned 1.122068× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
021 · measured dense bundle
Experiment 21, measured dense bundle. This bundle composed selected regions from earlier measured methods. Combining correct functions created a new source that still required a fresh complete correctness and timing evaluation. The official check returned 1.162327× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
022 · cuBLASLt plan search
Experiment 22, cuBLASLt plan search. This branch searched reusable library plans, layouts, and valid algorithm choices. It kept compute and reduction precision explicit rather than allow an output dtype to hide a cheaper intermediate reduction. The official check returned 1.159035× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
023 · vector plan search
Experiment 23, vector plan search. This branch swept direct vector reductions across selected small-token shapes. Output rows per block and warp count changed memory streams, register distribution, and reduction behavior. The official check returned 1.181509× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
024 · router plan search
Experiment 24, router plan search. This branch explored router launch and tile policies. It tested the interaction among grid parallelism, reduction work, and repeated input reads rather than assume a single larger tile would win. The official check returned 1.142180× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
025 · router fused reduction
Experiment 25, router fused reduction. This router branch targeted the split-combination path. Removing a dedicated reduction launch could introduce partial traffic, counters, and last-arriving-block costs that still needed measurement. The official check returned 1.142189× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
026 · expanded measured bundle
Experiment 26, expanded measured bundle. This broader bundle combined complementary selected methods and became a new independently scored projection milestone. The check and scored results remained separately recorded. The official check returned 1.209900× the baseline, and the saved status records a passed evaluation. The independently scored submission returned 1.199334× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
027 · paired router search
Experiment 27, paired router search. This branch explored paired high-and-low router layouts and reduction paths. A rearranged operand can improve access or combine operations, but its complete resource cost determines whether it helps. The official check returned 1.153926× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
028 · expanded library search
Experiment 28, expanded library search. This branch broadened library algorithm configurations with validated split, tile, and stage choices. Additional search coverage produced evidence without making an algorithm index universally suitable. The official check returned 1.178338× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
029 · C1 measured best-of
Experiment 29, C1 measured best-of. This candidate assembled a measured per-layer and token-range policy. It made later work modular: a new method could earn a region without replacing every validated path. The official check returned 1.256396× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
030 · C1 atomic router
Experiment 30, C1 atomic router. This candidate used paired router products with FP32 atomic accumulation into a fresh zeroed output. It avoided a dedicated partial-sum reduction while retaining initialization in the complete timed path. This ledger entry has no completed score recorded here; its status must not be silently converted into a performance claim. The independently scored submission returned 1.278497× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
031 · C1 tiny unpooler GEMM
Experiment 31, C1 tiny unpooler GEMM. This branch explored the installed tiny GEMM route for the small local unpooler slice. A useful component choice need not make its complete candidate check the next aggregate record. The official check returned 1.261956× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
032 · C1 cluster QKV
Experiment 32, C1 cluster QKV. This branch used a custom Hopper block-cluster QKV path. It staged tiles asynchronously, used matrix instructions, and combined split contributions through distributed shared memory. The official check returned 1.271215× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
033 · C1 deep cluster QKV
Experiment 33, C1 deep cluster QKV. This became the incumbent entering the C2 round. Its selected custom QKV region coexisted with vector, Triton, and library methods for other projection families and token ranges. The official check returned 1.277069× the baseline, and the saved status records a passed evaluation. The independently scored submission returned 1.288792× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
034 · C2 packed pooler and library choices
Experiment 34, C2 packed pooler and library choices. This combined candidate included direct packed pooler work and selected library configurations. A local component improvement did not establish an official aggregate win over the incumbent. The official check returned 1.285194× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
035 · C2 expanded library layouts
Experiment 35, C2 expanded library layouts. This candidate broadened operand and output orientation choices and protected neighboring shapes with fallbacks. Its layout-only official result still stayed near the earlier incumbent. The official check returned 1.286016× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
036 · C2 streaming vector winner
Experiment 36, C2 streaming vector winner. This candidate added the selected sixteen-warp streaming vector paths for single-token QKV and pooler to the combined layout policy. It became the officially scored 1.3012 source. The official check returned 1.302007× the baseline, and the saved status records a passed evaluation. The independently scored submission returned 1.301203× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
037 · C2 lean preparation
Experiment 37, C2 lean preparation. This candidate stopped preparing unused static layouts while retaining the selected arithmetic paths and needed fallbacks. Its near-identical official check did not establish a new scored milestone. The official check returned 1.302160× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
038 · C2 32-warp vector
Experiment 38, C2 32-warp vector. This candidate increased the selected single-token vector launch to 32 warps. It passed correctness but regressed in the complete official check, so the earlier verified winner was retained. The official check returned 1.269896× the baseline, and the saved status records a passed evaluation. This entry belongs to bf16 proj, so its ratio must be interpreted within that problem rather than transferred to a different board. The source snapshot and available job identifiers are listed in the accompanying experiment atlas. Read a check as off-board evidence and a scored run as a leaderboard attempt. A result above one means faster aggregate execution; below one means slower execution. The next decision should use the affected shape profile and numerical validity, not merely the order of this experiment number.
Appendices · Official per-shape measurements / 57
Appendix B · All thirty shapes#
This is the detailed tour of all thirty scored shapes. The important comparison is the time each contributes, as well as its individual ratio.
decode 1 · qkv_gate
This official case is decode 1, layer qkv_gate. The input has 1 token rows and 8192 input features, and the output has 2304 features. The required original weight payload for this local projection is approximately 37.749 decimal megabytes. The mathematical product contains about 37.749 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 14.080 microseconds and the paired-ratio-derived candidate time is 10.077 microseconds. The saved speedup is 1.3972, which reduces the corresponding time by about 28.43 percent. The winner selects the sixteen-warp streaming vector path. This case accounts for about 25.49 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
decode 1 · o
This official case is decode 1, layer o. The input has 1 token rows and 1024 input features, and the output has 8192 features. The required original weight payload for this local projection is approximately 16.777 decimal megabytes. The mathematical product contains about 16.777 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 6.784 microseconds and the paired-ratio-derived candidate time is 5.490 microseconds. The saved speedup is 1.2357, which reduces the corresponding time by about 19.07 percent. The winner selects a direct vector reduction. This case accounts for about 13.89 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
decode 1 · pooler
This official case is decode 1, layer pooler. The input has 1 token rows and 8192 input features, and the output has 4096 features. The required original weight payload for this local projection is approximately 67.109 decimal megabytes. The mathematical product contains about 67.109 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 21.456 microseconds and the paired-ratio-derived candidate time is 16.532 microseconds. The saved speedup is 1.2979, which reduces the corresponding time by about 22.95 percent. The winner selects the sixteen-warp streaming vector path. This case accounts for about 41.82 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
decode 1 · unpooler
This official case is decode 1, layer unpooler. The input has 1 token rows and 4096 input features, and the output has 1024 features. The required original weight payload for this local projection is approximately 8.389 decimal megabytes. The mathematical product contains about 8.389 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 6.912 microseconds and the paired-ratio-derived candidate time is 3.666 microseconds. The saved speedup is 1.8856, which reduces the corresponding time by about 46.97 percent. The winner selects a direct vector reduction. This case accounts for about 9.27 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
decode 1 · router
This official case is decode 1, layer router. The input has 1 token rows and 8192 input features, and the output has 256 features. The required original weight payload for this local projection is approximately 8.389 decimal megabytes. The mathematical product contains about 4.194 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 10.528 microseconds and the paired-ratio-derived candidate time is 3.770 microseconds. The saved speedup is 2.7924, which reduces the corresponding time by about 64.19 percent. The winner selects a direct original-FP32 vector reduction. This case accounts for about 9.54 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
decode 16 · qkv_gate
This official case is decode 16, layer qkv_gate. The input has 16 token rows and 8192 input features, and the output has 2304 features. The required original weight payload for this local projection is approximately 37.749 decimal megabytes. The mathematical product contains about 603.980 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 14.128 microseconds and the paired-ratio-derived candidate time is 12.971 microseconds. The saved speedup is 1.0892, which reduces the corresponding time by about 8.19 percent. The winner selects the custom cluster split-K path. This case accounts for about 21.27 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
decode 16 · o
This official case is decode 16, layer o. The input has 16 token rows and 1024 input features, and the output has 8192 features. The required original weight payload for this local projection is approximately 16.777 decimal megabytes. The mathematical product contains about 268.435 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 6.656 microseconds and the paired-ratio-derived candidate time is 6.700 microseconds. The saved speedup is 0.9934, which increases the corresponding time by about 0.66 percent. The winner selects the retained library dispatch. This case accounts for about 10.99 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
decode 16 · pooler
This official case is decode 16, layer pooler. The input has 16 token rows and 8192 input features, and the output has 4096 features. The required original weight payload for this local projection is approximately 67.109 decimal megabytes. The mathematical product contains about 1073.742 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 21.104 microseconds and the paired-ratio-derived candidate time is 18.073 microseconds. The saved speedup is 1.1677, which reduces the corresponding time by about 14.36 percent. The winner selects the direct packed-weight Triton path. This case accounts for about 29.64 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
decode 16 · unpooler
This official case is decode 16, layer unpooler. The input has 16 token rows and 4096 input features, and the output has 8192 features. The required original weight payload for this local projection is approximately 67.109 decimal megabytes. The mathematical product contains about 1073.742 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 18.624 microseconds and the paired-ratio-derived candidate time is 18.126 microseconds. The saved speedup is 1.0275, which reduces the corresponding time by about 2.67 percent. The winner selects the transposed library product. This case accounts for about 29.73 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
decode 16 · router
This official case is decode 16, layer router. The input has 16 token rows and 8192 input features, and the output has 256 features. The required original weight payload for this local projection is approximately 8.389 decimal megabytes. The mathematical product contains about 67.109 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 14.720 microseconds and the paired-ratio-derived candidate time is 5.102 microseconds. The saved speedup is 2.8853, which reduces the corresponding time by about 65.34 percent. The winner selects paired high/low BF16 products with FP32 atomic accumulation into freshly zeroed output. This case accounts for about 8.37 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
decode 32 · qkv_gate
This official case is decode 32, layer qkv_gate. The input has 32 token rows and 8192 input features, and the output has 2304 features. The required original weight payload for this local projection is approximately 37.749 decimal megabytes. The mathematical product contains about 1207.960 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 14.144 microseconds and the paired-ratio-derived candidate time is 13.028 microseconds. The saved speedup is 1.0857, which reduces the corresponding time by about 7.89 percent. The winner selects the selected cuBLASLt orientation. This case accounts for about 20.96 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
decode 32 · o
This official case is decode 32, layer o. The input has 32 token rows and 1024 input features, and the output has 8192 features. The required original weight payload for this local projection is approximately 16.777 decimal megabytes. The mathematical product contains about 536.871 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 6.784 microseconds and the paired-ratio-derived candidate time is 6.665 microseconds. The saved speedup is 1.0178, which reduces the corresponding time by about 1.75 percent. The winner selects the retained library dispatch. This case accounts for about 10.73 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
decode 32 · pooler
This official case is decode 32, layer pooler. The input has 32 token rows and 8192 input features, and the output has 4096 features. The required original weight payload for this local projection is approximately 67.109 decimal megabytes. The mathematical product contains about 2147.484 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 21.952 microseconds and the paired-ratio-derived candidate time is 18.839 microseconds. The saved speedup is 1.1653, which reduces the corresponding time by about 14.18 percent. The winner selects the direct packed-weight Triton path. This case accounts for about 30.31 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
decode 32 · unpooler
This official case is decode 32, layer unpooler. The input has 32 token rows and 4096 input features, and the output has 8192 features. The required original weight payload for this local projection is approximately 67.109 decimal megabytes. The mathematical product contains about 2147.484 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 18.560 microseconds and the paired-ratio-derived candidate time is 17.887 microseconds. The saved speedup is 1.0376, which reduces the corresponding time by about 3.63 percent. The winner selects the transposed library product. This case accounts for about 28.78 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
decode 32 · router
This official case is decode 32, layer router. The input has 32 token rows and 8192 input features, and the output has 256 features. The required original weight payload for this local projection is approximately 8.389 decimal megabytes. The mathematical product contains about 134.218 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 15.280 microseconds and the paired-ratio-derived candidate time is 5.726 microseconds. The saved speedup is 2.6686, which reduces the corresponding time by about 62.53 percent. The winner selects paired high/low BF16 products with FP32 atomic accumulation into freshly zeroed output. This case accounts for about 9.21 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
verify 1 · qkv_gate
This official case is verify 1, layer qkv_gate. The input has 8 token rows and 8192 input features, and the output has 2304 features. The required original weight payload for this local projection is approximately 37.749 decimal megabytes. The mathematical product contains about 301.990 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 13.984 microseconds and the paired-ratio-derived candidate time is 12.594 microseconds. The saved speedup is 1.1103, which reduces the corresponding time by about 9.94 percent. The winner selects the custom cluster split-K path. This case accounts for about 26.79 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
verify 1 · o
This official case is verify 1, layer o. The input has 8 token rows and 1024 input features, and the output has 8192 features. The required original weight payload for this local projection is approximately 16.777 decimal megabytes. The mathematical product contains about 134.218 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 6.464 microseconds and the paired-ratio-derived candidate time is 6.544 microseconds. The saved speedup is 0.9878, which increases the corresponding time by about 1.23 percent. The winner selects the retained library dispatch. This case accounts for about 13.92 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
verify 1 · pooler
This official case is verify 1, layer pooler. The input has 8 token rows and 8192 input features, and the output has 4096 features. The required original weight payload for this local projection is approximately 67.109 decimal megabytes. The mathematical product contains about 536.871 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 21.248 microseconds and the paired-ratio-derived candidate time is 18.066 microseconds. The saved speedup is 1.1761, which reduces the corresponding time by about 14.97 percent. The winner selects the direct packed-weight Triton path. This case accounts for about 38.43 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
verify 1 · unpooler
This official case is verify 1, layer unpooler. The input has 8 token rows and 4096 input features, and the output has 1024 features. The required original weight payload for this local projection is approximately 8.389 decimal megabytes. The mathematical product contains about 67.109 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 6.848 microseconds and the paired-ratio-derived candidate time is 4.766 microseconds. The saved speedup is 1.4367, which reduces the corresponding time by about 30.40 percent. The winner selects the small-slice FlashInfer tinygemm path. This case accounts for about 10.14 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
verify 1 · router
This official case is verify 1, layer router. The input has 8 token rows and 8192 input features, and the output has 256 features. The required original weight payload for this local projection is approximately 8.389 decimal megabytes. The mathematical product contains about 33.554 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 25.984 microseconds and the paired-ratio-derived candidate time is 5.035 microseconds. The saved speedup is 5.1604, which reduces the corresponding time by about 80.62 percent. The winner selects paired high/low BF16 products with FP32 atomic accumulation into freshly zeroed output. This case accounts for about 10.71 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
verify 16 · qkv_gate
This official case is verify 16, layer qkv_gate. The input has 128 token rows and 8192 input features, and the output has 2304 features. The required original weight payload for this local projection is approximately 37.749 decimal megabytes. The mathematical product contains about 4831.838 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 17.232 microseconds and the paired-ratio-derived candidate time is 17.089 microseconds. The saved speedup is 1.0084, which reduces the corresponding time by about 0.83 percent. The winner selects the retained library dispatch. This case accounts for about 23.88 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
verify 16 · o
This official case is verify 16, layer o. The input has 128 token rows and 1024 input features, and the output has 8192 features. The required original weight payload for this local projection is approximately 16.777 decimal megabytes. The mathematical product contains about 2147.484 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 7.424 microseconds and the paired-ratio-derived candidate time is 7.651 microseconds. The saved speedup is 0.9703, which increases the corresponding time by about 3.06 percent. The winner selects the retained library dispatch. This case accounts for about 10.69 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
verify 16 · pooler
This official case is verify 16, layer pooler. The input has 128 token rows and 8192 input features, and the output has 4096 features. The required original weight payload for this local projection is approximately 67.109 decimal megabytes. The mathematical product contains about 8589.935 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 24.928 microseconds and the paired-ratio-derived candidate time is 21.066 microseconds. The saved speedup is 1.1833, which reduces the corresponding time by about 15.49 percent. The winner selects the selected cuBLASLt layout and algorithm. This case accounts for about 29.44 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
verify 16 · unpooler
This official case is verify 16, layer unpooler. The input has 128 token rows and 4096 input features, and the output has 8192 features. The required original weight payload for this local projection is approximately 67.109 decimal megabytes. The mathematical product contains about 8589.935 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 19.584 microseconds and the paired-ratio-derived candidate time is 18.928 microseconds. The saved speedup is 1.0347, which reduces the corresponding time by about 3.35 percent. The winner selects the transposed library product. This case accounts for about 26.45 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
verify 16 · router
This official case is verify 16, layer router. The input has 128 token rows and 8192 input features, and the output has 256 features. The required original weight payload for this local projection is approximately 8.389 decimal megabytes. The mathematical product contains about 536.871 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 16.160 microseconds and the paired-ratio-derived candidate time is 6.829 microseconds. The saved speedup is 2.3665, which reduces the corresponding time by about 57.74 percent. The winner selects paired high/low BF16 products with FP32 atomic accumulation into freshly zeroed output. This case accounts for about 9.54 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
verify 32 · qkv_gate
This official case is verify 32, layer qkv_gate. The input has 256 token rows and 8192 input features, and the output has 2304 features. The required original weight payload for this local projection is approximately 37.749 decimal megabytes. The mathematical product contains about 9663.676 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 20.000 microseconds and the paired-ratio-derived candidate time is 19.936 microseconds. The saved speedup is 1.0032, which reduces the corresponding time by about 0.32 percent. The winner selects the retained library dispatch. This case accounts for about 21.88 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
verify 32 · o
This official case is verify 32, layer o. The input has 256 token rows and 1024 input features, and the output has 8192 features. The required original weight payload for this local projection is approximately 16.777 decimal megabytes. The mathematical product contains about 4294.967 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 9.152 microseconds and the paired-ratio-derived candidate time is 9.488 microseconds. The saved speedup is 0.9646, which increases the corresponding time by about 3.67 percent. The winner selects the retained library dispatch. This case accounts for about 10.41 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
verify 32 · pooler
This official case is verify 32, layer pooler. The input has 256 token rows and 8192 input features, and the output has 4096 features. The required original weight payload for this local projection is approximately 67.109 decimal megabytes. The mathematical product contains about 17179.869 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 30.896 microseconds and the paired-ratio-derived candidate time is 28.949 microseconds. The saved speedup is 1.0673, which reduces the corresponding time by about 6.30 percent. The winner selects the selected cuBLASLt layout and algorithm. This case accounts for about 31.77 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
verify 32 · unpooler
This official case is verify 32, layer unpooler. The input has 256 token rows and 4096 input features, and the output has 8192 features. The required original weight payload for this local projection is approximately 67.109 decimal megabytes. The mathematical product contains about 17179.869 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 23.984 microseconds and the paired-ratio-derived candidate time is 23.861 microseconds. The saved speedup is 1.0052, which reduces the corresponding time by about 0.51 percent. The winner selects the selected swapped-output cuBLASLt path. This case accounts for about 26.19 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
verify 32 · router
This official case is verify 32, layer router. The input has 256 token rows and 8192 input features, and the output has 256 features. The required original weight payload for this local projection is approximately 8.389 decimal megabytes. The mathematical product contains about 1073.742 million floating-point operations under the conventional two-M-N-K count; an implementation can perform extra work beyond that count. The recorded baseline time is 17.568 microseconds and the paired-ratio-derived candidate time is 8.884 microseconds. The saved speedup is 1.9774, which reduces the corresponding time by about 49.43 percent. The winner selects paired high/low BF16 products with FP32 atomic accumulation into freshly zeroed output. This case accounts for about 9.75 percent of the candidate time within its five-shape load. That share helps interpret its remaining aggregate leverage. It is a measurement from one official run, not a universal hardware floor or a promised result on another machine.
Appendices · Worked equations / 58
Appendix C · Mathematical derivations#
For the math-curious version, here are the derivations behind the shortcuts used in the main story. Take one at a time; they don't need to be memorized.
Counting GEMM work
For each of M times N output values, a dot product has K multiplications and roughly K additions. The conventional count is therefore two M N K floating-point operations. It is a count of useful mathematical work, not necessarily executed instructions. Tensor tiles may include padded elements, and a router high-and-low implementation performs two products. For a pooler at M sixteen, N 4,096, and K 8,192, the useful count is about 1.074 billion operations. This sounds large, but compare it with nearly sixty 7.1 megabytes of weights. The count alone cannot tell me elapsed time. To make a performance prediction, I need both arithmetic and movement bounds, then the real implementation costs.
Weight traffic and intensity
A BF16 value occupies two bytes. For an N by K weight matrix, the original payload is two N K bytes. Divide the approximate two M N K operation count by that payload and M remains. This weight-only intensity assumes each weight is fetched once and ignores activations, output, metadata, and scratch. A method that rereads weight tiles from external memory has a worse effective intensity. A method that reuses a tile across token rows may approach the assumption more closely. I use the expression to understand why token count changes the regime. I do not use it to claim actual traffic was measured or that every implementation reaches a particular roofline point.
Pooler at sixteen tokens
For the sixteen-token pooler, the nominal weight payload is approximately sixty 7.109 decimal megabytes. At 4.8 terabytes per second, moving that payload alone takes about thirteen point 98 microseconds. The useful arithmetic count divided by 989 tera operations per second gives only about 1.09 microseconds. Under these optimistic assumptions, movement is the larger bound. Real activation and output traffic, imperfect accesses, scheduling, and synchronization add cost. This example explains why a small arithmetic optimization might have little effect and why a more efficient weight stream was attractive. It does not promise that a new kernel can finish at thirteen point 98 microseconds.
Pooler at 256 tokens
Increase the pooler's token count to 256. The weight payload stays the same, but useful arithmetic grows sixteenfold from the sixteen-token example. The nominal arithmetic bound becomes about seventeen point 37 microseconds, larger than the weight-only bandwidth bound. That moves the simplified case toward the arithmetic ceiling. Additional activation and output traffic still exists, and the actual schedule may reread values. The official selected candidate took about twenty 8.95 microseconds for this shape in the saved run. The gap from an ideal bound suggests room in principle, but it does not identify an implementation capable of closing that room.
Router partial-sum storage
With 32 splits, sixteen token rows, and 256 router outputs, a FP32 partial tensor contains 524,288 bytes. Writing and reading all partials transfers roughly twice that payload before counting transaction inefficiency or cache behavior. The final output itself is only 16,384 bytes. This contrast explains why the reduction organization matters. A separate kernel, atomic route, or last-arriving-block design exchanges different forms of traffic and synchronization. None can be evaluated by the partial byte count alone, because a short call also pays latency and launch-related costs.
Geometric averaging
The six load ratios combine multiplicatively. Taking their logarithms turns the product into a sum, so the log of the overall score is the average log ratio. This is useful for small-change planning: a small fractional improvement in one load contributes roughly one sixth of that change to the overall log score if the other five loads stay unchanged. The exact calculation should use the product and sixth root, not this approximation. Inside each load, first sum weighted shape times. Reversing the order and averaging individual shape percentages produces a different statistic and can rank candidates incorrectly.
Amdahl with a concrete time share
Start with 100 units of baseline time. Twenty belong to the component I optimize, and eighty belong elsewhere. If that component becomes twice as fast, its time falls to ten. Total time becomes ninety, for a speedup of 1.111. If the component became infinitely fast, the other eighty would remain, limiting total speedup to 1.25. This is why a large ratio on a small router case cannot by itself produce the same ratio for a whole layer. To prioritize work, estimate attainable absolute savings on the actual critical path.
The remaining 1.32× gap
Divide the target score by the incumbent score to find the required relative speed improvement: roughly 1.01445. Divide in the opposite order to get the required relative time fraction: about 0.98576. The time reduction is therefore roughly 1.424 percent. These percentages differ because speed and time are reciprocals. The arithmetic assumes the same baseline and workload comparison. It is a planning target, not evidence that a noisy local improvement of exactly that magnitude will reproduce in an independent official run.
If only one load improves
Suppose five load ratios remain unchanged and only one load becomes faster. Because the score uses a sixth root, that load needs a larger relative gain than the overall target. Raising the required overall relative factor to the sixth power gives roughly a nine-percent speed increase in that one load, corresponding to a somewhat smaller percentage time reduction. This is a useful prioritization check. A tiny improvement in one isolated shape may have too little aggregate leverage, especially if the shape is only a fraction of that load. Several complementary improvements can distribute the burden more realistically.
Floating-point cancellation
In real arithmetic, both expressions equal one. In FP32, the spacing near 100,000,000 is larger than one. Adding one can round back to 100,000,000, so subtracting the original large value yields zero. Grouping the large cancellation first can preserve the final one. This example illustrates why changing reduction order can change results without changing the algebra. It does not authorize unlimited error. The task's actual reference checks, row constraints, and precision rules determine whether a kernel's floating-point behavior is acceptable.
High and low router components
The high part captures the coarse BF16 rounding of a FP32 weight. The residual subtraction in FP32 isolates information lost in that rounding. Rounding the residual into another BF16 value captures much of that detail on a smaller scale. Products with both parts can therefore approximate the original product much more accurately than a high-only BF16 weight. But cancellation, subnormal behavior, and output aggregation complicate any global error guarantee. I use the explicitly permitted scheme and test it against the supplied reference rather than describe the pair as universally exact.
Bandwidth proxies are not counter measurements
Dividing a matrix's original weight bytes by its candidate time gives a useful streaming proxy. It is not the same as measuring the actual external-memory bus. The kernel may reuse cache lines, reread activations, write scratch, or execute multiple products. A short-call timing also includes execution costs unrelated to byte delivery. Without hardware counter access, I should not present that simple quotient as a precise measurement of achieved H BM bandwidth. It is a model-derived indicator that can guide comparisons when its assumptions are explicit.
RMS normalization
Root-mean-square normalization computes the mean of squared features within a row, adds the specified epsilon, and rescales the row by the reciprocal square root, with the model's learned scaling where required. Unlike subtracting a mean, it does not center the row first. The reduction creates a dependency across the feature dimension. Fusing it with a following elementwise scale can save an intermediate, but moving it across a matrix product or across the sum of expert outputs generally changes the computation. My expert post-normalization work preserved the required per-expert placement. Use the exact task epsilon and scaling fields rather than invent a convenient constant.
SwiGLU and the two expert products
The first expert product produces gate and up vectors. The SiLU nonlinearity applied to the gate is gate times sigmoid of gate. Multiplying that result elementwise by the up vector gives the hidden expert activation consumed by the second matrix product. This is not equivalent to applying the nonlinearity after the second product. A fused epilogue may avoid materializing some intermediate values if it preserves this dependency and numerical contract. In the supplied expert task, normalization and route weighting follow their specified order after the expert output. Data movement can change; the required nonlinear operation cannot simply disappear.
Stable softmax and weighted values
For attention scores, a stable softmax subtracts the maximum before exponentiation. Subtracting the same maximum leaves normalized probabilities unchanged in exact arithmetic and reduces overflow risk. The denominator sums over every eligible key. Attention then forms a weighted sum of corresponding values. Split-attention implementations must combine partial maxima, normalization factors, and weighted sums consistently rather than average independently normalized fragments. The rules require the specified full key set and weighted sum, so skipping low-weight keys is not an allowed shortcut. Numerical stability and parallel reduction organization are part of implementing the same attention calculation.
Rotary position as pair rotations
Rotary position encoding applies position-dependent rotations to pairs of query and key features. For a pair u and v, a rotation uses u cosine theta minus v sine theta and u sine theta plus v cosine theta, with the model's specified frequencies and positions. The supplied sliding layers use their stated rotary configuration, while the full-attention path has its own specified behavior. A preparation fusion must use the right token position and feature pairing before writing or consuming keys. Faster arithmetic with a wrong rotation or cache location is not the same model computation.
Causal verification and the paged cache
For an eight-token verification block, the first new query may use only the appropriate history and its allowed prefix of the block. Later queries can attend to more of the block, but not its future. A page table translates logical sequence positions to physical cache locations. The task includes different page sizes in testing, so hard-coding the scored page size would be unsafe. The cache also has specified FP eight scales. Correctness therefore combines numerical conversion, logical masking, positions, and physical addressing. Fusing the writes is useful only if all those meanings survive.
Grouped-query heads and local model dimensions
The attention task specifies sixteen query heads and two key/value heads per GPU under the eight-way partition, with head dimension 64. Several query heads share a key/value head, which creates an opportunity for data reuse. Sliding layers use a 2,048-token window; full layers use the specified entire context, around 80,000 tokens in scored cases. These details affect memory volume and parallelism. They explain why an attention kernel tuned for a different head ratio, context length, or page layout might not be a useful replacement here.
Appendices · Exact code and its role / 59
Appendix D · The source atlas#
The source atlas is a reading guide to the files: which part prepares data, which part chooses a route, and where the arithmetic actually happens.
_c10_vector
This source window is c10 vector. The selected single-token routine distributes weight-row work across lanes, converts loaded operands to FP32, multiplies, and reduces across K. The cache-policy branch distinguishes the default eviction policy from the explicit selected policy. The output is stored in the required layer dtype. Follow the row and column masks: they connect a padded compile-time block to the actual logical tensor. Changing the number of warps affects the generated distribution and reduction without changing this mathematical source. This is why a small launch parameter change can matter even though the expression still looks like one dot product. Pause the video to compare the address expressions and parameter names with the full source. The displayed window is an exact excerpt, not pseudocode; the commentary explains its role within the complete method.
m_c10
This source window is m c10. This wrapper allocates a new output and launches the single-token routine with the actual output width and input-feature count. The K block is rounded to a power of two, and masking keeps the computation within the logical range. The selected plan supplies output rows per block, warps, and cache policy. The function does not synchronize to the CPU or inspect evaluated values for dispatch. Reading wrappers matters because allocation, zeroing, or extra operations around a fast kernel can change the complete captured timing. Here the wrapper's job is intentionally narrow. Pause the video to compare the address expressions and parameter names with the full source. The displayed window is an exact excerpt, not pseudocode; the commentary explains its role within the complete method.
_c2_dense_packed
This source window is c2 dense packed. The grid selects token and output-feature tiles. Weight addresses identify one contiguous packed K-by-output tile. The loop stages K blocks and updates a FP32 accumulator with a matrix dot product. The final store converts to BF16 and masks token or output boundaries. Notice what is absent: this selected packed path does not write a global split-partial tensor or launch a separate split reduction. That design can help only if its direct output grid and pipeline expose enough useful work. The local search selected the supported pooler regions. Pause the video to compare the address expressions and parameter names with the full source. The displayed window is an exact excerpt, not pseudocode; the commentary explains its role within the complete method.
m_c2_packed
This source window is m c2 packed. This wrapper retrieves the exact packed weight tensor from state, creates the required output shape, and launches the packed kernel with the selected token, output, and K tiles. The packed-state key includes layer and output-tile width, so preparation and dispatch must agree on which representations exist. A missing or mismatched representation is an integration failure, not a numerical or performance conclusion. The later lean preparation preserved only the packed pooler representation actually consumed by its plan. That cleanup illustrates why state requirements belong in the review of a dispatch policy. Pause the video to compare the address expressions and parameter names with the full source. The displayed window is an exact excerpt, not pseudocode; the commentary explains its role within the complete method.
_paired_router_atomic
This source window is paired router atomic. This router kernel loads paired high and low columns, performs BF16 dot products with FP32 accumulation, combines each corresponding pair, and atomically adds the split contribution to output. The masks protect valid token and output positions. Its K partitioning determines which contribution each block owns. The atomic store protects concurrent additions, while the wrapper must supply an initially zero output. Correctness therefore spans the kernel and its caller. The displayed excerpt is a window into the source; the full preserved implementation is linked in the evidence directory. Pause the video to compare the address expressions and parameter names with the full source. The displayed window is an exact excerpt, not pseudocode; the commentary explains its role within the complete method.
m_ratomic
This source window is m ratomic. The wrapper creates a zeroed FP32 output, launches the paired router over token tiles, output tiles, and K splits, then returns that output. Zeroing is essential for fresh invocation semantics and remains part of the captured path. The launch parameters vary across token ranges. The absence of a dedicated final reduction kernel does not mean initialization is free or absent. This wrapper is a concrete example of why I time the complete required call rather than quote the duration of the arithmetic kernel in isolation. Pause the video to compare the address expressions and parameter names with the full source. The displayed window is an exact excerpt, not pseudocode; the commentary explains its role within the complete method.
m_cluster
This source window is m cluster. The cluster wrapper selects the native extension and allocates a BF16 output. Its token count maps to the supported compiled token tile, and the plan supplies split count, stages, warps, and K width. The native implementation handles asynchronous staging, matrix instructions, and distributed shared-memory reduction. It is specialized to its supported small-token region. Before dispatching it, the applicability logic checks dimension and resource conditions. The wrapper is short, but the native kernel it invokes embodies a substantial amount of architecture-specific work. Pause the video to compare the address expressions and parameter names with the full source. The displayed window is an exact excerpt, not pseudocode; the commentary explains its role within the complete method.
_cluster_ext
This source window is cluster ext. The extension builder derives the set of required template instances from the plan, generates dispatch code, hashes the resulting source, and compiles it through PyTorch's inline extension mechanism. That source-derived name helps tie a compiled artifact to its implementation. Compilation is outside the timed graph but inside the run's lifecycle and limits. Too many speculative instances can consume setup time without contributing to the selected path. This is why a broad native search and a production submission should not automatically compile the same enormous collection of variants. Pause the video to compare the address expressions and parameter names with the full source. The displayed window is an exact excerpt, not pseudocode; the commentary explains its role within the complete method.
m_c7_lt
This source window is m c7 lt. The library wrapper chooses the selected operand orientation and algorithm index. For swapped-output paths with an unsuitable token leading dimension, it routes to the preserved fallback. Otherwise it allocates the requested physical output layout, invokes the native library extension with workspace, and returns either the direct output or a transposed view. The mathematical result has the required logical shape even when its physical layout differs. That flexibility is useful, but the alignment fallback is part of the design rather than an optional afterthought. Pause the video to compare the address expressions and parameter names with the full source. The displayed window is an exact excerpt, not pseudocode; the commentary explains its role within the complete method.
choose
This source window is choose. The policy scans the layer's ordered token limits and selects the first matching method. It then checks whether the method applies to the actual dimensions and parameters. If not, it uses the appropriate safe route. The plan is therefore interpretable: each region has a method and parameter tuple that can be traced to a measurement. This structure supports nearby shapes without reading activation values. A reviewer should inspect both the selected plan entries and the applicability checks before concluding the dispatch is general and correct. Pause the video to compare the address expressions and parameter names with the full source. The displayed window is an exact excerpt, not pseudocode; the commentary explains its role within the complete method.
kernel_fn
This source window is kernel fn. The timed entry point extracts the fresh input and supplied configuration, obtains layer and dimensions, asks the policy to choose a method, and returns that method's result. There is no reference import, network request, or output replay. The graph can reuse execution structure while consuming new input values. This separation makes the selected algorithms testable and the overall call capturable. It also makes source identity important: changing a plan entry can change performance while leaving this entry point visually identical. Pause the video to compare the address expressions and parameter names with the full source. The displayed window is an exact excerpt, not pseudocode; the commentary explains its role within the complete method.
prepare
This source window is prepare. The final preparation definition in the winning source wraps earlier preparation functions and ensures the library workspace and transposed dense layouts exist. The source contains several preparation definitions because the experimental fragments build on earlier functions. Python's final binding is the effective entry point, while captured aliases preserve the earlier layers. Reading only the first definition would therefore miss some static work. The exact source is preserved so this composition can be inspected rather than simplified retrospectively into a version that was never the one evaluated. Pause the video to compare the address expressions and parameter names with the full source. The displayed window is an exact excerpt, not pseudocode; the commentary explains its role within the complete method.
Appendices · Definitions and notation / 60
Appendix E · The glossary#
If an abbreviation stopped making sense, start here. This glossary gives the term a job in the story instead of expecting you to know it already.
Token
A token is an item in the model’s discrete input or output sequence. It may correspond to a word fragment, a word, punctuation, or another learned text unit. Token count becomes a tensor dimension, so it directly influences the geometry and parallelism of the kernels. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Parameter
A parameter is a learned model value that is normally static during inference. My projection weights are parameters. Static preparation can rearrange their storage for repeated use, while preserving the values and precision required by the task. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Activation
An activation is a value computed for a particular input as it moves through the model. Activations change across evaluated calls. A valid submission must compute fresh outputs from those new values rather than cache an answer from an earlier invocation. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Prefill
Prefill processes a block of new prompt tokens. Compared with one-token decode, it exposes more token rows and opportunities to reuse weights. The competition gives prefill its own workload and board, separate from the overall decode ranking. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Decode
Decode produces the next token in autoregressive generation. One request exposes a small amount of new token work but may read a long cached history. The small projection token dimension makes movement and launch overhead especially important. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Verification block
A verification block lets the main model check several draft tokens from speculative generation. The specified workload uses blocks of eight. Multiplying requests by block length gives the effective projection token count, while attention remains causal inside the block. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Tensor parallelism
Tensor parallelism partitions tensor computation across devices, for example by output features or a reduction dimension. Local matrix shapes reflect that partition. Partial outputs may require communication in real serving even when the isolated kernel task simplifies that communication. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Expert parallelism
Expert parallelism places different experts on different devices. In the supplied workload, one GPU holds 32 of 256 experts and computes only local routes. Uneven expert popularity creates irregular local batches. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
GEMM
GEMM is the conventional name for general matrix multiplication. My projection is input times transposed weights. The same algebra can be implemented through many tile layouts, instruction schedules, and library algorithms, so GEMM does not identify one universal kernel. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
GEMV
GEMV is general matrix-vector multiplication. A one-token projection resembles this regime. Direct streaming reductions can be competitive because there are few token rows over which to amortize a large matrix tile or reuse weights. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Stride
A stride describes how far memory addresses move when a tensor index advances. Shape and stride together define the mapping from logical indices to stored values. A transposed view changes that mapping without necessarily moving data. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Packed layout
A packed layout rearranges values into a representation designed for a kernel’s access pattern. My pooler packing preserved every BF16 value and grouped output-feature tiles into contiguous K-by-tile regions. Preparation paid the static rearrangement cost. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Coalescing
Coalescing is the efficient combination of nearby lane memory requests into useful transactions. Access size, alignment, and address distribution matter. It is a property of the actual memory pattern, not merely whether the source code uses the word vector. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
HBM
High bandwidth memory holds large GPU tensors such as model weights. Its capacity determines what can fit, while bandwidth and latency determine the cost of accessing it. A matrix can fit easily and still take substantial time to stream. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
L2 cache
L2 is a device-level cache between execution resources and external memory. Reuse can reduce external traffic. The judge deliberately begins timed replays with cold-cache conditions so accidental repeated use of one resident weight copy does not define the score. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Streaming multiprocessor
A streaming multiprocessor is a GPU execution unit that hosts blocks and warps and provides instruction and storage resources. A grid with too little independent work can leave many such units underused even if each active block has a long reduction. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Warp
A warp contains 32 lanes that execute instructions under participation masks. Tensor fragments and reductions are distributed across those lanes. Changing warp count changes the work distribution and resource balance, not just a cosmetic launch setting. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Thread block or CTA
A thread block, also called a cooperative thread array, is a group of threads scheduled together with shared-memory access and block synchronization. Its tile ownership and resource requirements influence grid parallelism and residency. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Register
A register holds thread-local state close to execution resources. Accumulators, addresses, metadata, and decoded values all compete for registers. Excessive register demand can reduce the number of resident warps or introduce spilling. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Shared memory
Shared memory is explicitly managed storage accessible within a block. It supports tile staging and reuse before matrix instructions. Its finite capacity means larger tiles and deeper pipelines can reduce resident work. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Bank conflict
Shared-memory accesses map onto banks. Certain patterns make lanes contend for bank resources. A swizzle rearranges addresses so the intended matrix-load pattern can interact more favorably with those banks without changing the mathematical values. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Occupancy
Occupancy describes resident warp capacity relative to hardware limits. Registers, shared memory, threads, and block limits affect it. It is a diagnostic quantity: maximizing occupancy alone does not guarantee the highest useful throughput. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Tensor core
A tensor core accelerates supported small matrix multiply-accumulate operations. It requires particular operand formats and fragment layouts. The surrounding kernel must feed it efficiently, and padded or skinny shapes can reduce useful work per instruction. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
MMA
MMA means matrix multiply accumulate. In the selected QKV kernel, warp-level synchronous MMA updates FP32 accumulators from BF16 operands. It is distinct from a complete GEMM implementation, which also moves and organizes data. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
cp.async
The asynchronous copy mechanism used by my custom QKV kernel transfers global data into shared staging. Committed copy groups and waits coordinate when tiles become safe to consume. Correct slot reuse and synchronization are essential. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Distributed shared memory
Distributed shared memory lets cooperating Hopper blocks in a cluster access peer shared-memory regions. My selected QKV path used it to combine split-K partials after a cluster synchronization, avoiding a separate global reduction launch. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
TMA
The tensor memory accelerator supports bulk tensor movement on Hopper. It can be part of a sophisticated pipeline, but it does not by itself ensure good tile reuse, occupancy, or arithmetic scheduling. My separate tested TMA path did not establish a useful win. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
WGMMA
Warp-group matrix multiply accumulate is a Hopper mechanism involving a larger cooperative execution group. It can support advanced designs but was not the arithmetic path of my selected synchronous-MMA QKV kernel. Capabilities and implemented results must remain distinct. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Split-K
Split-K partitions the reduction dimension among blocks that contribute to the same output tile. It creates more independent work but requires combination through scratch reduction, atomics, or another synchronization design. The complete tradeoff determines whether it helps. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Atomic addition
Atomic addition coordinates conflicting updates to one memory location so contributions are not lost through ordinary overwrite races. It does not impose one fixed floating-point arrival order. The output must also have the correct initial value. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Barrier
A barrier coordinates participating work so required values are ready before consumers proceed. Block and cluster barriers have different scopes. A barrier can protect correctness and lifetime while also adding a performance cost that must be repaid. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
CUDA graph
A CUDA graph captures execution structure for replay. Reusing the graph does not mean reusing evaluated answers. The challenge supplies fresh inputs and measures captured calls, so graph replay correctness and performance are central to the workload. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Cold L2
Cold L2 describes the benchmark condition created by displacing useful cache contents before a replay. It reduces accidental warm-weight advantages. It is part of the evaluation method, not a claim that all real production calls always have identical cache state. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Relative L2 error
Relative L2 error compares the norm of an output difference with the norm of the reference. The task adds row-level and sparse-probe safeguards, so passing a single global average is not a complete description of correctness. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
BF16
BF16 stores a sign, eight exponent bits, and seven fraction bits. It has a broad exponent range but less precision than FP32. My dense projection operands keep their original BF16 values, with FP32 accumulation in selected kernels. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
FP32
FP32 stores a sign, eight exponent bits, and 23 fraction bits. The router’s original weights and required output use this type. Dense kernels also use it for accumulators and split reductions before converting to their required output. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
FP8 cache
The attention cache uses its specified eight-bit floating-point representation and scales. This is an attention contract. It does not authorize replacing dense projection weights with FP eight or ignoring the cache’s format and scaling during a fusion. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
NVFP4
The routed-expert weights use the specified low-bit format and associated scaling structure. Efficient dequantization is part of that workload. It is separate from the dense projection contract, where arbitrary four-bit approximation of BF16 weights is not allowed. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Arithmetic intensity
Arithmetic intensity is useful floating-point operations divided by moved bytes under a stated traffic model. For my weight-only BF16 projection approximation it is roughly M. Real activation, output, scratch, and repeated reads can change it. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Roofline
A roofline combines a bandwidth-limited throughput slope with an arithmetic ceiling. It is a model of optimistic bounds under assumptions. Practical kernels generally sit below it because scheduling, movement patterns, synchronization, and other costs remain. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Latency
Latency measures how long an operation or request takes to complete. It includes dependencies and waiting along the relevant path. A higher aggregate throughput configuration can still increase one user’s latency if it waits for larger batches. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Throughput
Throughput measures completed useful work per unit time. Serving can report tokens per second per GPU or per user. Those quantities answer different questions, and the competition evaluates multiple concurrency levels to capture the tradeoff. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Geometric mean
A geometric mean multiplies positive ratios and takes the root corresponding to their count. The projection problem uses six load ratios. Weighted shape times are summed inside each load before that geometric aggregation. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Amdahl’s law
Amdahl’s law relates a component speedup to its share of total time. If the remaining work is unchanged, it limits total improvement even when the selected component becomes extremely fast. It guides prioritization of attainable absolute savings. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Median
A median is the middle sorted observation. It is less sensitive to a few outliers than a mean. The judge summarizes paired ratios with medians rather than reward the fastest isolated repetition. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Confidence interval
A confidence interval reports uncertainty under the evaluator’s statistical method. It should accompany the point estimate. An upper endpoint above a desired threshold does not establish that the threshold was achieved by the recorded score. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Official check
An official check runs the evaluation off the leaderboard and has its own allowance. It is valuable evidence for validation and selection. It remains distinct from an independently scored submission even when their source bytes match. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Scored submission
A scored submission is an official leaderboard attempt. Its result belongs to a particular source and job identifier. A later file or a local timing cannot silently replace that identity when explaining what achieved the recorded milestone. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Source hash
A source hash identifies the exact bytes of a file. It helps connect an immutable candidate with compiled artifacts, job results, and archives. It does not prove correctness by itself, but it prevents a result from drifting onto different code. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Preparation state
Preparation state stores static original or losslessly transformed weights, algorithm metadata, workspace, and permitted scratch. It cannot store answers derived from evaluated inputs for reuse. The timed call must still compute fresh required outputs. Keep this definition connected to the corresponding chapter and the actual operation on screen. A familiar term can describe different implementation choices, so always ask which values, scope, and measurement it refers to here.
Appendices · What each artifact establishes / 61
Appendix F · Provenance and limitations#
These are the boundaries of what the saved results support, plus how the original video was produced. I kept this detail here rather than interrupt the main story.
The winning source
The preserved winning file is experiment 036, streaming vector. The snapshot manifest records its hash and the exact scored job. The current project submission was promoted from those bytes, with the previous source retained. The documentary includes a read-only copy in its evidence directory so code explanations can be checked independently. Future edits should become new candidates rather than rewrite the identity of the old result. The accompanying files let you audit the scope of the claim rather than rely on the narration alone. When evidence is missing or a proposal was never validated, the correct conclusion is to keep that uncertainty visible.
The official score
The scored result JSON records passed status, the speedup point estimate, its interval, aggregate values, machine information, and detailed records. The documentary exports the relevant summary and thirty projection cases without inventing missing values. A viewer should distinguish those raw artifacts from the explanatory diagrams, whose small matrix tiles and simplified memory paths are conceptual illustrations. The accompanying files let you audit the scope of the claim rather than rely on the narration alone. When evidence is missing or a proposal was never validated, the correct conclusion is to keep that uncertainty visible.
The experiment ledger
The ledger contains checks and scored submissions across several problems. It also contains entries whose stored status was not finalized at a particular extraction point. The atlas labels that limitation rather than manufacture a score. Numbered source files with no linked run are presented as prepared artifacts. This preserves the difference among writing, launching, completing, and validating an experiment. The accompanying files let you audit the scope of the claim rather than rely on the narration alone. When evidence is missing or a proposal was never validated, the correct conclusion is to keep that uncertainty visible.
Narrative reconstruction and attribution
The story uses code, result files, research notes, and handoffs to reconstruct the decision sequence. It does not claim access to private unrecorded reasoning. Where a handoff establishes provenance, that contribution can be attributed. Where an explanation is a plausible mechanism without counter evidence, it is labeled accordingly. This makes the narrative useful without presenting a dramatized conversation as a historical transcript. The accompanying files let you audit the scope of the claim rather than rely on the narration alone. When evidence is missing or a proposal was never validated, the correct conclusion is to keep that uncertainty visible.
Voice and caption provenance
The opening and selected experiment-story chapters use the requested Liam voice within the available ElevenLabs credit budget. The remaining narration uses the locally available Daniel voice, as I approved. ElevenLabs clips use returned character timing for captions. Local clips use estimated caption timing derived from their duration, so those subtitles are approximate. Audio is cached independently of rendering to prevent a layout change from creating another paid voice request. The accompanying files let you audit the scope of the claim rather than rely on the narration alone. When evidence is missing or a proposal was never validated, the correct conclusion is to keep that uncertainty visible.
Time-sensitive information and costs
Competition schedules, allowances, rankings, service capabilities, and prices can change. The documentary presents the schedule and dated rankings checked for this project and the recorded bill for the specific pod. It does not imply those prices or ranks are permanent. Reproduction should recheck the current official rules and account state. The operational lesson is to preserve evidence and verify resource shutdown rather than leave paid allocation waiting after useful work ends. The accompanying files let you audit the scope of the claim rather than rely on the narration alone. When evidence is missing or a proposal was never validated, the correct conclusion is to keep that uncertainty visible.
Organizers, prizes, and queue priority
The official overview presents the challenge under Meta, Paradigm, and Andromeda branding. It lists 100,000 dollars in serving prizes: 50,000 for first, 30,000 for second, 10,000 for third, 3,000 for fourth, 2,000 for fifth, and 1,000 each for sixth through tenth. First place also lists a signed H200. The rules state that the top fifty on the overall kernel leaderboard at the kernel close receive serving queue priority. That is the overall kernel board, not merely a top-fifty position on my projection problem. This distinction changes how someone should plan a competition strategy.
Serving submission boundaries
The serving rules specify modifying SGLang at the stated day-zero-support commit and submitting a source diff. Allowed changes are restricted to the permitted SGLang source and JSON configuration area, with model-loader restrictions and patch-size limits. The prebuilt kernel binaries are not rebuilt. The model must preserve its required expert count, attention window, normalizations, parameter structure, activation and cache formats, and released drafter behavior. Requests must return the specified token count. These constraints explain why serving optimization is an implementation problem, not permission to substitute a smaller model or reduce the workload.
Historical limits and final review
The kernel rules list separate daily submission and check allowances, resetting at midnight UTC, and state that limits may change with service load. The project queried the live CLI rather than assume a remembered quota was permanent. Serving has separate allowances and longer whole-node evaluations. Final review can rerun leading entries, including held-out inputs and nearby shapes, and positions remain provisional until that review. A leaderboard point is therefore evidence from an evaluated run, while the final competition outcome still depends on the stated review process.
License and upstream intent
The terms state that submitted code is licensed under Apache License 2.0 and that participants confirm the right to submit it. The rules describe upstreamable real improvements as the purpose of the challenge. This is another reason to preserve supported library use, general shape behavior, and a reproducible implementation rather than optimize around an accidental evaluator loophole. This written companion explains the technical project; anyone entering the competition should read and accept the current official terms themselves rather than treat a video summary as a substitute.
Appendices · Active recall and reasoning / 62
Appendix G · Pause and predict#
Try predicting the next decision before reading the answer. These questions revisit the tradeoffs from the rest of the notes.
Exercise 01 · predict, then explain
Exercise for chapter 1, The run that crossed 1.30×. A local test says 1.3234×. Has the 1.32× official target been achieved? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. No. A local comparison is evidence for a candidate. The official scored source must reach the target under the competition evaluation. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 02 · predict, then explain
Exercise for chapter 2, What the competition actually asks. Does a high kernel ranking itself award the serving cash prize? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. No. The kernel and serving stages have distinct roles. Kernel standings can provide serving queue priority; the cash prizes belong to serving. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 03 · predict, then explain
Exercise for chapter 3, The complete competition map. Can a better expert score replace the projection goal? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. No. Each score belongs to its defined problem. A separate expert improvement is valuable but does not establish the projection threshold. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 04 · predict, then explain
Exercise for chapter 4, From a message to generated tokens. Why can one new token still require substantial memory work? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. The new activation is small, but it can read large learned weights and a long cached attention history. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 05 · predict, then explain
Exercise for chapter 5, Inside the transformer layer. Can per-expert normalization move after the weighted expert sum? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. Not in general. Normalization is nonlinear and the specified dependency places it on each expert output before combination. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 06 · predict, then explain
Exercise for chapter 6, Prefill, decode, and verification. What effective projection M comes from sixteen requests verifying eight tokens? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. 128 token rows. The attention remains causal within the eight-token block. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 07 · predict, then explain
Exercise for chapter 7, One GPU inside an eight-GPU model. Does omitting collectives in a kernel test make real serving communication free? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. No. The isolated contract simplifies communication. Full serving must measure actual transfers, synchronization, and scheduling. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 08 · predict, then explain
Exercise for chapter 8, The software stack beneath SGLang. An advanced library call fails its operand-rank requirement. Is that a slow-kernel result? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. No. It is an integration failure. Repair the interface and pass correctness before drawing a performance conclusion. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 09 · predict, then explain
Exercise for chapter 9, The mathematics of my projection. Does a transposed view necessarily copy matrix values? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. No. A view can change strides without moving data. A contiguous transpose physically rearranges the representation. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 10 · predict, then explain
Exercise for chapter 10, The exact projection workload. Why does a one-microsecond router saving count like a one-microsecond pooler saving within one load? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. The load adds weighted times. With equal listed weights, the same absolute time saving has the same immediate contribution to that sum. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 11 · predict, then explain
Exercise for chapter 11, Numerical formats and error. Does a BF16 output dtype prove the split reduction used FP32? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. No. Operand, accumulator, reduction, and output precision are separate choices. Inspect the algorithm configuration and validate the result. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 12 · predict, then explain
Exercise for chapter 12, Why the router needs special care. Why not use only the router’s BF16 high part? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. It loses weight detail beyond the allowed high-plus-low scheme and can fail the tighter router and sparse-probe checks. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 13 · predict, then explain
Exercise for chapter 13, A guided tour of the H200. If weights fit in HBM, is reading them essentially free? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. No. Capacity and bandwidth are different. A resident matrix still takes time to stream to execution resources. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 14 · predict, then explain
Exercise for chapter 14, Threads, warps, blocks, and scheduling. Will doubling warps per block always improve a kernel? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. No. Warp count changes register distribution, residency, memory behavior, and reduction structure. My 32-warp candidate regressed. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 15 · predict, then explain
Exercise for chapter 15, The journey of a byte. Does fewer kernel launches guarantee lower total time? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. No. Fusion can add synchronization, resource pressure, or insufficient parallelism. Time the complete captured path. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 16 · predict, then explain
Exercise for chapter 16, Coalescing, tiling, and weight layout. Why test an odd token count near a winning swapped-output case? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. Because the output leading dimension may change alignment. A nearby odd count can expose a severe regression or masking bug. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 17 · predict, then explain
Exercise for chapter 17, Tensor cores and matrix instructions. Does adding tensor-core instructions guarantee beating cuBLAS? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. No. The kernel must still move operands, fill useful tiles, schedule work, and manage resources better than the library for that shape. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 18 · predict, then explain
Exercise for chapter 18, Rooflines and practical limits. Is a theoretical roofline point a measured attainable kernel time? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. No. It is an optimistic bound under assumptions. Practical movement, launch, synchronization, and scheduling costs remain. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 19 · predict, then explain
Exercise for chapter 19, Split-K and the cost of combining work. What does split-K add besides parallelism? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. It adds a combination problem: partial traffic, a reduction launch, atomics, counters, or cluster synchronization, depending on the design. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 20 · predict, then explain
Exercise for chapter 20, Hopper pipelines and block clusters. Did the selected custom QKV kernel use WGMMA? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. No. Its documented path used asynchronous staging, ldmatrix, warp-level mma.sync, and distributed shared-memory cluster reduction. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 21 · predict, then explain
Exercise for chapter 21, The submission contract. May preparation cache outputs from evaluated activations? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. No. Static preparation receives weights. Fresh evaluated inputs must produce fresh outputs in the timed computation. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 22 · predict, then explain
Exercise for chapter 22, What correctness really tests. Why replay a captured graph on new input values? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. To expose stale outputs, scratch state, or counters that accidentally make capture-time or first-call results persist. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 23 · predict, then explain
Exercise for chapter 23, How the judge times a kernel. Why alternate baseline-first and candidate-first measurements? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. Swapped-order pairs help cancel simple order effects and provide stronger evidence than unrelated best-case timings. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 24 · predict, then explain
Exercise for chapter 24, How thirty timings become one score. What is the geometric mean of speedups 2, 1, and 0.5? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. One. Their product is one. An arithmetic average would report a different and misleading aggregate for this purpose. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 25 · predict, then explain
Exercise for chapter 25, Noise, uncertainty, and moving ranks. If a confidence interval reaches 1.32×, can the point estimate be advertised as 1.32×? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. No. Report the recorded point estimate and interval. A preferred endpoint is not the achieved scored result. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 26 · predict, then explain
Exercise for chapter 26, Building an auditable investigation. Why preserve slower experiments? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. They constrain future hypotheses, prevent repeated dead ends, and explain which evidence changed the investigation’s direction. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 27 · predict, then explain
Exercise for chapter 27, A correct kernel that lost. The first custom kernel passes correctness at 0.7761×. What kind of failure is that? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. A performance loss, not an arithmetic failure. The next hypothesis should examine execution, such as insufficient independent work. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 28 · predict, then explain
Exercise for chapter 28, Split the router: my first useful win. Why did splitting the router deserve a test despite extra traffic? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. The additional blocks could improve utilization enough to repay partial storage and final reduction overhead. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 29 · predict, then explain
Exercise for chapter 29, Learning to dispatch by shape. Why select methods by layer and token range? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. Different shapes expose different grid sizes, reuse, and overhead. A policy can combine useful regimes while retaining strong library paths. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 30 · predict, then explain
Exercise for chapter 30, Packed router: reaching 1.1555×. What does the early packed router concatenate? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. It concatenates transposed high and low output-column regions, computes both products, and adds corresponding regions in FP32. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 31 · predict, then explain
Exercise for chapter 31, The attention side story. Does the attention component ratio multiply directly with the projection ratio? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. No. Whole-layer or serving improvement depends on original time shares, compatible integration, and the complete workload. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 32 · predict, then explain
Exercise for chapter 32, The routed-expert side story. Why can less expert padding still lose? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. A smaller or different grouping can reduce arithmetic waste while worsening tensor-core efficiency, scheduling, or launch behavior. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 33 · predict, then explain
Exercise for chapter 33, Why whole-layer gains were smaller. Why was the whole-layer result smaller than some component results? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. The larger workload has its own dominant time shares and integration costs. It must be measured independently. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 34 · predict, then explain
Exercise for chapter 34, Transposes, wider K, and QuACK detours. Why distinguish repaired QuACK runs from the first failed attempts? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. Only the repaired interface reached valid correctness and timing. The earlier failures do not establish library performance. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 35 · predict, then explain
Exercise for chapter 35, Systematic vector and library searches. Why retime finalists after a broad search? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. Selecting the best noisy observation can favor luck. More paired repetitions and nearby-shape tests reduce that selection risk. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 36 · predict, then explain
Exercise for chapter 36, Composing gains into 1.1993×. Does combining correct functions make the bundle automatically a proven win? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. No. Preparation, dispatch, layout, and complete timing can change. The combined source needs fresh validation and evaluation. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 37 · predict, then explain
Exercise for chapter 37, The handoff and the measured best-of plan. What makes a handoff useful? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. Exact sources, commands, environment, measured outcomes, failed branches, and proposals labeled as untested rather than mixed with achievements. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 38 · predict, then explain
Exercise for chapter 38, Atomic router: reaching 1.2785×. Does the atomic router eliminate output initialization? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. No. The selected wrapper supplies a fresh zeroed FP32 output. Removing the dedicated reduction does not make zeroing free. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 39 · predict, then explain
Exercise for chapter 39, The small unpooler opportunity. Why did tinygemm target the small unpooler? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. The task’s small-token local output slice has a much smaller geometry and can favor a low-overhead specialized path. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 40 · predict, then explain
Exercise for chapter 40, Custom cluster QKV: reaching 1.2888×. How does the cluster QKV path combine partials? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. Blocks write FP32 shared-memory partials, synchronize the cluster, read peer values, and store final BF16 outputs with protected lifetime. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 41 · predict, then explain
Exercise for chapter 41, Building my remote H200 laboratory. A pod reports running. Is the experiment environment verified? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. Not yet. Confirm actual access, GPU visibility, versions, and workload execution, and preserve the evidence. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 42 · predict, then explain
Exercise for chapter 42, The packed pooler experiment. Did packed pooler weights change BF16 values? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. No. The selected representation reorders original values into output-feature tiles. Dequantization or approximate replacement was not used. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 43 · predict, then explain
Exercise for chapter 43, Exploring cuBLASLt orientations. Why was the swapped-output library fallback important? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. Its leading dimension depends on M. The fallback protects cases whose alignment does not suit the selected orientation. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 44 · predict, then explain
Exercise for chapter 44, Lossless compression: fewer bytes, slower execution. Why can lossless compression be slower than original weights? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. Metadata, decode instructions, escapes, and resource pressure can exceed the memory time saved by fewer stored bytes. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 45 · predict, then explain
Exercise for chapter 45, Router redesigns that did not help. Does a last-arriving-block reduction remove all combination costs? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. No. It still writes partials, coordinates completion, reads them back, sums them, and resets state correctly. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 46 · predict, then explain
Exercise for chapter 46, Advanced features that still lost. Does TMA appearing in source prove an optimization? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. No. Its complete pipeline must still outperform the incumbent under valid captured measurements. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 47 · predict, then explain
Exercise for chapter 47, The final single-token streaming gain. Which final single-token settings were included? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. The selected QKV and pooler entries used one output row per block, sixteen warps, and .cg weight loads. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 48 · predict, then explain
Exercise for chapter 48, Read the winning implementation end to end. Is the final submission one universal kernel? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. No. It is a documented per-layer and token-range policy over vector, packed Triton, custom cluster, tinygemm, and library paths. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 49 · predict, then explain
Exercise for chapter 49, Local 1.3234×, official 1.3012×. Which result controls the official ending: 1.3234× local or 1.3012× scored? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. The scored official result. The local number remains useful evidence for investigation and an explicit measurement discrepancy. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 50 · predict, then explain
Exercise for chapter 50, What crossing 1.30× established. Does 1.3012× mean thirty percent less time? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. No. Time reduction is one minus the reciprocal, about twenty 3.15 percent. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 51 · predict, then explain
Exercise for chapter 51, The epilogue: tuning can regress. Why retain experiment 036 after candidate 038 passed correctness? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. Correctness alone is not a performance win. Candidate 038’s official check regressed, while 036 was the scored incumbent. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 52 · predict, then explain
Exercise for chapter 52, The remaining road to 1.32×. Can a very small gain in one isolated shape close the full target gap automatically? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. No. Its contribution is diluted by its load time share and the six-load geometric aggregation. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 53 · predict, then explain
Exercise for chapter 53, From kernel wins to serving wins. Can maximizing tokens per second worsen a user’s experience? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. Yes. Waiting for larger batches can raise throughput while increasing per-user latency or time to first token. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 54 · predict, then explain
Exercise for chapter 54, Reproduce and audit the result. What must be copied before terminating a remote lab? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. The required source and experiment evidence. Termination can destroy retained disk state, so synchronize and verify resource lifecycle actions. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Exercise 55 · predict, then explain
Exercise for chapter 55, The decision-making playbook. What is the reusable loop behind the project? Pause here and make a prediction before continuing. State the reason for your answer, not just yes or no. Now compare it with the recorded lesson. Define the contract, model the cost, measure a bottleneck, test a hypothesis, validate, compare independently, preserve evidence, and finish the resource lifecycle. The useful habit is to connect your conclusion to the numerical contract, execution mechanism, or evidence that resolves the question. If your prediction differed, revisit the corresponding chapter and identify which assumption changed.
Postscript · A later result arrived during production / 63
Postscript · The official 1.3234× result#
The later candidate really did score 1.3234× officially. It used different code from the earlier local run with the same rounded number. Here's what changed.
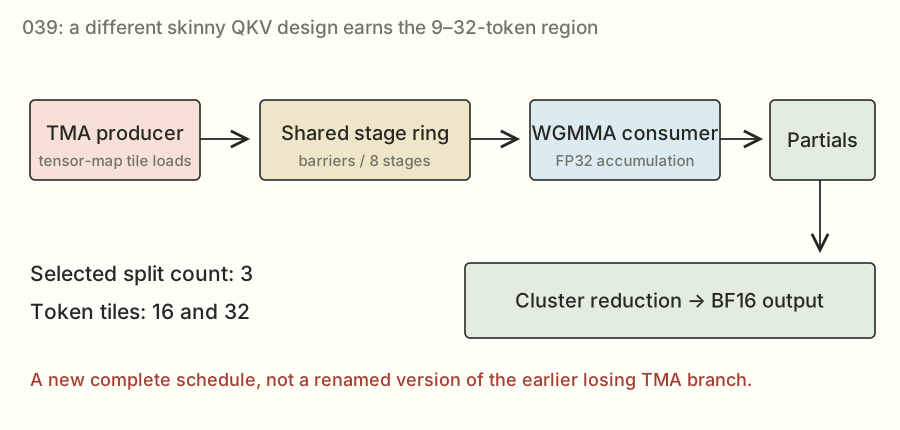
A new official result arrives
There is a later development. While this written companion was being produced, the project recorded a newer projection submission that independently scored 1.32343. Its official check had returned 1.3218. Both passed, and the live board showed the new result at rank 66 at the time of my read. This clears the 1.32 point-estimate target discussed in the earlier chapters. The main film reconstructs the preserved 1.30 milestone; this postscript records the subsequent step with separate evidence.
Same rounded number, different evidence
The rounded number 1.3234 may look familiar. Earlier in the article, that was a local measurement of candidate 036, whose official score was lower. The newer 1.3234 is an official result for candidate 039. They are different candidates and different evaluations. The earlier local result did not retroactively become official. A new scored job supplies new evidence. This distinction is exactly why I preserved source identities, measurement labels, and job records throughout the story.
Three additions in the newer source
The saved build script describes three measured additions on top of the lean-preparation base. It uses programmatic dependent launch for the router's initialization and compute path. It selects expanded library configurations for QKV at 128 tokens and pooler at 256. It also adds a different skinny QKV kernel using tensor memory transfers, warp-group matrix operations, and cluster reduction for the selected nine-through-32-token range. This is not the same TMA implementation that lost in the earlier round. A failed earlier design did not prove every more complete later design would fail.
PDL preserves a correctness boundary
The router still needs a fresh zero output before atomic additions. Programmatic dependent launch gives the following kernel an opportunity to begin independent work before the zero-fill predecessor has fully completed. The router can perform loads and product work, then waits before its output atomics depend on the initialization. This does not make the dependency disappear, and concurrent execution is opportunistic rather than guaranteed. The source explicitly signals dependent launch and waits at the dependent-write boundary. The relevant NVIDIA documentation is linked with the postscript sources.
The later skinny kernel is a new design
The new skinny path uses a producer and consumer organization, tensor-map loads, shared staging barriers, warp-group matrix accumulation, and cluster cooperation to finish split contributions. Its instantiated configurations use three-way split work and an eight-stage pipeline for the selected token tiles. The complete design differs from the earlier simple TMA descriptor experiment and from the old warp-level MMA QKV path. The source supports the explanation of its mechanism, while the bundled official result establishes the new submission's aggregate outcome. Assigning an exact isolated causal percentage to each addition would require the corresponding controlled comparisons.
Library indices and neighboring routes
The source also selects expanded cuBLAS Lt enumerations at particular matrix shapes where those indices were measured. Nearby shapes retain earlier routes, and swapped-output alignment has a fallback. The index is an entry in a shape-specific enumeration, not an architecture-independent algorithm name. This explains why the newer source guards its selected choices rather than applying one integer across an arbitrary token range. The implementation remains subject to the competition's final review and neighboring-shape expectations, just like the earlier submissions.
The new result and its uncertainty
The newer scored point estimate is 1.323430, with a reported interval of roughly 1.3036 to 1.3433. Its independent check is also above 1.32. Relative to the earlier 1.3012 scored point, the new ratio is about 1.0171. These are recorded outcomes from separate runs, so I retain the uncertainty rather than claim every last decimal is a precisely isolated causal effect. The target crossing itself is visible in the passing official result and the board.
An updated ending, with the history intact
The main investigation still explains how the project reached 1.30. This later result extends that history rather than rewriting the earlier local measurement or erasing rejected experiments. It reinforces the central lesson: preserve what an experiment actually tested, and let new implementations create new evidence. The documentary includes the later source, both result files, and the dated board read in a separate postscript folder. You can audit the original milestone and the subsequent 1.32 target crossing without confusing their code or measurements.